P.S. Kostenlose 2026 Snowflake ARA-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertPruefung verfügbar: https://drive.google.com/open?id=1gr5vSRMEm-pThHq099JuAac3DUlBYG7X
Wissen Sie Snowflake ARA-C01 Dumps von ZertPruefung? Warum sind diese Dumps von den Benutzern gut bewertet? Wollen Sie diese Dumps probieren? Klicken Sie bitte ZertPruefung Website und die Demo herunterladen. Und jedr Fragenkatalog hat eine kostlose Demo. Wenn Sie es gut finden, können Sie diese Dumps sofort kaufen. Nach dem Kauf können Sie auch einen einjährigen kostlosen Aktualisierungsservice bekommen. Innerhalb eines Jahres können Sie die neuesten Snowflake ARA-C01 Prüfungsunterlagen besitzen. Damit können Sie Snowflake ARA-C01 Zertifizierungsprüfung sehr leicht bestehen und dieses Zertifikat bekommen.
| Section | Weight | Objectives |
|---|---|---|
| Performance Optimization | 20% | - Virtual warehouse configuration and sizing - Clustering and partitioning strategies - Cost optimization and resource management - Query performance tuning |
| Snowflake Architecture | 30% | - Data modeling and use cases - Data sharing architecture design - Data protection and recovery strategies - Object hierarchy and architectural impact - Development lifecycle and workload support |
| Accounts and Security | 25% | - Security principles and implementation scenarios - Account and database strategy design - Security, compliance and governance architecture |
| Data Engineering | 25% | - Transformation and processing frameworks - Data loading and unloading solutions - Data pipeline and integration design |
Wollen Sie Ihre IT-Fähigkeiten in kürzester Zeit erhöhen, aber zugleich sorgen Sie noch darum, dass Ihnen geeignete Lernmaterialien fehlen? Machen Sie jetzt keine Sorgen, denn solange Sie über die Fragenkataloge zur Snowflake ARA-C01 Zertifizierungsprüfung von ZertPruefung verfügen, können Sie mit jeder IT-Prüfung leicht fertig werden. Unsere Fragenkataloge zur Snowflake ARA-C01 Zertifizierungsprüfung sind von den erfahrenen IT-Experten durch langjährige ständige Untersuchung und Erforschung bearbeitet. ZertPruefung wird Ihre beste Wahl sien.
123. Frage
Following objects can be cloned in snowflake
Antwort: B,C,E
Begründung:
* Snowflake supports cloning of various objects, such as databases, schemas, tables, stages, file formats, sequences, streams, tasks, and roles. Cloning creates a copy of an existing object in the system without copying the data or metadata. Cloning is also known as zero-copy cloning1.
* Among the objects listed in the question, the following ones can be cloned in Snowflake:
* Permanent table: A permanent table is a type of table that has a Fail-safe period and a Time Travel retention period of up to 90 days. A permanent table can be cloned using the CREATE TABLE ...
CLONE command2. Therefore, option A is correct.
* Transient table: A transient table is a type of table that does not have a Fail-safe period and can have a Time Travel retention period of either 0 or 1 day. A transient table can also be cloned using the CREATE TABLE ... CLONE command2. Therefore, option B is correct.
* External table: An external table is a type of table that references data files stored in an external
* location, such as Amazon S3, Google Cloud Storage, or Microsoft Azure Blob Storage. An external table can be cloned using the CREATE EXTERNAL TABLE ... CLONE command3.
Therefore, option D is correct.
* The following objects listed in the question cannot be cloned in Snowflake:
* Temporary table: A temporary table is a type of table that is automatically dropped when the session ends or the current user logs out. Temporary tables do not support cloning4. Therefore, option C is incorrect.
* Internal stage: An internal stage is a type of stage that is managed by Snowflake and stores files in Snowflake's internal cloud storage. Internal stages do not support cloning5. Therefore, option E is incorrect.
References: : Cloning Considerations : CREATE TABLE ... CLONE : CREATE EXTERNAL TABLE ...
CLONE : Temporary Tables : Internal Stages
124. Frage
You are creating a TASK to query a table streams created on the raw table and insert subsets of rows into multiple tables. You are following the below steps, but when you reached the step to resume the task, you received an error message as below.
Why is this error thrown and who can give you the required privilege?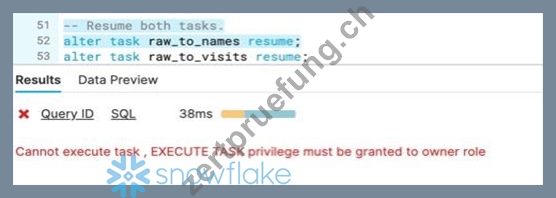
Steps to be followed to get this error
-- Create a landing table to store raw JSON data.
-- Snowpipe could load data into this table. create or replace table raw (var variant);
-- Create a stream to capture inserts to the landing table.
-- A task will consume a set of columns from this stream. create or replace stream rawstream1 on table raw;
-- Create a second stream to capture inserts to the landing table.
-- A second task will consume another set of columns from this stream. create or replace stream rawstream2 on table raw;
-- Create a table that stores the names of office visitors identified in the raw data. create or replace table names (id int, first_name string, last_name string);
-- Create a table that stores the visitation dates of office visitors identified in the raw data.
create or replace table visits (id int, dt date);
-- Create a task that inserts new name records from the rawstream1 stream into the names table
-- every minute when the stream contains records.
-- Replace the 'mywh' warehouse with a warehouse that your role has USAGE privilege on. create or replace task raw_to_names
warehouse = etl_wh
schedule = '1 minute'
when
system$stream_has_data('rawstream1')
as
merge into names n
using (select var:id id, var:fname fname, var:lname lname from rawstream1) r1 on n.id = to_number(r1.id)
when matched then update set n.first_name = r1.fname, n.last_name = r1.lname
when not matched then insert (id, first_name, last_name) values (r1.id, r1.fname, r1.lname)
;
-- Create another task that merges visitation records from the rawstream1 stream into the visits table
-- every minute when the stream contains records.
-- Records with new IDs are inserted into the visits table;
-- Records with IDs that exist in the visits table update the DT column in the table.
-- Replace the 'mywh' warehouse with a warehouse that your role has USAGE privilege on. create or replace task raw_to_visits
warehouse = etl_wh schedule = '1 minute' when
system$stream_has_data('rawstream2') as
merge into visits v
using (select var:id id, var:visit_dt visit_dt from rawstream2) r2 on v.id = to_number(r2.id) when matched then update set v.dt = r2.visit_dt
when not matched then insert (id, dt) values (r2.id, r2.visit_dt);
-- Resume both tasks.
alter task raw_to_names resume;
Antwort: B
125. Frage
An event table has 150B rows and 1.5M micro-partitions, with the following statistics:
Column NDV*
A_ID 11K
C_DATE 110
NAME 300K
EVENT_ACT_0 1.1G
EVENT_ACT_4 2.2G
*NDV = Number of Distinct Values
What three clustering keys should be used, in order?
Antwort: B
Begründung:
Comprehensive and Detailed 150 to 250 words of Explanation From Snowflake SnowPro Architect exam scope and all publicly documented material:
Clustering keys are most beneficial when they improve micro-partition pruning for common filter patterns and when the chosen columns provide a useful ordering that co-locates data. A common heuristic is to place lower- cardinality columns earlier (to quickly narrow partitions) and then add a higher-cardinality column that further reduces scanned partitions for selective access paths. Here, C_DATE has very low NDV (110), making it an excellent leading key to organize data by date and enable strong pruning for time-bound queries typical of event tables. Next, A_ID (11K) is moderate cardinality and can further segment data within a date range, helping point lookups or narrow scans by identifier. For the third key, the options force choosing between very high-cardinality event activity columns; selecting EVENT_ACT_0 (1.1G) is preferable to EVENT_ACT_4 (2.2G) because it is comparatively less distinct while still supporting additional pruning when queries filter by that attribute. This ordering aligns with Snowflake guidance: keep keys few, ordered to match common predicates, and avoid excessively high-cardinality keys unless they directly match frequent selective filters.
=========
126. Frage
A table contains five columns and it has millions of records. The cardinality distribution of the columns is shown below: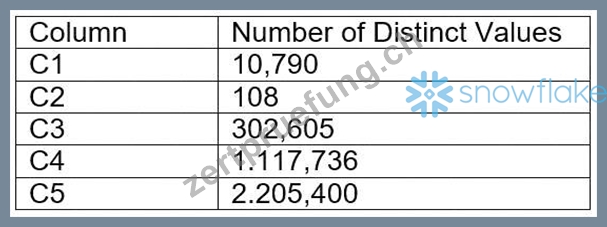
Column C4 and C5 are mostly used by SELECT queries in the GROUP BY and ORDER BY clauses.
Whereas columns C1, C2 and C3 are heavily used in filter and join conditions of SELECT queries.
The Architect must design a clustering key for this table to improve the query performance.
Based on Snowflake recommendations, how should the clustering key columns be ordered while defining the multi-column clustering key?
Antwort: C
Begründung:
According to the Snowflake documentation, the following are some considerations for choosing clustering for a table1:
* Clustering is optimal when either:
* You require the fastest possible response times, regardless of cost.
* Your improved query performance offsets the credits required to cluster and maintain the table.
* Clustering is most effective when the clustering key is used in the following types of query predicates:
* Filter predicates (e.g. WHERE clauses)
* Join predicates (e.g. ON clauses)
* Grouping predicates (e.g. GROUP BY clauses)
* Sorting predicates (e.g. ORDER BY clauses)
* Clustering is less effective when the clustering key is not used in any of the above query predicates, or when the clustering key is used in a predicate that requires a function or expression to be applied to the key (e.g. DATE_TRUNC, TO_CHAR, etc.).
* For most tables, Snowflake recommends a maximum of 3 or 4 columns (or expressions) per key.
Adding more than 3-4 columns tends to increase costs more than benefits.
Based on these considerations, the best option for the clustering key columns is C. C1, C3, C2, because:
* These columns are heavily used in filter and join conditions of SELECT queries, which are the most effective types of predicates for clustering.
* These columns have high cardinality, which means they have many distinct values and can help reduce the clustering skew and improve the compression ratio.
* These columns are likely to be correlated with each other, which means they can help co-locate similar rows in the same micro-partitions and improve the scan efficiency.
* These columns do not require any functions or expressions to be applied to them, which means they can be directly used in the predicates without affecting the clustering.
1: Considerations for Choosing Clustering for a Table | Snowflake Documentation
127. Frage
A retail company has 2000+ stores spread across the country. Store Managers report that they are having trouble running key reports related to inventory management, sales targets, payroll, and staffing during business hours. The Managers report that performance is poor and time-outs occur frequently.
Currently all reports share the same Snowflake virtual warehouse.
How should this situation be addressed? (Select TWO).
Antwort: C,E
Begründung:
The best way to address the performance issues and time-outs faced by the Store Manager team is to configure a dedicated virtual warehouse for them and make it multi-clustered. This will allow them to run their reports independently from other workloads and scale up or down the compute resources as needed. A dedicated virtual warehouse will also enable them to apply specific security and access policies for their data. A multi-clustered virtual warehouse will provide high availability and concurrency for their queries and avoid queuing or throttling.
Using a Business Intelligence tool for in-memory computation may improve performance, but it will not solve the underlying issue of insufficient compute resources in the shared virtual warehouse. It will also introduce additional costs and complexity for the data architecture.
Configuring the virtual warehouse to size 4-XL may increase the performance, but it will also increase the cost and may not be optimal for the workload. It will also not address the concurrency and availability issues that may arise from sharing the virtual warehouse with other workloads.
Advising the Store Manager team to defer report execution to off-business hours may reduce the load on the shared virtual warehouse, but it will also reduce the timeliness and usefulness of the reports for the business. It will also not guarantee that the performance issues and time-outs will not occur at other times.
References:
* Snowflake Architect Training
* Snowflake SnowPro Advanced Architect Certification - Preparation Guide
* SnowPro Advanced: Architect Exam Study Guide
128. Frage
......
Wenn Sie nicht wissen, wie man die Snowflake ARA-C01 Prüfung effizienter bestehen kann. Dann werde ich Ihnen einen Vorschlag geben, nämlich eine gute Ausbildungswebsite zu wählen. Dies kann bessere Resultate bei weniger Einsatz erzielen. Unsere ZertPruefung Website strebt danach, den Kandidaten alle echten Schulungsunterlagen zur Snowflake ARA-C01 Zertifizierungsprüfung zur Verfügung zu stellen. Die Software-Version zur Snowflake ARA-C01 Zertifizierungsprüfung hat eine breite Abdeckung und kann Ihnen eine große Menge Zeit und Energie ersparen.
ARA-C01 Schulungsangebot: https://www.zertpruefung.ch/ARA-C01_exam.html
2026 Die neuesten ZertPruefung ARA-C01 PDF-Versionen Prüfungsfragen und ARA-C01 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1gr5vSRMEm-pThHq099JuAac3DUlBYG7X