We know the certificate of Databricks-Certified-Professional-Data-Engineer exam guide is useful and your prospective employer wants to see that you can do the job with strong prove, so our Databricks-Certified-Professional-Data-Engineer study materials could be your opportunity. Our Databricks-Certified-Professional-Data-Engineer practice dumps are sensational from the time they are published for the importance of Databricks-Certified-Professional-Data-Engineer Exam as well as the efficiency of our Databricks-Certified-Professional-Data-Engineer training engine. And we can help you get success and satisfy your eager for the certificate.
| Section | Weight | Objectives |
|---|---|---|
| Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Ingestion | 15-20% | - Streaming ingestion
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
>> Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps <<
VCE4Dumps is the website that provides all candidates with IT certification exam dumps and can help all candidates pass their exam with ease. VCE4Dumps IT expert edits all-time exam materials together on the basis of flexibly using the experiences of forefathers, thereby writing the best Databricks Databricks-Certified-Professional-Data-Engineer Certification Training dumps. The exam dumps include all questions that can appear in the real exam. So it can guarantee you must pass your exam at the first time.
NEW QUESTION # 62
The data engineering team maintains the following code: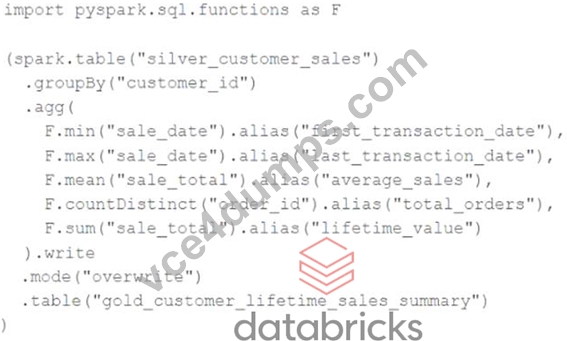
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: A
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 63
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: C
Explanation:
Comprehensive and Detailed
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 64
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Answer: B
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed. This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table12. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
The other options are not as simple or efficient as the proposed approach, because:
* Option A would require applying the churn model to all rows in the customer_churn_params table, which would be wasteful and redundant. It would also require implementing logic to perform an upsert into the predictions table, which would be more complex than using the merge statement.
* Option B would require converting the batch job to a Structured Streaming job, which would involve changing the data ingestion and processing logic. It would also require using the complete output mode, which would output the entire result table every time there is a change in the source data, which would be inefficient and costly.
* Option C would require calculating the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers, which would be computationally expensive and prone to errors. It would also require storing and accessing the previous predictions, which would add extra storage and I/O costs.
* Option D would require modifying the overwrite logic to include a field populated by calling spark.sql.
functions.current_timestamp() as data are being written, which would add extra complexity and overhead to the data engineering job. It would also require using this field to identify records written on a particular date, which would be less accurate and reliable than using the change data feed.
References: Merge, Change data feed
NEW QUESTION # 65
A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "Change data feed (CDF) provides row-level change information for Delta tables." Exact extract: "Use table_changes to query the set of rows that were inserted, updated, or deleted between two versions (or timestamps)." Exact extract: "MERGE INTO updates and inserts only the rows that changed." Overwriting the table nightly makes it difficult to isolate just the changed rows. With CDF enabled, if you update the table using MERGE so only changed rows are touched, you can read exactly those changed rows from CDF for the last 24 hours and score only them, which is simpler and more efficient.
Reference:
NEW QUESTION # 66
The data engineering team maintains the following code: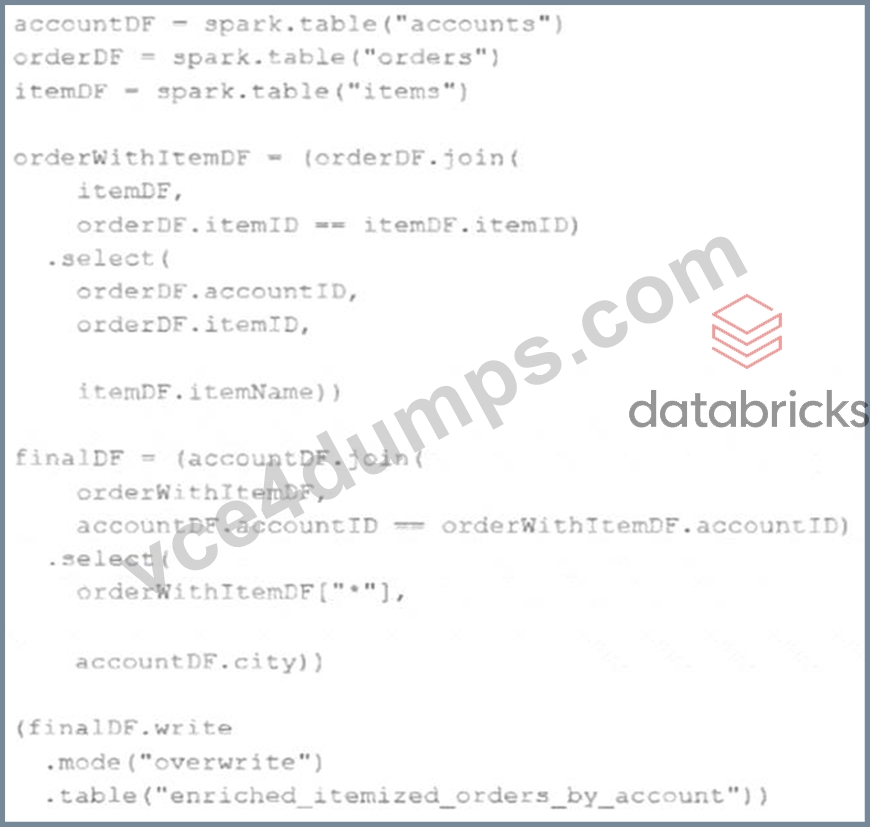
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: B
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 67
......
Free update for one year for Databricks-Certified-Professional-Data-Engineer study guide is available, namely, you don’t need to spend extra money on update version, and the update version for Databricks-Certified-Professional-Data-Engineer exam materials will be sent to your email automatically. In addition, we are pass guarantee and money back guarantee, and if you fail to pass the exam by using Databricks-Certified-Professional-Data-Engineer Exam Dump of us, we will give you full refund. We have online and offline chat service for Databricks-Certified-Professional-Data-Engineer exam materials, and the staffs possess the professional knowledge, if you have any questions, you can consult us, and we will give you reply as quickly as we can.
Databricks-Certified-Professional-Data-Engineer Trustworthy Exam Content: https://www.vce4dumps.com/Databricks-Certified-Professional-Data-Engineer-valid-torrent.html