DOWNLOAD the newest RealExamFree SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yU162k5tIk3kCpPSh-Qbl7ZpvItaO9H3
There is no shortcut to SPS-C01 exam questions success except hard work. You cannot expect your dream of earning the Snowflake CERTIFICATION EXAM come true without using updated study material Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions. Success in the SPS-C01 exam adds more value to your resume and helps you land the best jobs in the industry.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark Concepts | 15% | - Transformations vs. Actions - Client-side vs. Server-side execution - Stored procedures and conditional logic - Snowpark Sessions and connection management - Snowpark architecture and core concepts - Snowpark DataFrames and query plans |
| Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark - Minimizing data transfer - Query pushdown and optimization - Debugging and explain plans - Vectorized UDFs - Caching strategies |
| Snowpark API for Python | 30% | - Reading and writing data - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures |
| Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Window functions - Complex data pipelines - Persisting transformed data - Using built-in functions |
>> Snowflake SPS-C01 Valuable Feedback <<
SPS-C01 also offers free demos, allowing users to test the quality and suitability of the SPS-C01 exam dumps before purchasing. The demo provides access to a limited portion of the material, providing users with a better understanding of the content. Additionally, SPS-C01 provides three months of free updates to ensure that candidates have access to the latest questions.
NEW QUESTION # 353
You have a Snowpark Python application that reads data from a Snowflake table, performs a complex transformation using a User- Defined Table Function (UDTF), and then writes the transformed data back to a new Snowflake table. The UDTF is defined as follows: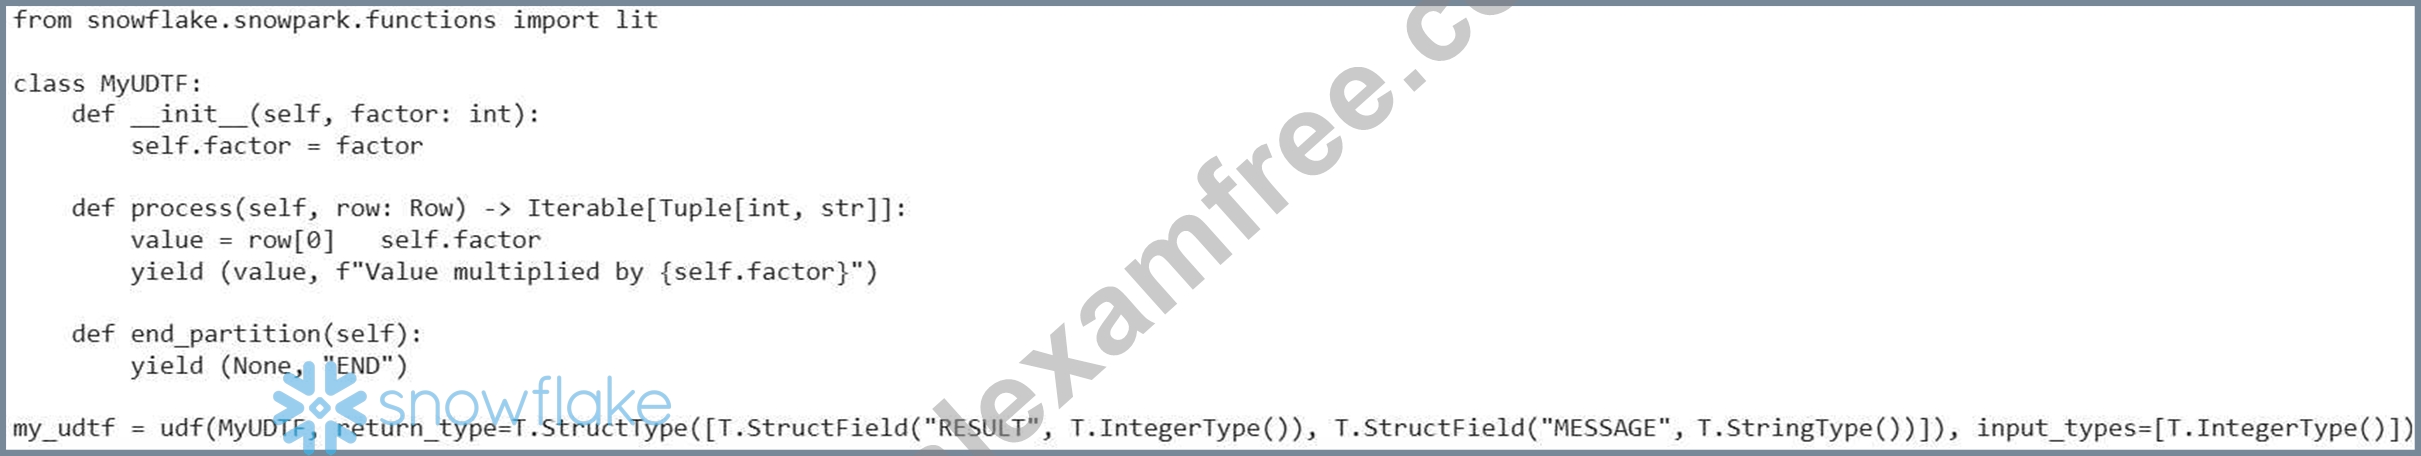
You need to optimize the performance of this application. Which of the following strategies would be MOST effective in reducing the execution time of the UDTF?
Answer: E
Explanation:
Vectorized UDTFs process data in batches, which can significantly improve performance compared to processing each row individually. This is especially true for complex transformations. Increasing warehouse size (A) can help but might not be as efficient as vectorization. Reducing input data (B) is always a good practice, but vectorization provides a more direct performance boost to the UDTF execution. Standard UDFs (D) are not generally faster than UDTFs, especially when dealing with table transformations. Caching (E) can help if the DataFrame is reused multiple times, but it doesn't directly optimize the UDTF's performance.
NEW QUESTION # 354
You have written a Snowpark Python function that utilizes a UDF to perform complex string manipulation on a DataFrame containing customer reviews. When deploying this function using '@sproc.test_utils.mock_snowflake environment, the test fails with a 'ModuleNotFoundError' indicating that a custom Python library (e.g., is not available. You have already confirmed that the library is installed in your local development environment. What is the MOST reliable way to ensure the UDF has access to this dependency during local testing?
Answer: D
Explanation:
Option C is the most reliable solution for local testing with . The function explicitly makes the library available to the Snowpark session during execution, simulating how dependencies are handled in the Snowflake environment. Option A might work locally, but it's not a reliable deployment strategy. Option B is a temporary workaround and not a structured solution. Option D makes the library globally available, defeating the purpose of isolating dependencies for testing. Option E is a valid approach but less explicit and may affect other Python environments on the system. Using 'add_import' ensures that the correct version and dependencies are included in the deployment package.
NEW QUESTION # 355
You have JSON files stored in an internal stage named 'json_stage' within your Snowflake account. Each JSON file contains an array of product objects, with potentially nested structures. You need to create a Snowpark DataFrame to analyze this data, but the schema is complex and you want to avoid explicitly defining it in your Python code. Which of the following Snowpark code snippets will MOST effectively achieve this, assuming you have a Snowpark session object named 'session'?





Answer: A
Explanation:
Option A is the most straightforward. By default, Snowpark automatically infers the schema when reading JSON files directly from a stage without requiring additional options. Other options are useful for specific cases, like handling missing fields, but are not necessary for the basic requirement of reading JSON with schema inference. Note that E would require looping through and UNIONing results, and is far less efficient than the built in stage reader.
NEW QUESTION # 356
You have a Snowpark DataFrame named 'orders_df with columns 'order_id', 'customer_id', 'order_date', and 'order_total'. You need to perform the following data enrichment steps using Snowpark for Python: 1. Calculate the 'year' from the 'order_date' column. 2. Calculate the 'discounted_total' by applying a discount of 10% if the 'order_total' is greater than $100, otherwise, no discount. 3. Create a new column 'customer_tier' based on the total spend per customer for each year. Customers with total spend greater than $1000 are 'Gold', between $500 and $1000 are 'Silver', and below $500 are 'Bronze'. Which of the following code snippets correctly implements these data enrichment steps using Snowpark (Assume the existence of a customer total spend df DataFrame).
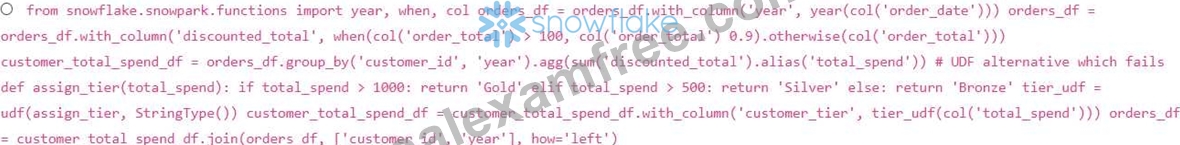
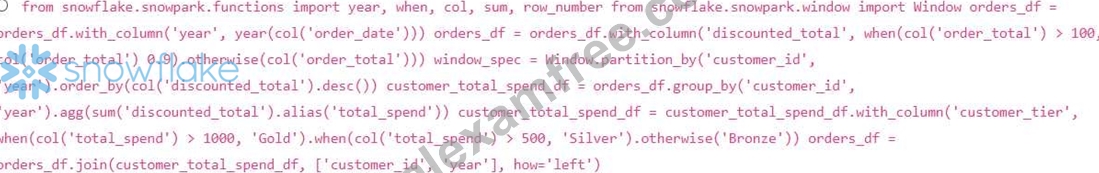

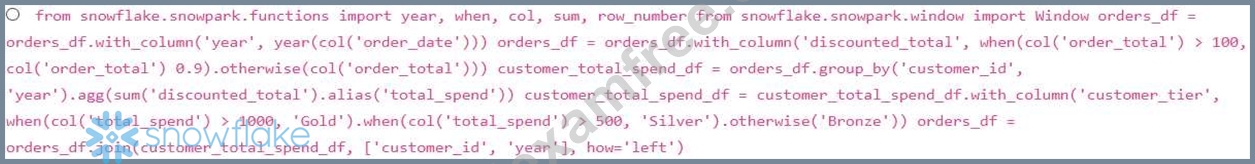
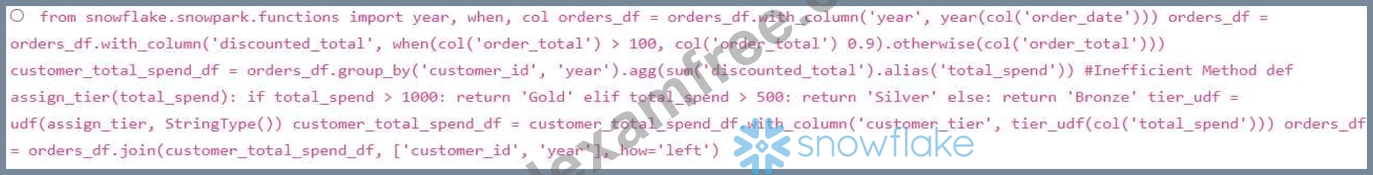
Answer: D
Explanation:
Option B is the most efficient and correct. It calculates 'year' and 'discounted_total' using built-in functions. It then groups by 'customer_id' and 'year' to calculate 'total_spend'. Critically, it then assigns the 'customer_tier' using a series of 'when' statements directly within Snowpark, avoiding the performance overhead of a UDE Finally, it joins the customer tier information back to the original 'orders df. Option A implements Customer Tier calculation using UDF, Option C introduces Windowing without need. Options D, E are incomplete.
NEW QUESTION # 357
You are tasked with building a machine learning pipeline in Snowpark to predict customer churn. You plan to use the scikit-learn library for model training and want to deploy the trained model as a Snowpark UDF for real-time scoring. Consider the following code snippet:
Answer: D
Explanation:
The primary issue is that the 'model' object, which is a trained scikit-learn model, cannot be directly serialized and passed as an argument to the UDF. Snowpark's UDF serialization mechanism doesn't automatically handle complex Python objects like scikit-learn models. You'll need to use a serialization method like 'pickle' to serialize the model into a byte stream, and then deserialize it within the UDF. The other options are less likely to cause the code to fail if serialization is handled, assuming the snowpark library is imported and available, and a return type is correctly defined.
NEW QUESTION # 358
......
We put high emphasis on the protection of our customers’ personal data and fight against criminal actson our SPS-C01 exam questions. Our SPS-C01 preparation exam is consisted of a team of professional experts and technical staff, which means that you can trust our security system with whole-heart. As for your concern about the network virus invasion, SPS-C01 Learning Materials guarantee that our purchasing channel is absolutely worthy of your trust.
Reliable SPS-C01 Exam Sample: https://www.realexamfree.com/SPS-C01-real-exam-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=1yU162k5tIk3kCpPSh-Qbl7ZpvItaO9H3