DOWNLOAD the newest PracticeVCE DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=13Yrj0LWJsa8xImdBBHfvpFOBlWbSaOlY
As practice makes perfect, we offer three different formats of Microsoft DP-750 exam study material to practice and prepare for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam. Our Microsoft DP-750 practice test simulates the real DP-750exam and helps applicants kill exam anxiety. These DP-750 practice exams provide candidates with an accurate assessment of their readiness for the DP-750 test.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 3: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> Unlimited DP-750 Exam Practice <<
To be the best global supplier of electronic DP-750 study materials for our customers through innovation and enhancement of our customers' satisfaction has always been our common pursuit. The advantages of our DP-750 guide dumps are too many to count. And the most important point is that the pass rate of our DP-750 learning quiz is preety high as 98% to 99%. I guess this is also the candidates care most as well. You can totally trust in our DP-750 exam questions!
NEW QUESTION # 11
You have an Azure Databricks workspace that contains a cluster named Cluster1. Cluster1 has the following characteristics:
* Configured as a single node cluster
* Uses a general purpose virtual machine node type
The cluster runtime environment has the following configurations:
* Uses Databricks Runtime for Machine Learning (Databricks Runtime Ml)
* Includes common machine learning libraries
* Supports Python workloads
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The first statement is No . Although Databricks Runtime ML includes machine learning and deep-learning libraries, GPU acceleration also requires a GPU-enabled virtual machine node type and a compatible GPU runtime. Cluster1 uses a general-purpose node type, which provides CPU-based compute rather than GPU acceleration. Microsoft Learn The second statement is No . A single-node cluster has no separate worker nodes. The driver operates as both the master and worker, and Spark runs locally. Consequently, Cluster1 cannot distribute machine learning processing across multiple nodes. A multi-node cluster would be required for distributed workloads.
Microsoft Learn
The third statement is Yes . Databricks Runtime ML provides a ready-to-use machine learning environment containing commonly used libraries such as scikit-learn, TensorFlow, PyTorch, XGBoost, and MLflow.
Because Cluster1 supports Python, Python workloads can import and use these preinstalled libraries without requiring each package to be installed separately.
NEW QUESTION # 12
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.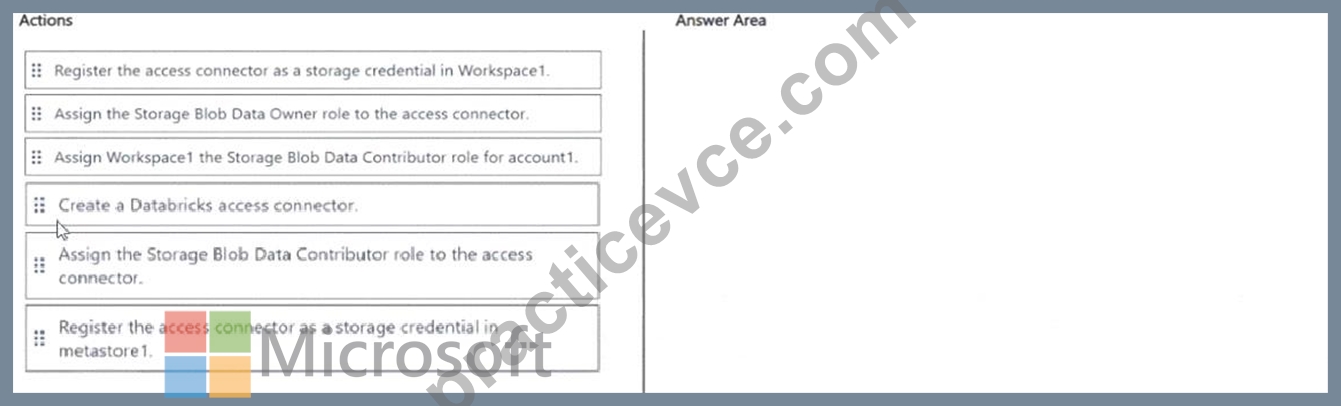
Answer:
Explanation: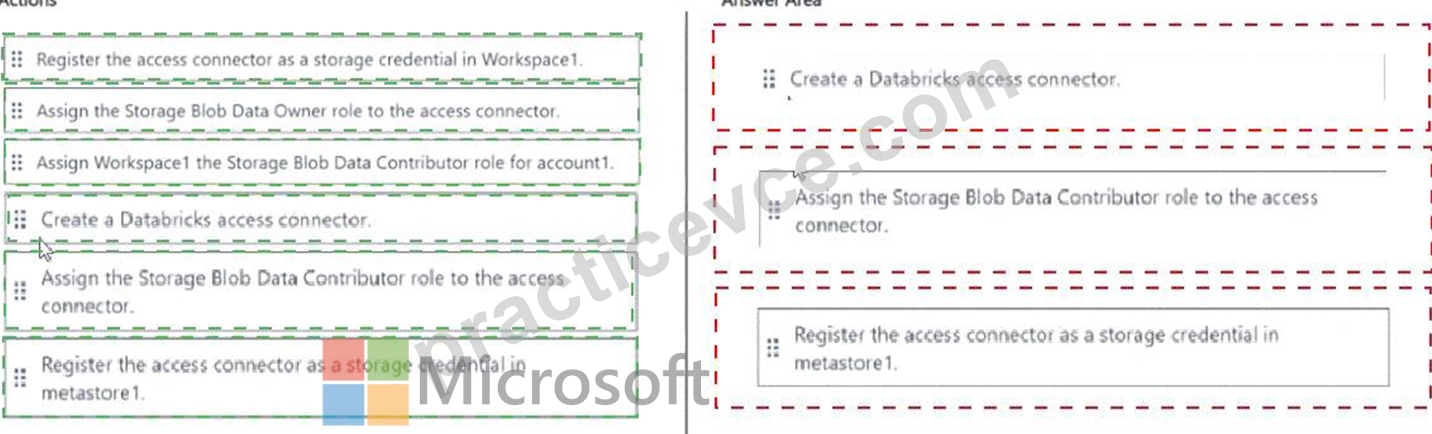
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 13
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 14
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: D
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 15
What does the VACUUM command do in Delta Lake?
Answer: C
Explanation:
VACUUM removes old, unreferenced files that are no longer needed after updates or deletes. It helps manage storage but does not improve query performance directly. OPTIMIZE handles performance improvements. Schema changes are unrelated.
NEW QUESTION # 16
......
To increase your chances of success, consider utilizing the PracticeVCE DP-750 Exam Questions, which are valid, updated, and reflective of the actual DP-750 exam. Don't miss the opportunity to strengthen your Microsoft DP-750 exam preparation with these valuable questions. The PracticeVCE is a leading platform that has been assisting the Microsoft DP-750 Exam candidates for many years. Over this long time period countless DP-750 exam candidates have passed their Microsoft DP-750 certification exam. They got success in Implementing Data Engineering Solutions Using Azure Databricks exam with flying colors and did a job in top world companies.
DP-750 Test Guide Online: https://www.practicevce.com/Microsoft/DP-750-practice-exam-dumps.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by PracticeVCE: https://drive.google.com/open?id=13Yrj0LWJsa8xImdBBHfvpFOBlWbSaOlY