P.S. Free 2026 Microsoft AI-500 dumps are available on Google Drive shared by RealValidExam: https://drive.google.com/open?id=1GGbEz47JQiGcNoOHQYYY3rv_MzDkOzXH
The software boosts varied self-learning and self-assessment functions to check the results of the learning. The software can help the learners find the weak links and deal with them. Our AI-500 exam torrent boosts timing function and the function to stimulate the exam. Our product sets the timer to stimulate the exam to adjust the speed and keep alert. Our AI-500 study questions have simplified the complicated notions and add the instances, the stimulation and the diagrams to explain any hard-to-explain contents.
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
| Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
The AI-500 study materials are in the process of human memory, is found that the validity of the memory used by the memory method and using memory mode decision, therefore, the AI-500 training materials in the process of examination knowledge teaching and summarizing, use for outstanding education methods with emphasis, allow the user to create a chain of memory, the knowledge is more stronger in my mind for a long time by our AI-500 study engine. Firmly believe in an idea, the AI-500 exam questions are as long as the user to follow our steps to obtain the certificate.
NEW QUESTION # 48
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
Answer: C
Explanation:
Microsoft Foundry Agent Service is the managed option that best satisfies containerized production agent execution, dynamic scaling, and low administrative overhead. Hosted agents run in Foundry-managed container compute and scale according to workload demand while the platform manages much of the runtime, endpoint, identity, and operational plumbing. AKS could provide strong tenant/workload isolation and autoscaling, but it also requires Kubernetes cluster operations, policy, upgrades, node pools, and scaling configuration, which conflicts with the requirement to minimize administration as the tenant count grows.
Azure Container Instances is simpler but lacks the same managed autoscaling model, and GPU virtual machines create the highest infrastructure burden. Therefore C is the strongest fit for a SaaS platform that wants production agent compute without owning the orchestration platform. From an architecture perspective, the selection also creates explicit ownership and boundaries that can be tested independently. That matters in multi-agent systems because implicit sharing or loosely defined authority often becomes the source of cross- agent coupling, security drift, and difficult incident diagnosis.
Official Microsoft reference: Microsoft Foundry Agent Service overview
NEW QUESTION # 49
You have a Microsoft Foundry multi-agent solution that includes a planning agent and an execution agent You are designing a fixed order process where executions can run for several hours and can be interrupted by worker restarts.
You need to implement orchestration for the process. The solution must meet the following requirements
* Pause at predefined points.
* Resume from the last saved state after an interruption.
Which mechanisms should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.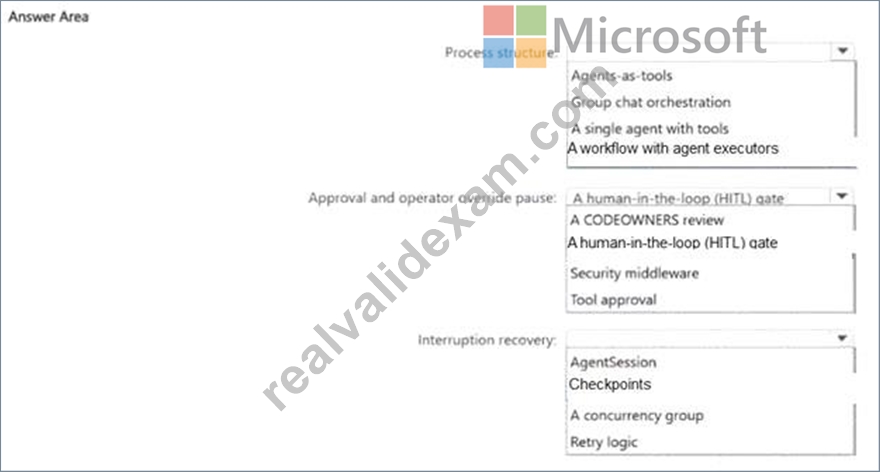
Answer:
Explanation: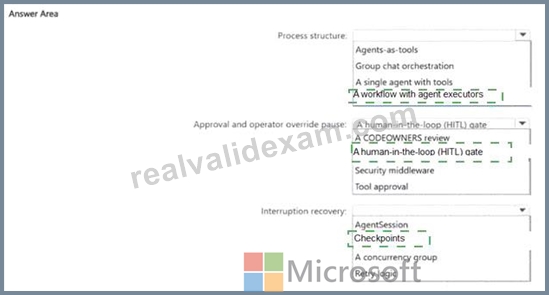
Explanation:
Process structure: A workflow with agent executors; Pause mechanism: A human-in-the-loop (HITL) gate; Interruption recovery: Checkpoints.
The process has a fixed execution order and can run for several hours, so an explicit workflow with agent executors is preferable to free-form agent delegation. The requirement to pause at predefined points is a human-in-the-loop requirement: the workflow must be able to suspend and emit a request for approval or operator input. The requirement to resume after worker restarts is addressed by checkpoints. Microsoft Agent Framework checkpoints persist workflow progress, executor state, pending messages, shared state, and outstanding requests so execution can be restored from the last saved point. A retry policy alone re-executes operations but does not reconstruct the complete workflow state after a process interruption. The three selected mechanisms therefore cover structure, controlled pause, and durable recovery as separate but complementary workflow concerns. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Checkpoints and Human-in-the-loop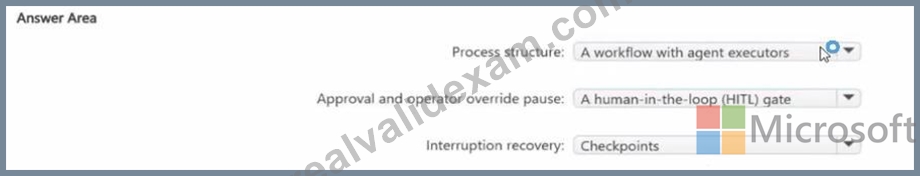
NEW QUESTION # 50
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.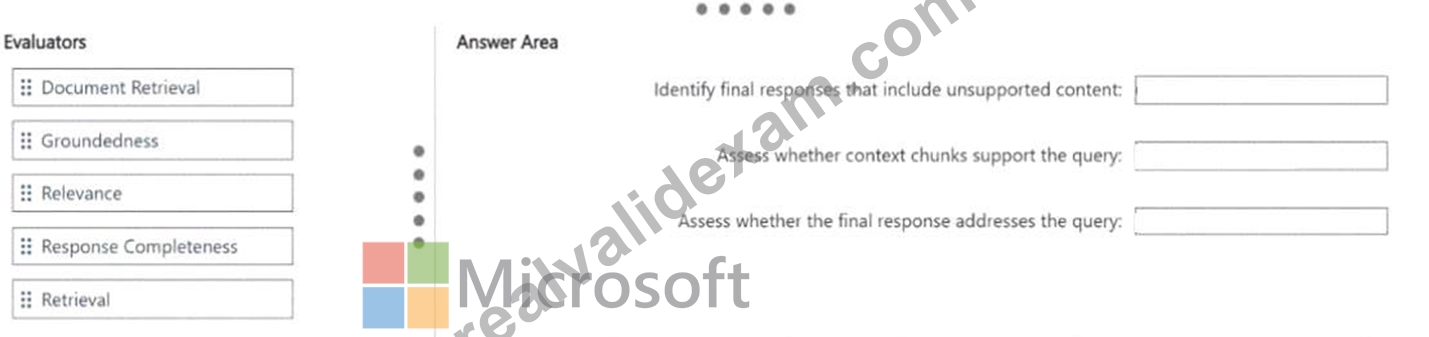
Answer:
Explanation: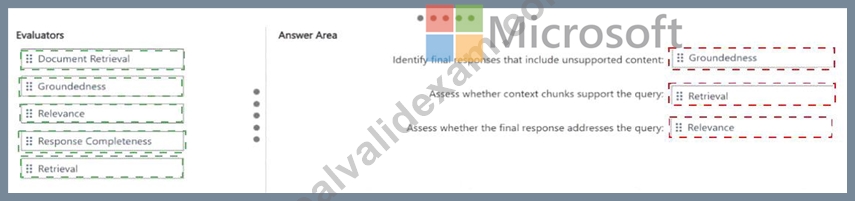
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators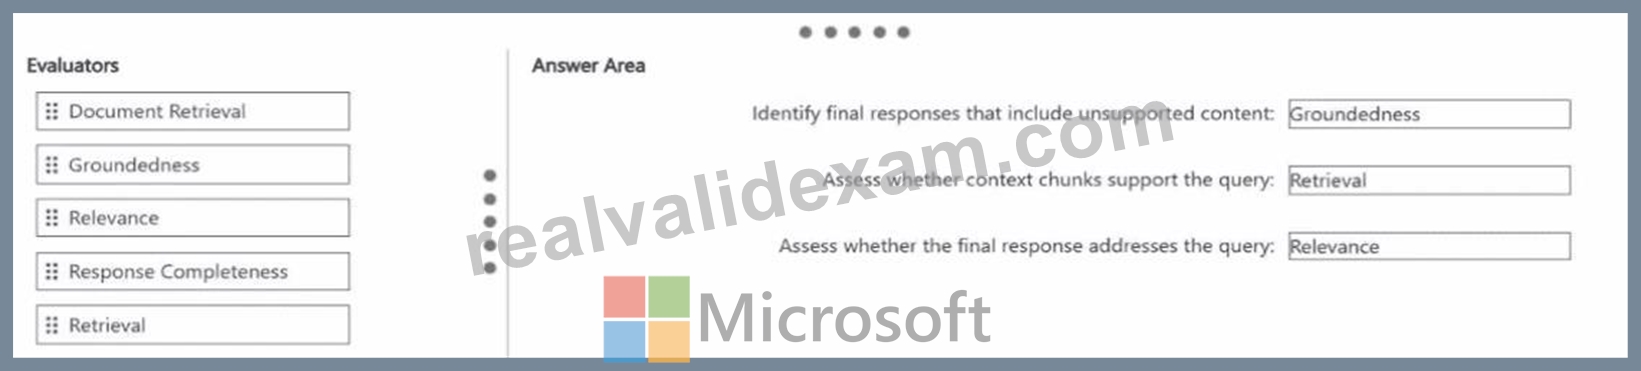
NEW QUESTION # 51
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: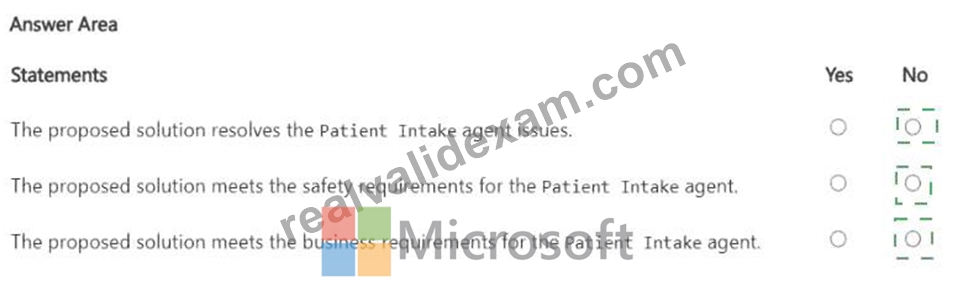
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
NEW QUESTION # 52
You have a Microsoft Foundry project that contains a coordinator agent for claims processing.
You have an existing fraud analysis agent hosted outside of Foundry. The agent exposes a standards-based HTTPS endpoint, publishes the supported s kills and media types, and requires authenticated requests.
You need to configure the coordinator agent to invoke the fraud analysis agent. The solution must meet the following requirements:
Use the interoperable invocation interface.
Use the published capability discovery contract.
Reuse stored authentication across versions of the coordinator agent.
How should you configure the integration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.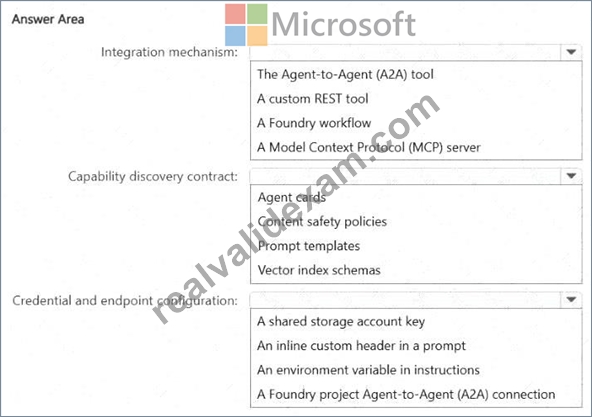
Answer:
Explanation: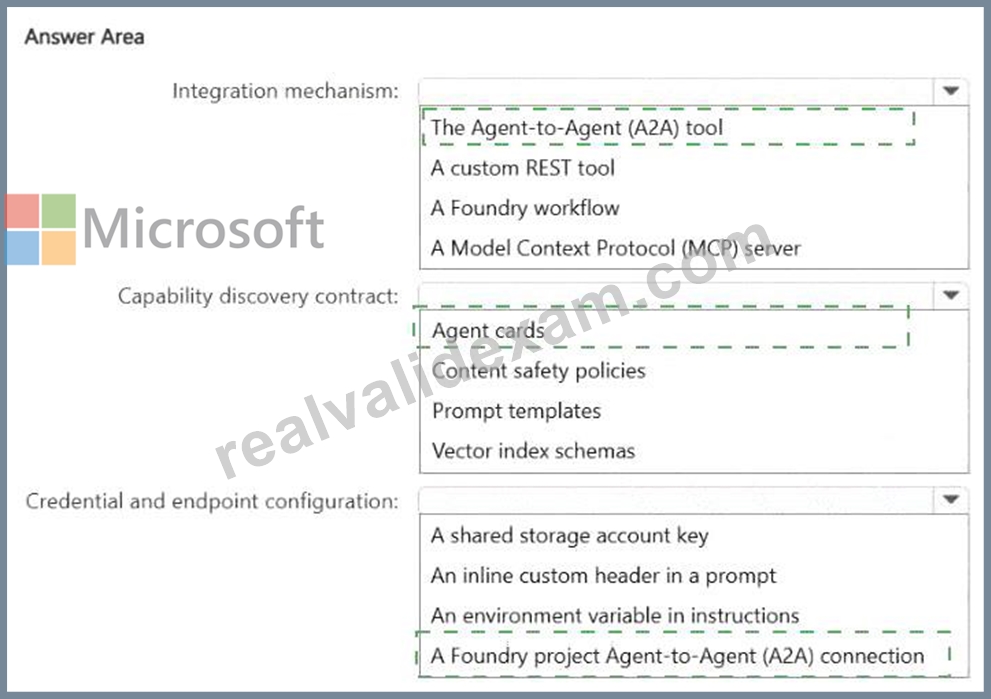
Explanation:
Integration mechanism: Agent-to-Agent (A2A) tool; Capability discovery contract: Agent cards; Credential and endpoint configuration: A Foundry project A2A connection.
The remote fraud service is an autonomous agent that exposes a standards-based HTTPS endpoint and publishes its skills and media types, which matches the Agent-to-Agent protocol rather than a conventional tool API. A2A uses an agent card as the capability-discovery contract, allowing the coordinator to discover supported skills, formats, and invocation details without coupling to the remote framework ' s implementation.
Microsoft Foundry project A2A connections store the remote endpoint and authentication configuration so credentials can be reused across coordinator-agent versions instead of being embedded separately in every version. Together, the A2A tool, agent card, and project connection satisfy interoperable invocation, capability discovery, and reusable authentication. This is the supported Microsoft architecture for calling an external A2A-compatible agent from a Foundry coordinator. The configuration should be kept in the project connection rather than prompt text so authentication remains centrally managed, auditable, and reusable as the coordinator evolves. This also avoids duplicating sensitive connection settings across agent versions.
Official Microsoft reference: Microsoft Foundry - enable Agent-to-Agent endpoint and authentication
NEW QUESTION # 53
......
Our company is a professional certificate test materials provider, and we are in the leading position in providing valid and effective exam materials. AI-500 exam braindumps are high quality, and it also contain certain questions and answers, and it will be enough for you to pass the exam. Besides, in order to let you have a deeper understanding of what you are going to buy, we offer you free demo to have a try before buying AI-500 Training Materials. We offer you free update for 365 days after purchasing, and the update version will be sent to your email address automatically.
Valid AI-500 Dumps Demo: https://www.realvalidexam.com/AI-500-real-exam-dumps.html
BTW, DOWNLOAD part of RealValidExam AI-500 dumps from Cloud Storage: https://drive.google.com/open?id=1GGbEz47JQiGcNoOHQYYY3rv_MzDkOzXH