2026 Die neuesten EchteFrage Databricks-Certified-Professional-Data-Engineer PDF-Versionen Prüfungsfragen und Databricks-Certified-Professional-Data-Engineer Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1iUUmLNmxIhn-Nmt1U83gVKjN3Q4ym6HJ
Die Produkte von PassTest sind für diejenigen, die sich an der Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung beteiligen,geeignet. Die Schulungsmaterialien von EchteFrage enthalten nicht nur Trainingsmaterialien zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung, um Ihre Fachkenntnisse zu konsolidieren, sondern auch die genauen Prüfungsfragen und Antworten. Wir versprechen, dass Sie die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung beim ersten Versuch mit einer hohen Note bestehen können.
Die Datenbank für die Datenbank für professionelle Dateneringenieure ist eine strenge Zertifizierungsprüfung, die umfangreiche Kenntnisse und Erfahrung im Datenentwicklung erfordert. Die Kandidaten müssen ein tiefes Verständnis der Daten technischen Konzepte wie Datenmodellierung, Data Warehousing, ETL, Data Governance und Datensicherheit haben. Darüber hinaus müssen sie Erfahrung in der Arbeit mit Datenbank -Tools und -Technologien wie Apache Spark, Delta Lake und MLFlow haben. Das Bestehen dieser Prüfung zeigt, dass der Kandidat über die Fähigkeiten und das Wissen verfügt, um Datenpipelines auf der Datenbankplattform zu erstellen und zu optimieren.
>> Databricks-Certified-Professional-Data-Engineer Prüfungs-Guide <<
Unser EchteFrage stellt Ihnen die besten Fragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung zur Verfügung und führt Ihnen schrittweise zum Erfolg. Die Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von EchteFrage werden Ihnen eine reale Prüfungsvorbereitung bieten. Sie sind ganz zielgerichtet. Sie werden sicher ein IT-Expert werden. Unsere Databricks Databricks-Certified-Professional-Data-Engineer Schulungsunterlagen sind Ihnen am geeignetesten.Tragen Sie doch in unserer Website ein. Sie werden sicher etwas Unerwartetes bekommen.
Die Zertifizierung von Datenbäumen Certified Professional Data Engineer ist ein wertvoller Berechtigungsnachweis für Dateningenieure, die ihre Fähigkeiten und Fachkenntnisse bei der Verwendung von Datenbäumen validieren möchten. Die Zertifizierung zeigt den Arbeitgebern und Kunden, dass der Kandidat über das Wissen und die Fähigkeiten verfügt, die zur Gestaltung und Implementierung von Datenlösungen mithilfe von Datenbanken erforderlich sind. Es hilft auch Dateningenieuren, sich in einem wettbewerbsfähigen Arbeitsmarkt zu unterscheiden, und bietet Möglichkeiten für den beruflichen Aufstieg.
86. Frage
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
Antwort: B
Begründung:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
87. Frage
The data engineering team is looking to add a new column to the table, but the QA team would like to test the change before implementing in production, which of the below options allow you to quickly copy the table from Prod to the QA environment, modify and run the tests?
Antwort: A
Begründung:
Explanation
The answer is SHALLOW CLONE
SHALLOW CLONE If you wish to create a copy of a table quickly to test out applying changes without the risk of modifying the current table, SHALLOW CLONE can be a good option. Shallow clones just copy the Delta transaction logs, meaning that the data doesn't move so it can be very quick.
1.CREATE OR REPLACE TABLE {new_table_name} SHALLOW CLONE
{source_table_name}|[LOCATION path]
DEEP CLONE fully copies data and metadata from a source table to a target. This copy occurs incre-mentally, so executing this command again can sync changes from the source to the target location. It copies all of the data and transaction logs this can take a long time based on the size of the table.
1.CREATE OR REPLACE TABLE {new_table_name} DEEP CLONE {source_table_name}|[LOCATION path]
88. Frage
A table named user_ltv is being used to create a view that will be used by data analysts on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: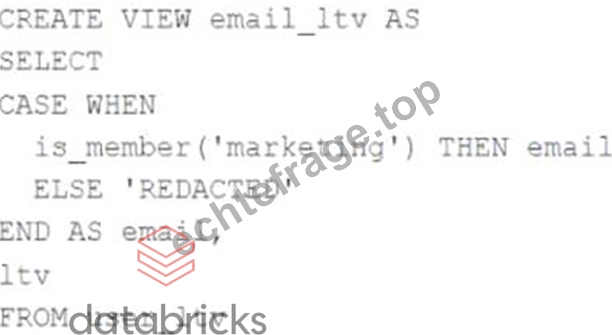
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Antwort: B
Begründung:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
89. Frage
A data engineering team needs to implement a tagging system for their tables as part of an automated ETL process, and needs to apply tags programmatically to tables in Unity Catalog.
Which SQL command adds tags to a table programmatically?
Antwort: A
Begründung:
Comprehensive and Detailed Explanation from Databricks Documentation:
Unity Catalog in Databricks provides the ability to attach tags (key-value metadata pairs) to securable objects such as catalogs, schemas, tables, volumes, and functions. Tags are critical for governance, compliance, and automation, as they allow organizations to track metadata like sensitivity, ownership, business purpose, and retention policies directly at the object level.
According to the official Databricks SQL reference for Unity Catalog, the correct way to programmatically add tags to a table is by using the ALTER TABLE ... SET TAGS command. The syntax is:
ALTER TABLE table_name SET TAGS ('tag_name' = 'tag_value', ...);
This command can be used within ETL workflows or jobs to automatically apply metadata during or after ingestion, ensuring that governance and compliance rules are embedded in the pipeline itself.
Option A is correct because it uses the supported syntax for applying tags.
Option B (APPLY TAGS) is not valid SQL in Unity Catalog and is not recognized by Databricks.
Option C confuses COMMENT with TAGS. While COMMENT can add descriptive text to a table, it does not handle tags.
Option D (SET TAGS FOR) is not a valid SQL construct in Databricks for applying tags.
Thus, Option A is the only valid and documented way to programmatically set tags on a table in Unity Catalog.
90. Frage
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.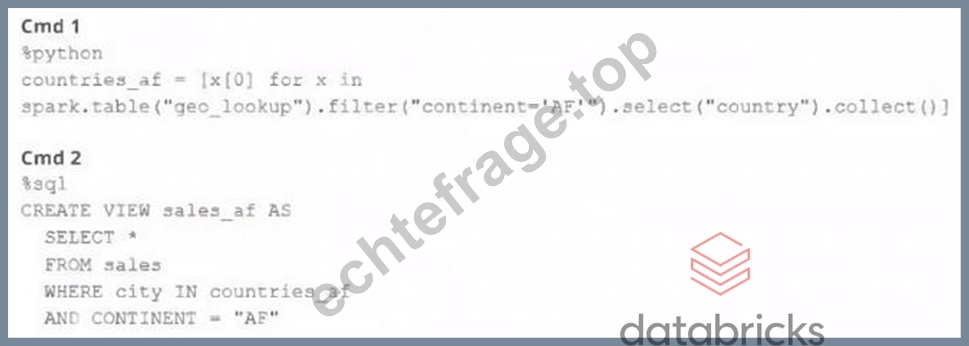
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Antwort: A
Begründung:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified Reference: [Databricks Certified Data Engineer Professional], under "Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
91. Frage
......
Databricks-Certified-Professional-Data-Engineer PDF Demo: https://www.echtefrage.top/Databricks-Certified-Professional-Data-Engineer-deutsch-pruefungen.html
Laden Sie die neuesten EchteFrage Databricks-Certified-Professional-Data-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1iUUmLNmxIhn-Nmt1U83gVKjN3Q4ym6HJ