P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Pass4Leader: https://drive.google.com/open?id=1RhQ012jheP_eq7rCaTs1vykj6maPkXkb
We always aim at improving our users’ experiences. You can download the PDF version demo before you buy our SPS-C01 test guide, and briefly have a look at the content and understand the SPS-C01 exam meanwhile. After you know about our SPS-C01 actual questions, you can decide to buy it or not. The process is quiet simple, all you need to do is visit our website and download the free demo. That would save lots of your time, and you’ll be more likely to satisfy with our SPS-C01 Test Guide.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and Operations | 35% | - Advanced operations
|
| Topic 2: Performance and Best Practices | 10% | - Security and governance
|
| Topic 3: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Topic 4: Snowpark API and Development | 30% | - Multi-language support
|
>> SPS-C01 Exam Brain Dumps <<
Services like quick downloading within five minutes, convenient and safe payment channels made for your convenience. Even newbies will be tricky about this process. Unlike product from stores, quick browse of our SPS-C01 practice materials can give you the professional impression wholly. So, they are both efficient in practicing and downloading process. By the way, we also have free demo of SPS-C01 practice materials as freebies for your reference to make your purchase more effective.
NEW QUESTION # 58
A data engineering team has developed a Snowpark Python application to process customer orders, enrich them with external data (e.g., geo location, weather) and update the Customer360 table. The application is deployed to a production environment. The application's latency has significantly increased over the last week. Your investigation reveals that the Snowflake warehouse used by the application is constantly switching between the 'Scaling Up' and 'Scaling Down' states. The team has set the Auto Suspend time to 5 minutes and Auto Resume to True. Assuming that the team hasn't changed the code, the external API or any parameter related to data ingestion, which combination of the following actions would MOST likely fix the warehouse instability issue and improve the performance of this Snowpark application in production without substantial cost increases?
Answer: A,B
Explanation:
The 'Scaling Up' and 'Scaling Down' thrashing is likely caused by the warehouse suspending too quickly, leading to constant restarts as new requests arrive. Increasing the Auto Suspend time (Option A) prevents this frequent cycling. Increasing the MIN CLUSTER COUNT (Option B) makes more resources readily available, helping the warehouse respond faster to spikes in demand and reducing the need for scaling up. Workload management (Option C) is a good practice but may not directly address the root cause of the instability. Reducing MAX_CLUSTER_COUNT (Option D) could worsen the problem by limiting the warehouse's ability to handle peak loads. Changing to 'ECONOMY' scaling policy (Option E) would prioritize cost over performance, which is counter to improving performance.
NEW QUESTION # 59
You have developed a Snowpark application that uses a Python UDF to perform sentiment analysis on text data extracted from JSON files stored in a Snowflake stage. The UDF relies on a large pre-trained machine learning model that is loaded during the UDF initialization. After deploying the application, you observe that the UDF initialization is taking a significant amount of time, causing slow query performance. What are the three MOST effective strategies to optimize the UDF initialization time in this scenario?
Answer: A,C,E
Explanation:
Optimizing UDF initialization is crucial for performance. Option A is correct because caching the model using 'cachetoolS avoids reloading it for each UDF call. Option C is also correct; 'context.add_dependency' tells Snowflake to distribute and cache the model on worker nodes, further reducing load times. Option D avoids the need for the UDF to load the model, reducing the initialization step down entirely. Streamlit caching is not valid for Snowflake operations, making option E incorrect. 'SnowflakeFile' isn't best used within a UDF initializer as its inefficient, making option B incorrect.
NEW QUESTION # 60
You have a requirement to create Snowpark DataFrames from CSV files located in an AWS S3 external stage. Some CSV files have a header row, while others do not. The files also use different delimiters (comma, semicolon, or tab). You want to create a single function that can handle all these variations, without creating separate functions for each combination. The 'create_dataframe' function receives the stage path, the delimiter, and a boolean indicating whether a header is present. Which of the following code snippets, when implemented inside the function, BEST achieves this goal using the Snowpark Python API? Assume a Snowpark session 'session'.





Answer: A
Explanation:
Option D is the best approach. It correctly handles both delimiter and header options for CSV files using the correct option names ('field_delimiter' and 'skip_header'). The 'skip_header' option requires '0' or '1', not a boolean. Option A will throw exception as it uses incorrect option name. Option B will throw exception as hasHeader is expecting 0 or 1. Option C uses 'skip_header' but this option does not exist in snowpark DataFrameReader option E will throw exception as 'format' method should be called before 'options' method.
NEW QUESTION # 61
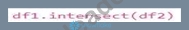
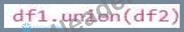
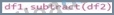
You have two Snowpark DataFrames, 'dfl' and 'df2, representing customer data'. 'dfl' contains columns 'CUSTOMER ID', 'NAME, and 'EMAIL', while 'df2 contains 'CUSTOMER ID' and 'PURCHASE AMOUNT'. You need to create a new DataFrame that combines the information from both DataFrames but only includes customers who exist in BOTH 'dfl ' and 'df2 and the resulting DataFrame should have columns from both. Which of the following Snowpark DataFrame operations should you use, and what is the correct way to call it?


Answer: A,B
Explanation:
To include only customers present in BOTH DataFrames and include columns from both, you need to perform an INNER JOIN. Options B, C and D are incorrect: intersect, union and subtract operations work at a row level. Also, intersect , union and subtract operations expects the number of columns and datatypes to match and is not relevant to the described scenario. Option A and E are valid way to use the join operation: (A) uses the explicit condition 'dfl .CUSTOMER_ID df2.CUSTOMER_lD while (E) is the short form which specifies the column name directly. Both achieves the same inner join behavior. You can choose E as a cleaner option when only joining on column name.
NEW QUESTION # 62
You have a Snowpark DataFrame containing sales data with columns 'region' , and 'sales_amount'. You need to calculate the total sales amount for each region and then filter the results to only include regions where the total sales amount is greater than 10000. Which of the following Snowpark code snippets correctly implements this logic?





Answer: D
Explanation:
Option C is correct because it uses the correct Snowpark syntax for grouping by region, summing the sales amount with an alias, and then filtering based on the aliased column. Option A is incorrect as it omits the 'sf.' prefix for 'sum' and 'col' within the 'filter'. Option B uses where' instead of Tilters but correctly aggregates. Option D incorrectly compares a string to a number in the filter. Option E uses a non-standard way of referencing the aggregated column in the 'where' clause.
NEW QUESTION # 63
......
We never concoct any praise but show our capacity by the efficiency and profession of our SPS-C01 practice materials. Besides, the pollster conducted surveys of public opinions of our SPS-C01 study engine and get desirable outcomes that more than 98 percent of exam candidates feel rewarding after using our SPS-C01 Actual Exam. And we enjoy their warm feedbacks to show and prove that we really did a good job in this career. You can totally rely on us!
SPS-C01 Exam Passing Score: https://www.pass4leader.com/Snowflake/SPS-C01-exam.html
What's more, part of that Pass4Leader SPS-C01 dumps now are free: https://drive.google.com/open?id=1RhQ012jheP_eq7rCaTs1vykj6maPkXkb