Now on the Internet, a lot of online learning platform management is not standard, some web information may include some viruses, cause far-reaching influence to pay end users and adverse effect. If you purchase our Databricks-Certified-Data-Engineer-Professional test torrent this issue is impossible. We hire experienced staff to handle this issue perfectly. We are sure that our products and payment process are surely safe and anti-virus. If you have any question about downloading and using our Databricks-Certified-Data-Engineer-Professional Study Tool, we have professional staff to remotely handle for you immediately, let users to use the Databricks Certified Data Engineer Professional Exam guide torrent in a safe environment, bring more comfortable experience for the user.
| Section | Weight | Objectives |
|---|---|---|
| Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Optimize compute and storage resources - Apply cost management best practices |
| Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Enforce data quality standards - Implement schema evolution and management |
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Ensure data privacy and compliance - Implement access control and permissions |
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic - Use Databricks-specific libraries and APIs - Write efficient and maintainable code |
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
| Data Governance | 7% | - Enforce data policies and standards - Use Unity Catalog for governance - Manage data assets and metadata |
| Data Modelling | 6% | - Implement dimensional and relational models - Design Medallion Architecture - Optimize table design and partitioning |
| Data Sharing and Federation | 5% | - Manage cross-platform data access - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation |
>> Premium Databricks-Certified-Data-Engineer-Professional Exam <<
There is no doubt that in the future information society, knowledge and skills will be a major driver for economic growth and one of the major contributors to the sustainable development of the information industry. And getting the related Databricks Certified Data Engineer Professional Exam certification in your field will be the most powerful way for you to show your professional knowledge and skills. However, it is not easy for the majority of candidates to prepare for the exam in order to pass it, if you are one of the candidates who are worrying about the exam now, congratulations, there is a panacea for you--our Databricks-Certified-Data-Engineer-Professional Study Tool.
NEW QUESTION # 83
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
Answer: A
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 84
The following code has been migrated to a Databricks notebook from a legacy workload: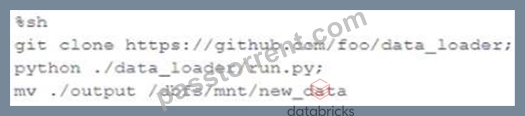
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
Answer: E
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 85
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.address THEN UPDATE SET current = false, end_date = staged_updates.effective_date WHEN NOT MATCHED THEN INSERT (customer_id, address, current, effective_date, end_date) VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
Answer: A
Explanation:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context. In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.
NEW QUESTION # 86
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: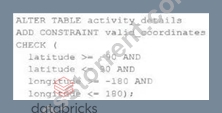
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: E
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 87
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: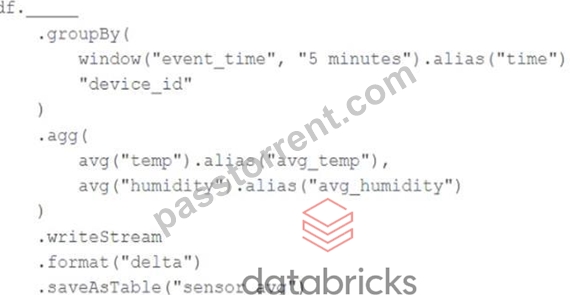
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: A
Explanation:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
NEW QUESTION # 88
......
Nowadays, the certification has been one of the criteria for many companies to recruit employees. And in order to obtain the Databricks-Certified-Data-Engineer-Professional certification, taking the Databricks-Certified-Data-Engineer-Professional exam becomes essential. Although everyone hopes to pass the exam, the difficulties in preparing for it should not be overlooked. There are plenty of people who took a lot of energy and time but finally failed to pass. You really need our Databricks-Certified-Data-Engineer-Professional practice materials which can work as the pass guarantee.
Valid Dumps Databricks-Certified-Data-Engineer-Professional Sheet: https://www.passtorrent.com/Databricks-Certified-Data-Engineer-Professional-latest-torrent.html