Databricks-Machine-Learning-Professional Pass4sure Guide & Databricks-Machine-Learning-Professional Exam Preparation & Databricks-Machine-Learning-Professional Study Materials

2026 Latest PrepAwayPDF Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=135h-8xej4tlBraPVoPFu_x7lryo5L9EO
It is difficult to get the Databricks-Machine-Learning-Professional certification for you need have extremely high concentration to have all test sites in mind. Our Databricks-Machine-Learning-Professional learning questions can successfully solve this question for the content are exactly close to the changes of the real exam. When you grasp the key points, nothing will be difficult for you anymore. Our professional experts are good at compiling the Databricks-Machine-Learning-Professional training guide with the most important information. Believe in us, and your success is 100% guaranteed!
| Topic | Details |
|---|
| Topic 1 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 2 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 3 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 4 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 5 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 6 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 7 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 8 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 9 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
>> Databricks-Machine-Learning-Professional Latest Exam Papers <<
Selecting The Databricks-Machine-Learning-Professional Latest Exam Papers, Pass The Databricks Certified Machine Learning Professional
Our Databricks-Machine-Learning-Professional quiz torrent can provide you with a free trial version, thus helping you have a deeper understanding about our Databricks-Machine-Learning-Professional test prep and estimating whether this kind of study material is suitable to you or not before purchasing. With the help of our trial version, you will have a closer understanding about our Databricks-Machine-Learning-Professional exam torrent from different aspects, ranging from choice of three different versions available on our test platform to our after-sales service. Otherwise you may still be skeptical and unintelligible about our Databricks-Machine-Learning-Professional Test Prep. So as you see, we are the corporation with ethical code and willing to build mutual trust between our customers.
Databricks Certified Machine Learning Professional Sample Questions (Q81-Q86):
NEW QUESTION # 81
A Machine Learning Engineer has trained a credit scoring model and needs to evaluate fairness metrics across different customer segments while maintaining different levels of granularity for business reporting. They need to compute metrics like precision, recall, and demographic parity at the individual feature level (credit_score_range, income_bracket) as well as intersectional slices (combinations of features). The model outputs are stored in a Delta table with prediction probabilities and actual default labels. The engineer wants to systematically evaluate model performance across these various feature slices and granularities. Which approach will do this?
- A. Use Unity Catalog metric views with dimensions defined for each feature and measures for the fairness metrics.
- B. Build separate Spark DataFrames for each slice and compute metrics using standard DataFrame operations.
- C. Implement custom MLflow evaluation functions that iterate through all possible feature combinations.
- D. Create Lakehouse Monitoring with slicing expressions for individual features and intersection conditions.
Answer: D
Explanation:
Lakehouse Monitoring supports defining slicing expressions on one or more columns, allowing metrics such as precision, recall, and fairness indicators to be computed at both individual feature levels and intersectional combinations. This provides a systematic, scalable, and governed way to evaluate model performance and fairness across multiple granularities directly from Delta tables without custom metric pipelines.
NEW QUESTION # 82
Which of the following describes the concept of MLflow Model flavors?
- A. A convention that deployment tools can use to wrap preprocessing logic into a Model
- B. A convention that MLflow Model Registry can use to organize its Models by project
- C. A convention that deployment tools can use to understand the model
- D. A convention that MLflow Model Registry can use to version models
- E. A convention that MLflow Experiments can use to organize their Runs by project
Answer: E
NEW QUESTION # 83
A Machine Learning Engineer is tasked with implementing a simple solution, requiring as little code as possible, to monitor a regression model and ensure that the R2 score does not exceed a certain threshold. If the threshold is exceeded, the solution needs to send an email to a distribution list. Which proposed solution meets the criteria?
- A. Create a Workflow that runs on a schedule. The Workflow executes a SQL Query that calculates the R2 score. Use Workflow If/Else condition to execute a Notebook Task that sends the email if the R2 score threshold is exceeded.
- B. Configure Lakehouse Monitoring using the Inference profile type. Create a SQL Alert that runs on a schedule and evaluates if the R2 score in the profile table exceeds the threshold. If so, the Alert should send an email to the configured email notification destination.
- C. Configure Lakehouse Monitoring using the Inference profile type. Create a SQL Query that runs on a schedule and evaluates if the R2 score in the profile table exceeds the threshold. If so, the Alert should send an email to the configured email notification destination.
- D. Configure Lakehouse Monitoring using the Inference profile type. Create a Workflow that runs on a schedule and executes a SQL query that evaluates the R2 score in the profile table. Use Workflow If/Else condition to execute a Notebook Task that sends the email if the R2 score threshold is exceeded.
Answer: B
Explanation:
Lakehouse Monitoring with the Inference profile already computes regression performance metrics such as R2 and stores them in Delta tables. A Databricks SQL Alert can directly evaluate the R2 value against a threshold on a schedule and send an email notification when the condition is met. This requires minimal code and avoids additional workflows or custom logic, making it the simplest and most maintainable solution.
NEW QUESTION # 84
A Machine Learning Engineer has deployed a fraud detection model in Databricks Model Serving to detect fraudulent transactions. The engineer wants to compare the model's predictions with the actual fraud classifications from the Fraud Ops team to monitor model performance. The Fraud Ops team uses a unique transaction_id to investigate fraudulent activity and persist their findings to a fraud_findings table. The engineer enabled inference tables on the endpoint, but they are not sure how to map the models' predictions to the Fraud Ops team's classifications. How can the engineer uniquely join the models' prediction to the fraud_findings table with the fewest code changes?
- A. Join the inference table with the fraud_findings table using timestamp_ms as the join key.
- B. Store databricks_request_id returned from each model serving request and persist it to the fraud_findings table. Join the inference table with the fraud_findings table using databricks_request_id as the join key.
- C. Populate the client_request_id field with the transaction_id in the model serving request body.
Join the inference table with the fraud_findings table using client_request_id (which contains the transaction_id) as the join key. - D. Modify the model to include an additional input: transaction_id. Log, register and deploy the new model. In the model serving request body, add transaction_id as an additional input feature. Join the inference table with the fraud_findings table using transaction_id as the join key.
Answer: C
Explanation:
Databricks Model Serving inference tables automatically log the client_request_id field for each request. By populating this field with the existing transaction_id in the request body, the engineer can directly and uniquely join inference predictions with the fraud_findings table using the same identifier, achieving accurate performance monitoring with minimal code changes and no model retraining or redeployment.
NEW QUESTION # 85
A data scientist has created a Python function compute_features that returns a Spark DataFrame with the following schema:
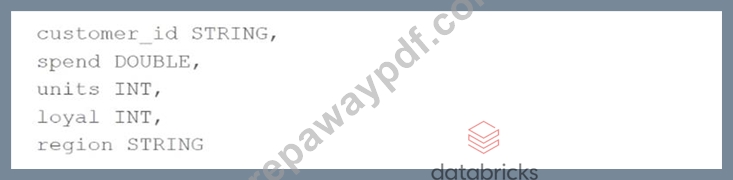
The resulting DataFrame is assigned to the features_df variable. The data scientist wants to create a Feature Store table using features_df.
Which of the following code blocks can they use to create and populate the Feature Store table using the Feature Store Client fs?
- A. features_df.write.mode("fs").path("new_table")
- B.
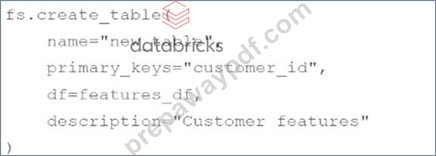
- C.
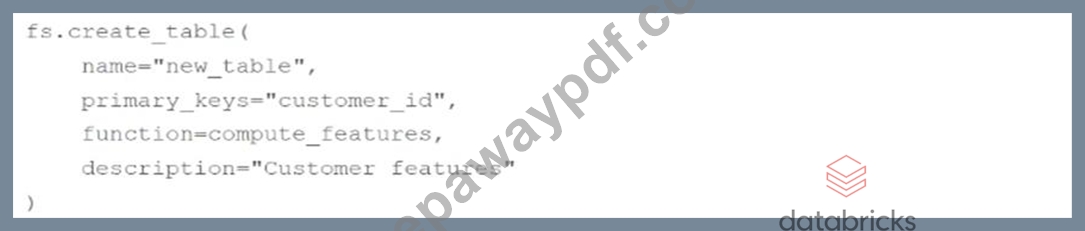
- D. features_df.write.mode("feature").path("new_table")
- E.
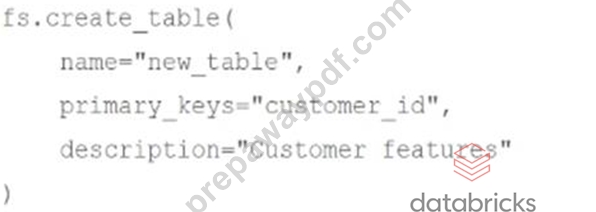
Answer: C
NEW QUESTION # 86
......
It's not easy for most people to get the Databricks-Machine-Learning-Professional guide torrent, but I believe that you can easily and efficiently obtain qualification certificates as long as you choose our products. After you choose our study materials, you can master the examination point from the Databricks-Machine-Learning-Professional Guide question. Then, you will have enough confidence to pass your exam. As for the safe environment and effective product, why don’t you have a try for our Databricks-Machine-Learning-Professional question torrent, never let you down!
Databricks-Machine-Learning-Professional Simulation Questions: https://www.prepawaypdf.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
- Databricks-Machine-Learning-Professional Reliable Exam Review 🈵 Databricks-Machine-Learning-Professional Test Passing Score 🔋 Databricks-Machine-Learning-Professional Reliable Exam Braindumps 😕 Search on ⇛ www.troytecdumps.com ⇚ for 《 Databricks-Machine-Learning-Professional 》 to obtain exam materials for free download 🧱Databricks-Machine-Learning-Professional Reliable Exam Braindumps
- Quiz High Hit-Rate Databricks - Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Latest Exam Papers 🚢 Search for ▶ Databricks-Machine-Learning-Professional ◀ on ⏩ www.pdfvce.com ⏪ immediately to obtain a free download 🧵Valid Databricks-Machine-Learning-Professional Exam Tutorial
- Latest Databricks-Machine-Learning-Professional Exam Braindumps Materials - Databricks-Machine-Learning-Professional Test Prep - www.prepawayexam.com 🥽 Open ⇛ www.prepawayexam.com ⇚ and search for ☀ Databricks-Machine-Learning-Professional ️☀️ to download exam materials for free 🧼Valid Databricks-Machine-Learning-Professional Exam Tutorial
- Databricks-Machine-Learning-Professional Latest Exam Papers - Quiz 2026 First-grade Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Simulation Questions ↔ Download ⏩ Databricks-Machine-Learning-Professional ⏪ for free by simply entering 「 www.pdfvce.com 」 website 🚀Lab Databricks-Machine-Learning-Professional Questions
- Databricks-Machine-Learning-Professional Latest Dumps Ppt 🔓 Databricks-Machine-Learning-Professional Reliable Test Review 🖐 Databricks-Machine-Learning-Professional Exam Objectives Pdf 🌋 Simply search for ➥ Databricks-Machine-Learning-Professional 🡄 for free download on ⮆ www.pdfdumps.com ⮄ 📒Databricks-Machine-Learning-Professional Reliable Exam Review
- Databricks-Machine-Learning-Professional Latest Exam Papers - Databricks First-grade Databricks-Machine-Learning-Professional Simulation Questions Pass Guaranteed 🟤 Simply search for ▶ Databricks-Machine-Learning-Professional ◀ for free download on ▶ www.pdfvce.com ◀ 🥤Databricks-Machine-Learning-Professional Exam Fee
- Databricks-Machine-Learning-Professional Pdf Exam Dump 🎦 Databricks-Machine-Learning-Professional Online Version 🌄 Databricks-Machine-Learning-Professional Exam Objectives Pdf 🧥 The page for free download of ➠ Databricks-Machine-Learning-Professional 🠰 on ➤ www.practicevce.com ⮘ will open immediately 🚴Databricks-Machine-Learning-Professional Online Version
- Databricks-Machine-Learning-Professional Reliable Exam Braindumps 🚏 Databricks-Machine-Learning-Professional Reliable Test Review 🏘 Databricks-Machine-Learning-Professional Exam Objectives Pdf 🕉 Enter { www.pdfvce.com } and search for ⏩ Databricks-Machine-Learning-Professional ⏪ to download for free 🔌Official Databricks-Machine-Learning-Professional Study Guide
- Valid Databricks-Machine-Learning-Professional Exam Tutorial 🌄 Databricks-Machine-Learning-Professional Pass Leader Dumps 🔚 Databricks-Machine-Learning-Professional Exam Fee 🤺 Easily obtain [ Databricks-Machine-Learning-Professional ] for free download through 「 www.troytecdumps.com 」 🍚Databricks-Machine-Learning-Professional Exam Objectives Pdf
- Databricks-Machine-Learning-Professional Latest Exam Papers - Databricks First-grade Databricks-Machine-Learning-Professional Simulation Questions Pass Guaranteed ✔ Copy URL ▶ www.pdfvce.com ◀ open and search for ▛ Databricks-Machine-Learning-Professional ▟ to download for free 👷Reliable Databricks-Machine-Learning-Professional Dumps Book
- New APP Databricks-Machine-Learning-Professional Simulations 🟨 Reliable Databricks-Machine-Learning-Professional Dumps Book 💸 Official Databricks-Machine-Learning-Professional Study Guide 🖍 Search for 《 Databricks-Machine-Learning-Professional 》 on ▶ www.examdiscuss.com ◀ immediately to obtain a free download 🍚Latest Databricks-Machine-Learning-Professional Braindumps Files
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=135h-8xej4tlBraPVoPFu_x7lryo5L9EO