Databricks-Certified-Data-Engineer-Professional最新試験情報、Databricks-Certified-Data-Engineer-Professional試験概要

さらに、Xhs1991 Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12DdpnwfaqJP2bSVLfE9FwfMs2g9YyFoC
Xhs1991のDatabricksのDatabricks-Certified-Data-Engineer-Professionalの試験問題と解答はあなたが受験する前にすべての必要とした準備資料を提供しています。DatabricksのDatabricks-Certified-Data-Engineer-Professionalの認証試験について、あなたは異なるサイトや書籍で色々な問題を見つけることができます。しかし、ロジックが接続されているかどうかはキーです。Xhs1991の問題と解答は初めに試験を受けるあなたが気楽に成功することを助けるだけではなく、あなたの貴重な時間を節約することもできます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
|
| Topic 2: Delta Lake and Data Management | - Schema evolution and enforcement
- Time travel and versioning
- Delta Lake transactions and ACID properties
|
| Topic 3: Data Modeling and Transformation | - Spark SQL transformations
- Performance optimization techniques
- Dimensional modeling concepts
|
| Topic 4: Data Ingestion and Processing | - ETL pipeline design patterns
- Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
|
| Topic 5: Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
>> Databricks-Certified-Data-Engineer-Professional最新試験情報 <<
Databricks-Certified-Data-Engineer-Professional試験概要 & Databricks-Certified-Data-Engineer-Professional専門トレーリング
多くの会社はDatabricks認証の有無によって社員の給料が違います。それに、Databricks-Certified-Data-Engineer-Professional試験に参加したことがない人にとって、これはいい挑戦です。我々の更新された問題集は多くの受験者を助けました。あなたはDatabricks-Certified-Data-Engineer-Professional試験を準備しているなら、我々の最新の問題集を利用して復習することができます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q33-Q38):
質問 # 33
A table named user_ltv is being used to create a view that will be used by data analysts on Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
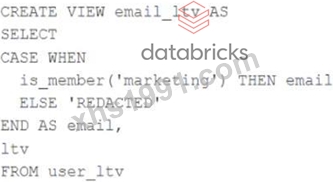
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- B. Only the email and itv columns will be returned; the email column will contain all null values.
- C. The email and ltv columns will be returned with the values in user itv.
- D. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - E. The email, age. and ltv columns will be returned with the values in user ltv.
正解:D
解説:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
質問 # 34
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- B. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- C. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- D. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- E. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
正解:D
質問 # 35
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
- A. Create external locations and storage credentials to connect to each database, then register foreign tables in Unity Catalog.
- B. Configure connections and foreign catalog in Unity Catalog, then grant access to foreign catalogs, schemas, and tables using Unity Catalog permissions.
- C. Mirror the external datasets into Delta Lake using Auto Loader, and govern them using Data Lineage and System Tables.
- D. Use Partner Connect to create linked datasets, and apply table ACLs at the source system to govern access through Databricks.
正解:B
解説:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
質問 # 36
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- E. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
正解:E
解説:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
質問 # 37
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
- A. import sys
date = sys.argv[1] - B. date = spark.conf.get("date")
- C. dbutils.widgets.text("date", "null")
date = dbutils.widgets.get("date") - D. date = dbutils.notebooks.getParam("date")
- E. input_dict = input()
date= input_dict["date"]
正解:C
解説:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter.
For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
質問 # 38
......
状況によってはあなたを助けたり破ったりすることができるこの運命的な試験について、当社はこれらのDatabricks-Certified-Data-Engineer-Professional練習資料を説明責任を持って作成しました。他の場所に受け入れられる可能性が高くなり、より高い給料や受け入れが得られることを理解しています。 Databricks-Certified-Data-Engineer-Professionalトレーニング資料は当社の責任会社によって作成されているため、他の多くのメリットも得られます。参考のために無料のデモを提供し、専門家が自由に作成できる場合は新しいアップデートをお送りします。
Databricks-Certified-Data-Engineer-Professional試験概要: https://www.xhs1991.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional資格勉強 🧘 Databricks-Certified-Data-Engineer-Professional受験内容 🕯 Databricks-Certified-Data-Engineer-Professionalテストサンプル問題 🔂 ▶ jp.fast2test.com ◀サイトにて➤ Databricks-Certified-Data-Engineer-Professional ⮘問題集を無料で使おうDatabricks-Certified-Data-Engineer-Professional認定資格試験
- Databricks-Certified-Data-Engineer-Professional受験内容 👡 Databricks-Certified-Data-Engineer-Professional最新受験攻略 🤖 Databricks-Certified-Data-Engineer-Professionalテストサンプル問題 🐵 ウェブサイト☀ www.goshiken.com ️☀️を開き、[ Databricks-Certified-Data-Engineer-Professional ]を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional関連復習問題集
- 試験の準備方法-実際的なDatabricks-Certified-Data-Engineer-Professional最新試験情報試験-認定するDatabricks-Certified-Data-Engineer-Professional試験概要 🌭 ➽ www.mogiexam.com 🢪サイトで[ Databricks-Certified-Data-Engineer-Professional ]の最新問題が使えるDatabricks-Certified-Data-Engineer-Professional復習対策書
- Databricks-Certified-Data-Engineer-Professional日本語版復習資料 🌺 Databricks-Certified-Data-Engineer-Professional資格勉強 🔵 Databricks-Certified-Data-Engineer-Professional専門トレーリング 🆗 URL ▷ www.goshiken.com ◁をコピーして開き、☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional模擬問題
- Databricks-Certified-Data-Engineer-Professional模擬体験 🎱 Databricks-Certified-Data-Engineer-Professional問題サンプル 🌒 Databricks-Certified-Data-Engineer-Professional日本語版サンプル 🦝 ⏩ www.mogiexam.com ⏪に移動し、【 Databricks-Certified-Data-Engineer-Professional 】を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional模擬問題
- 効率的なDatabricks-Certified-Data-Engineer-Professional最新試験情報と信頼的なDatabricks-Certified-Data-Engineer-Professional試験概要 🔍 [ www.goshiken.com ]は、➥ Databricks-Certified-Data-Engineer-Professional 🡄を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional模擬問題
- 試験の準備方法-実際的なDatabricks-Certified-Data-Engineer-Professional最新試験情報試験-認定するDatabricks-Certified-Data-Engineer-Professional試験概要 🏅 ▶ www.mogiexam.com ◀で☀ Databricks-Certified-Data-Engineer-Professional ️☀️を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Engineer-Professional模擬体験
- Databricks-Certified-Data-Engineer-Professional受験内容 🍹 Databricks-Certified-Data-Engineer-Professional受験内容 🔬 Databricks-Certified-Data-Engineer-Professionalテストサンプル問題 🥤 ▶ www.goshiken.com ◀を開き、⮆ Databricks-Certified-Data-Engineer-Professional ⮄を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語認定対策
- Databricks-Certified-Data-Engineer-Professional必殺問題集 🏂 Databricks-Certified-Data-Engineer-Professional日本語試験情報 🙉 Databricks-Certified-Data-Engineer-Professional模擬問題 ⛄ URL ➠ www.passtest.jp 🠰をコピーして開き、⮆ Databricks-Certified-Data-Engineer-Professional ⮄を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語版サンプル
- 効果的なDatabricks-Certified-Data-Engineer-Professional最新試験情報試験-試験の準備方法-素敵なDatabricks-Certified-Data-Engineer-Professional試験概要 🦓 ✔ www.goshiken.com ️✔️サイトにて最新☀ Databricks-Certified-Data-Engineer-Professional ️☀️問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional資格勉強
- Databricks-Certified-Data-Engineer-Professional最新受験攻略 🌗 Databricks-Certified-Data-Engineer-Professional最新受験攻略 🌋 Databricks-Certified-Data-Engineer-Professional最新受験攻略 🧜 ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️を無料でダウンロード▛ www.it-passports.com ▟ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional日本語認定対策
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S.Xhs1991がGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=12DdpnwfaqJP2bSVLfE9FwfMs2g9YyFoC