Exam Databricks-Machine-Learning-Professional Overviews, Databricks-Machine-Learning-Professional Training Solutions

2026 Latest BraindumpsPrep Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=1M6ARNvK5FXR5PfrsrvEWZQdxNlR7g7AD
In some respects, it is a truth that processional certificates can show your capacity in a working environment. If you pay your limited time to practice with our Databricks-Machine-Learning-Professional study braindumps, you can learn how to more effectively create value and learn more knowledge the exam want to test for you. We promise it is our common goal to get it and we are trustworthy materials company you cannot miss this time.
| Topic | Details |
|---|
| Topic 1 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 2 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 3 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 4 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 5 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 6 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 7 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 8 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
>> Exam Databricks-Machine-Learning-Professional Overviews <<
Databricks-Machine-Learning-Professional Training Solutions | Latest Databricks-Machine-Learning-Professional Study Notes
We would like to benefit our customers from different countries who decide to choose our Databricks-Machine-Learning-Professional study guide in the long run, so we cooperation with the leading experts in the field to renew and update our study materials. Our leading experts aim to provide you the newest information in this field in order to help you to keep pace with the times and fill your knowledge gap. We can assure you that you will get the latest version of our Databricks-Machine-Learning-Professional Training Materials for free from our company in the whole year after payment. Do not miss the opportunity to buy the best Databricks-Machine-Learning-Professional preparation questions in the international market which will also help you to advance with the times.
Databricks Certified Machine Learning Professional Sample Questions (Q100-Q105):
NEW QUESTION # 100
A Machine Learning Engineer is using Lakehouse Monitoring to track the performance of ML models deployed in their environment. They want to monitor significant distributional drift in categorical features with a metric bounded on [0,1] for easy interpretation. Which statistical method should they use?
- A. Jensen-Shannon Distance
- B. Kolmogorov-Smirnov Test
- C. Kullback-Leibler Distance
- D. Wasserstein Distance
Answer: A
NEW QUESTION # 101
A data scientist has run the following line of code to create a Feature Store table:
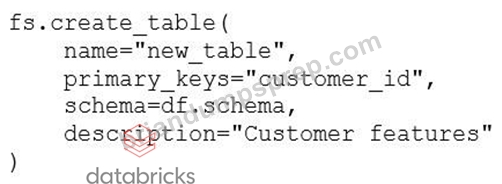
Which statement correctly describes the data in the Feature Store table new_table?
- A. There is no data in new_table
- B. The data in new_table is the values in column customer_id from df
- C. The data in new_table is exactly the same as the data in df
- D. The data in new_table is the customer-related features from df
Answer: A
Explanation:
The fs.create_table() command defines metadata for a Feature Store table, such as its name, primary key, schema, and description - but it does not insert any data into the table. This command simply registers an empty table structure based on the provided schema (df.schema).
To populate the table with data, a separate fs.write_table() or equivalent write operation must be executed afterward.
NEW QUESTION # 102
A Machine Learning Engineer is setting up a cluster for a deep learning training run, but has a number of settings options to choose from. Their cluster will be reused by other engineers on their team and their datasets vary in size from hundreds of MBs to hundreds of GBs. They need to choose a configuration that allows for performant, stable deep learning training without excessive costs. Which configuration will do this?
- A. Using Databricks Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
- B. Using ML Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
- C. Using ML Runtime, use a moderate sized GPU VM for the driver and a variable number of memory optimized CPU VMs for the workers with autoscale enabled
- D. Using ML Runtime, use a large single node, GPU-enabled VM with auto termination set to 20 minutes to reduce costs
Answer: B
Explanation:
Using the ML Runtime ensures deep learning frameworks and GPU drivers are preconfigured and optimized. A moderately sized CPU driver is sufficient for coordination, while GPU-enabled worker nodes handle the computationally intensive training workload. Enabling autoscaling allows the cluster to efficiently adapt to datasets ranging from hundreds of megabytes to hundreds of gigabytes, providing strong performance without overprovisioning and controlling costs in a shared team environment.
NEW QUESTION # 103
A Data Scientist needs to analyze drift detection results from Databricks Lakehouse Monitoring.
The system has generated both profile metrics and drift metrics tables. The scientist needs to identify baseline drift in numerical features by comparing current data against a baseline from 6 months ago. Which combination of table columns and values indicates baseline drift in a numerical feature?
- A. window_cmp pointing to baseline time window and tv_distance > 0.5 with any drift_type value.
- B. drift_type = "BASELINE", chi_squared_test.p_value < 0.05, and js_distance > 0.2.
- C. drift_type = "BASELINE", ks_test.p_value < 0.05, and wasserstein_distance > 0.1.
- D. log_type = "BASELINE" in profile metrics table with population_stability_index > 0.2 in drift metrics table.
Answer: C
Explanation:
Baseline drift is identified in the drift metrics table by setting drift_type to BASELINE, and for numerical features the drift statistics are the KS test (ks_test with a p-value indicating a statistically significant distribution change) and a numeric distance metric such as wasserstein_distance.
NEW QUESTION # 104
A machine learning engineer has developed a random forest model using scikit-learn and registered the model using MLflow. They now want to deploy that model in parallel. Which of the following operations can they use to create a function they can use to deploy the registered scikit- learn model in parallel?
- A. mlflow.pyfunk.spark.udf
- B. It is not possible to deploy a scikit-learn model in parallel.
- C. mlflow.spark.pandas_udf
- D. mlflow.sklearn.spark.udf
Answer: D
Explanation:
The correct operation is mlflow.sklearn.spark_udf, which creates a Spark UDF from a registered scikit-learn model. This allows the model to be applied in parallel across a Spark DataFrame, enabling scalable batch inference using Spark.
NEW QUESTION # 105
......
As the name suggests,web-based Databricks Databricks-Machine-Learning-Professional practice tests are internet-based. This practice test is appropriate for usage via any operating system such as Mac, iOS, Windows, Android, and Linux which helps you clearing Databricks Databricks-Machine-Learning-Professional exam. All characteristics of the Windows-based CERT NAME practice exam software are available in it which is necessary for Databricks Databricks-Machine-Learning-Professional Exam. No special plugins or software installation is compulsory to attempt the web-based Databricks Databricks-Machine-Learning-Professional practice tests. In addition, the online mock test is supported by all browsers.
Databricks-Machine-Learning-Professional Training Solutions: https://www.briandumpsprep.com/Databricks-Machine-Learning-Professional-prep-exam-braindumps.html
- Latest Databricks-Machine-Learning-Professional Exam Cram 🤚 Latest Databricks-Machine-Learning-Professional Test Pdf 🤭 Latest Databricks-Machine-Learning-Professional Exam Practice ⬜ Search for ➽ Databricks-Machine-Learning-Professional 🢪 and obtain a free download on ▛ www.dumpsmaterials.com ▟ 💒Latest Databricks-Machine-Learning-Professional Exam Practice
- Free Databricks-Machine-Learning-Professional Download 🍔 Valid Databricks-Machine-Learning-Professional Exam Camp Pdf 🔪 New Databricks-Machine-Learning-Professional Exam Topics 🧈 Enter ⏩ www.pdfvce.com ⏪ and search for ⏩ Databricks-Machine-Learning-Professional ⏪ to download for free 🤳Databricks-Machine-Learning-Professional Trusted Exam Resource
- Databricks-Machine-Learning-Professional Valid Exam Simulator 🙇 Databricks-Machine-Learning-Professional Vce Files 🌠 Free Databricks-Machine-Learning-Professional Download 🕞 ⇛ www.practicevce.com ⇚ is best website to obtain ➥ Databricks-Machine-Learning-Professional 🡄 for free download 🐙Databricks-Machine-Learning-Professional Test Vce
- Dumps Databricks-Machine-Learning-Professional Download ⛪ Valid Databricks-Machine-Learning-Professional Exam Camp Pdf 💛 Databricks-Machine-Learning-Professional Valid Exam Simulator 🟪 Download ⮆ Databricks-Machine-Learning-Professional ⮄ for free by simply entering ➤ www.pdfvce.com ⮘ website 📫New Databricks-Machine-Learning-Professional Exam Topics
- New Databricks-Machine-Learning-Professional Exam Topics ⛰ Databricks-Machine-Learning-Professional Test Vce ⚫ Databricks-Machine-Learning-Professional Test Vce 🖍 Open ✔ www.vceengine.com ️✔️ and search for { Databricks-Machine-Learning-Professional } to download exam materials for free 🐤Databricks-Machine-Learning-Professional Trusted Exam Resource
- New Databricks-Machine-Learning-Professional Exam Topics ▶ Latest Databricks-Machine-Learning-Professional Test Pdf 🆒 Exam Databricks-Machine-Learning-Professional Prep 🧺 Immediately open ➡ www.pdfvce.com ️⬅️ and search for ▷ Databricks-Machine-Learning-Professional ◁ to obtain a free download 📽Exam Databricks-Machine-Learning-Professional Quizzes
- Make Exam Preparation Simple www.validtorrent.com Real Databricks Databricks-Machine-Learning-Professional Exam Questions 🧶 Copy URL “ www.validtorrent.com ” open and search for ☀ Databricks-Machine-Learning-Professional ️☀️ to download for free 🤦Databricks-Machine-Learning-Professional Test Vce
- Databricks-Machine-Learning-Professional exam dumps and Databricks Databricks-Machine-Learning-Professional exam Simulator 🍄 The page for free download of ➤ Databricks-Machine-Learning-Professional ⮘ on ⮆ www.pdfvce.com ⮄ will open immediately 🤏Certification Databricks-Machine-Learning-Professional Exam Dumps
- Databricks-Machine-Learning-Professional Test Dumps Pdf 🐻 Test Databricks-Machine-Learning-Professional Free 🥏 Test Databricks-Machine-Learning-Professional Free 🛌 Simply search for ➥ Databricks-Machine-Learning-Professional 🡄 for free download on { www.exam4labs.com } 🐺Latest Databricks-Machine-Learning-Professional Test Pdf
- Reliable Exam Databricks-Machine-Learning-Professional Overviews - Leader in Qualification Exams - Correct Databricks Databricks Certified Machine Learning Professional ⚪ Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and easily obtain a free download on ( www.pdfvce.com ) 🍃Exam Databricks-Machine-Learning-Professional Quizzes
- Pass Guaranteed 2026 Trustable Databricks Exam Databricks-Machine-Learning-Professional Overviews 🥉 Simply search for ⮆ Databricks-Machine-Learning-Professional ⮄ for free download on ▛ www.easy4engine.com ▟ 🧮Practice Databricks-Machine-Learning-Professional Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, backloggd.com, issuu.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of BraindumpsPrep Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1M6ARNvK5FXR5PfrsrvEWZQdxNlR7g7AD