We offer you free demo for you to have a try before buying the DP-750 study guide, so that you can have a better understanding of what you are going to buy. DP-750 exam dumps of us also offer you free update for one year after purchasing, and our system will send the latest version to you automatically. Besides we have the online and offline chat service stuff, and if you have any questions about the DP-750 Study Guide, you can consult them, and they will offer you the suggestions.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
>> New Exam Microsoft DP-750 Braindumps <<
Successful people are those who are willing to make efforts. If you have never experienced the wind and rain, you will never see the rainbow. Giving is proportional to the reward. Now, our DP-750 study materials just need you spend less time, then your life will take place great changes. Maybe you think that our DP-750 study materials cannot make a difference. But you must know that if you do not have a try, your life will never be improved. It is useless that you speak boast yourself but never act. Please muster up all your courage. No one will laugh at a hardworking person. Our DP-750 Study Materials are your good study partner.
NEW QUESTION # 13
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.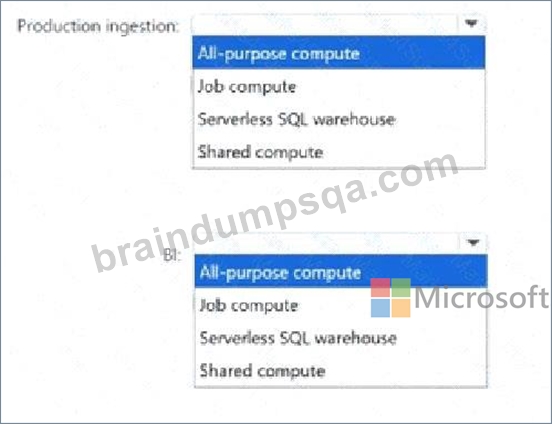
Answer:
Explanation: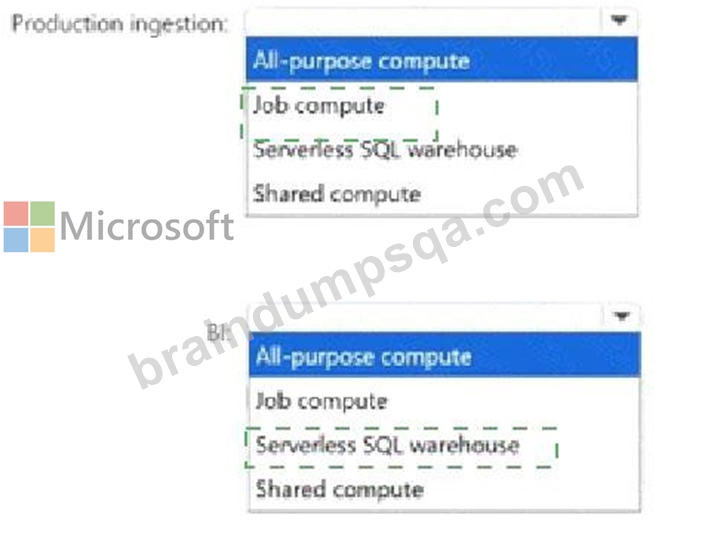
Explanation:
Production ingestion: Job compute
BI: Serverless SQL warehouse
Job compute is designed for automated production workloads executed through Lakeflow Jobs. Its lifecycle can be tied to the job run, providing workload isolation and avoiding the cost of maintaining an interactive all- purpose cluster continuously. It is therefore appropriate for scheduled ingestion and transformation processing. A serverless SQL warehouse is designed for BI and Databricks SQL workloads. It provides rapid startup, automatic infrastructure management, scaling, and optimized SQL-query execution for dashboards and reporting tools. All-purpose compute is intended primarily for interactive notebook development and exploration, while shared compute does not provide the same job-specific isolation or SQL-serving experience. Consequently, job compute should support production ingestion, and a serverless SQL warehouse should serve the BI workload.
NEW QUESTION # 14
Which feature helps reduce data scan during query execution in Delta Lake?
Answer: C
Explanation:
Delta Lake uses data skipping based on file-level statistics (min/max values). This reduces unnecessary file scans and improves query performance. VACUUM removes old files but does not improve query speed. Cluster restart has no impact on query optimization.
NEW QUESTION # 15
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluster1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
The best action is uploading the libraries to the workspace and installing the libraries on the cluster (or ideally uploading them to Unity Catalog volumes).
Unity Catalog Compatibility: When using Unity Catalog for access control, compute clusters are typically configured with Standard (Shared) access mode. In this mode, traditional cluster init scripts [Not B.] face strict execution restrictions or are completely blocked to maintain secure user isolation.
Governance: Uploading your packages as Workspace Files or to Unity Catalog volumes allows administrators to manage access permissions directly and add them to an allowlist if needed.
Cluster-Wide Availability: Installing the libraries via the cluster's Libraries tab ensures that the required ingestion packages are automatically pre-installed and available across all nodes and notebooks running on that cluster.
Incorrect:
[Not A]
Running pip3 install manually on a cluster terminal or inside a notebook only applies to the specific notebook session (notebook-scoped). It does not natively persist across cluster restarts or handle cross-node execution effectively for data ingestion pipelines.
[Not B]
Running a custom script or a legacy init script to modify system-level paths introduces security risks and is generally incompatible with Unity Catalog's strict execution isolation policies for shared compute.
Reference:
https://docs.databricks.com/aws/en/libraries/
NEW QUESTION # 16
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.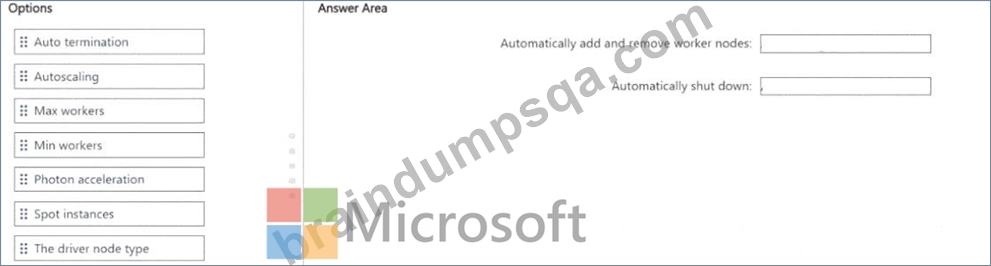
Answer:
Explanation: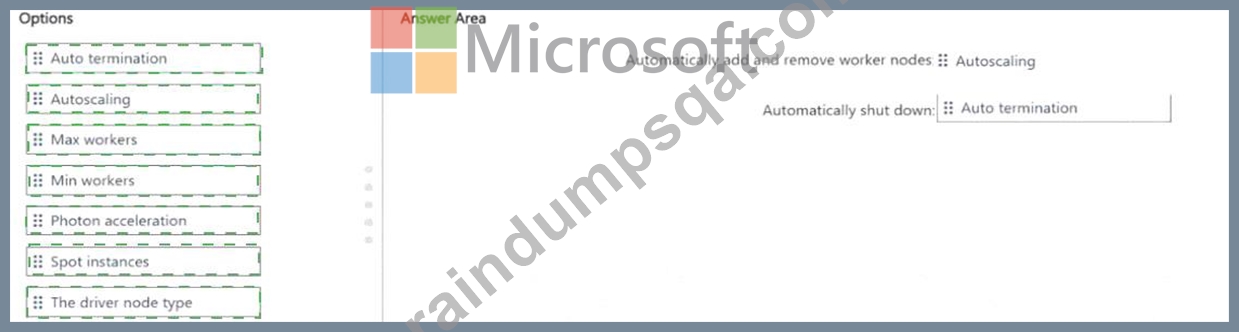
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 17
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
NEW QUESTION # 18
......
Braindumpsqa provide you with the comprehensive Microsoft DP-750 Exam information to help you to succeed. Our training materials are the latest study materials which bring by experts. We help you achieve your success. You can get the most detailed and accurate exam questions and answers from us. Our Training Tools are updated in a timely manner in accordance with the changing of Exam Objectives. In fact, the success is not far away, go down along with Braindumpsqa, then you will come to the road to success.
DP-750 Exam Simulations: https://www.braindumpsqa.com/DP-750_braindumps.html