BONUS!!! Download part of Pass4sureCert AI-300 dumps for free: https://drive.google.com/open?id=1TjeSvHSJ8q6EGtVvulnPin2EW4g5lior
Microsoft AI-300 reliable tes prep is the right study reference for your test preparation. The comprehensive AI-300 questions & answers are in accord with the knowledge points of the real exam. Furthermore, AI-300 sure pass exam will give you a solid understanding of how to conquer the difficulties in the real test. The mission of Pass4sureCert AI-300 PDF VCE is to give you the most valid study material and help you pass with ease.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Topic 2: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
>> AI-300 Reliable Test Price <<
Challenges are omnipresent everywhere. This challenge of AI-300 practice exam is something you do not need to be anxious with our AI-300 practice materials. If you make choices on practice materials with untenable content, you may fail the exam with undesirable outcomes. Our Operationalizing Machine Learning and Generative AI Solutions practice materials are totally to the contrary. Confronting obstacles or bottleneck during your process of reviewing, AI-300 practice materials will fix all problems of the exam and increase your possibility of getting dream opportunities dramatically.
NEW QUESTION # 68
Hotspot Question
A team is provisioning a new Azure Machine Learning workspace for a production project.
The workspace must support secure secret storage and operational monitoring. The team requires the workspace to be created with the correct dependent resources to meet security and monitoring requirements.
You need to configure the required dependencies when the team creates the workspace.
Which resources should you associate with the workspace? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.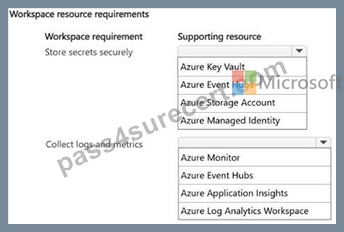
Answer:
Explanation: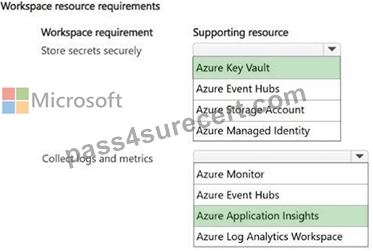
NEW QUESTION # 69
Hotspot Question
You manage an Azure OpenAI deployment of the gpt-4o base model.
You plan to fine-tune the deployed model.
You need to prepare a file that contains training data.
Which keys should you include in each line of the training data file? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.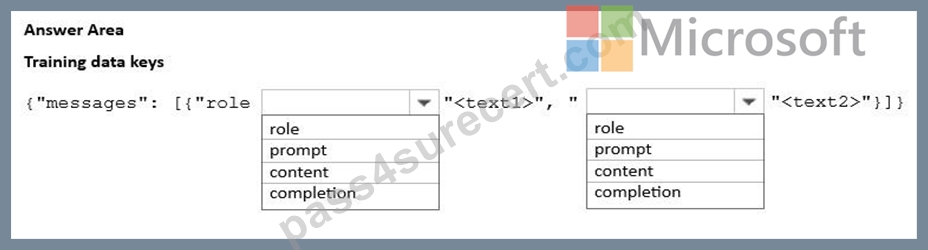
Answer:
Explanation: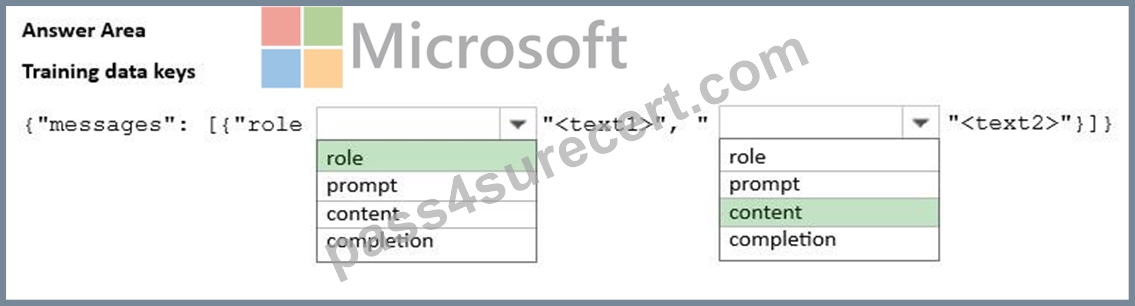
Explanation:
For fine-tuning conversational models like gpt-4o on Azure OpenAI, the training file must be formatted in a JSON Lines (.jsonl) file, where each line represents a single training conversation.
Each line must strictly contain a messages key wrapping an array of message objects.
Box 1: role
role: Defines the sender of the message. The accepted strings for fine-tuning are "system",
"user", or "assistant".
Box 2: content
content: Contains the actual text string or multi-modal payload of the message.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/openai/how-to/reinforcement-fine-tuning
NEW QUESTION # 70
A team manages an Azure Machine Learning workspace and deploys a model to an endpoint.
A deployed online endpoint shows inconsistent response times during periods of high traffic.
You need to identify potential performance degradation.
Which three metrics should you monitor? Each correct answer presents part of the solution.
Choose three.
NOTE: Each correct selection is worth one point.
Answer: A,B,C
Explanation:
To locate potential performance degradation in an Azure Machine Learning online endpoint during high traffic, you should monitor these three metrics:
Requests per minute: This metric tracks the volume of incoming traffic and helps identify if spikes in load correlate with slower response times.
Connections active: This monitors the total number of concurrent TCP connections from clients, which can indicate if the endpoint is reaching its capacity limits during peak periods.
Request latency: This directly measures the time taken to respond to requests, allowing you to observe exactly when and by how much performance is degrading.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-deploy-a-machine-learning-model-as-a-real- time-endpoint-in-azure-machine-learning/view
NEW QUESTION # 71
An organization is deploying several generative AI workloads by using Microsoft Foundry. Each workload must meet different requirements related to data governance, task specialization, and operational cost control.
The organization requires models that meet the following requirements:
Model behavior aligns with the task being performed.
Data handling aligns with internal governance policies.
Operational complexity and cost are justified by workload needs.
You need to select the foundation model options that meet the requirements.
Which three models can you select? Each correct answer presents a complete solution. NOTE: Each correct selection is worth one point. Choose three .
Answer: A,C,E
Explanation:
Microsoft ' s foundation model selection documentation emphasizes right-sizing: choose models based on task alignment, data governance, and justified operational cost rather than defaulting to the largest or smallest available. A model optimized for conversational reasoning (option A) is correctly matched to an interactive assistant workload. A model supporting multiple input types (option D) is correctly matched to workloads combining text and image analysis. A model offering enterprise governance controls (option E) is correctly matched to workloads processing regulated business data. The largest available model (option B) is not recommended simply for operational simplicity - it adds unnecessary cost without justification. The smallest available model (option C) may fail quality thresholds for complex workloads. The correct selections are the models that align with actual task requirements, governance needs, and cost justification.
Microsoft Learn Reference Topic: Select foundation models in Microsoft Foundry - Task alignment, governance, and cost optimization
NEW QUESTION # 72
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Configure Azure Monitor to collect logs from the workspace. Use the logs to perform prompt evaluation.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Configure Azure Monitor to collect logs from the workspace. Use the logs to perform prompt evaluation.
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing-taneja-mbwze
NEW QUESTION # 73
......
Microsoft AI-300 learning materials are new but increasingly popular choices these days which incorporate the newest information and the most professional knowledge of the practice exam. All points of questions required are compiled into our Operationalizing Machine Learning and Generative AI Solutions AI-300 Preparation quiz by experts. By the way, the AI-300certificate is of great importance for your future and education.
AI-300 Latest Guide Files: https://www.pass4surecert.com/Microsoft/AI-300-practice-exam-dumps.html
BTW, DOWNLOAD part of Pass4sureCert AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1TjeSvHSJ8q6EGtVvulnPin2EW4g5lior