BTW, DOWNLOAD part of itPass4sure HPE7-J01 dumps from Cloud Storage: https://drive.google.com/open?id=1swSxmqyAaKKTFS4F-Z4RhelEd__P-dI9
In the era of informational globalization, the world has witnessed climax of science and technology development, and has enjoyed the prosperity of various scientific blooms. In 21st century, every country had entered the period of talent competition, therefore, we must begin to extend our HPE7-J01 personal skills, only by this can we become the pioneer among our competitors. We here tell you that there is no need to worry about. Our HPE7-J01 Actual Questions are updated in a high speed. Since the date you pay successfully, you will enjoy the HPE7-J01 test guide freely for one year, which can save your time and money. We will send you the latest HPE7-J01 study dumps through your email, so please check your email then.
| Section | Weight | Objectives |
|---|---|---|
| Storage Architecture and Design | 30% | - HPE storage portfolio architecture
|
| Management and Optimization | 15% | - Monitoring and administration
|
| Emerging Technologies and Solutions | 10% | - Hybrid cloud and multi-cloud storage
|
| Data Protection and Availability | 25% | - High availability solutions
|
| Deployment and Integration | 20% | - Networking and connectivity
|
>> HPE7-J01 Valid Exam Braindumps <<
The itPass4sure is a leading platform that offers real, valid, and subject matter expert's verified HPE7-J01 exam questions. These HPE7-J01 exam practice questions are particularly designed for fast Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam preparation. The itPass4sure HPE7-J01 exam questions are designed and verified by experienced and qualified HP HPE7-J01 Exam trainers. They work together and put all their expertise and experience to ensure the top standard of itPass4sure HPE7-J01 exam practice questions all the time.
NEW QUESTION # 68
An HPE customer purchased an HPE B-Series SN7000B SAN fabric switch. QoS is currently not enabled.
Which two statements are correct regarding buffer-to-buffer (BB) credits and the operation of the switch?
(Choose two.)
Answer: A,E
Explanation:
The HPE B-Series SN7000B is a high-performance Director based on Brocade Gen 7 (G7) technology.
Buffer-to-Buffer (BB) credits are the fundamental flow-control mechanism used in Fibre Channel to prevent frame loss and manage congestion.
Statement D is a foundational principle of SAN architecture: BB credits are based on link speed and frame size. In an FC fabric, the number of credits required to "fill the pipe" (keep data moving without waiting for acknowledgments) is a direct function of the Round Trip Time (RTT), which is determined by the physical distance, the speed of the link (e.g., 64Gb/s vs 32Gb/s), and the size of the frames being sent (typically 2KB).
As link speeds increase, more buffer credits are required to maintain full throughput over the same distance.
Statement C reflects a specific technical default in the Brocade Fabric OS (FOS) for Gen 7 hardware. To ensure that ports can initialize and handle basic traffic immediately upon being enabled, the switch reserves a default number of credits from the ASIC's global buffer pool. For user ports on these high-density blades, the system reserves eight buffer credits per port, regardless of whether the port is currently online or offline.
This reservation ensures that the port has the minimum resources necessary to complete a fabric login (FLOGI) or negotiate a link without competing for pool resources.
Option E is incorrect because the entire pool is not reserved; a significant portion of the ASIC's buffers remains in a "shared pool" that can be dynamically allocated for long-distance links or high-demand ports via the "Extended Fabrics" feature. Option B is incorrect as it confuses the TCP windowing concept with FC credit-based flow control. Option A is incorrect because BB credits are a local port-to-port negotiation (link- level) and do not need a fabric-wide global "agreement" to form the fabric.
NEW QUESTION # 69
A customer is planning a new mission-critical database deployment requiring synchronous replication between two metropolitan data centers separated by 40 km. The solution must provide zero data loss and automatic failover while minimizing application downtime. Which HPE storage technology best meets these requirements?
Answer: A
Explanation:
HPE Primera Active Peer Persistence enables active-active synchronous replication across metro distances, delivering zero RPO and near-zero RTO. It supports transparent automatic failover, which is ideal for mission-critical workloads. Asynchronous solutions introduce data-loss risk, while StoreOnce and MSA replication do not provide this enterprise-grade availability model.
NEW QUESTION # 70
An HPE Partner is sizing an Alletra MP B10000 array for a customer using the HPE Ninja Sizer online tool.
When tuning the solution, the partner is not getting the best read and write performance from the array.
Use your cursor to place a + where the partner can click in the web GUI to begin to determine how to correct this Issue and appropriately size the solution for the customer.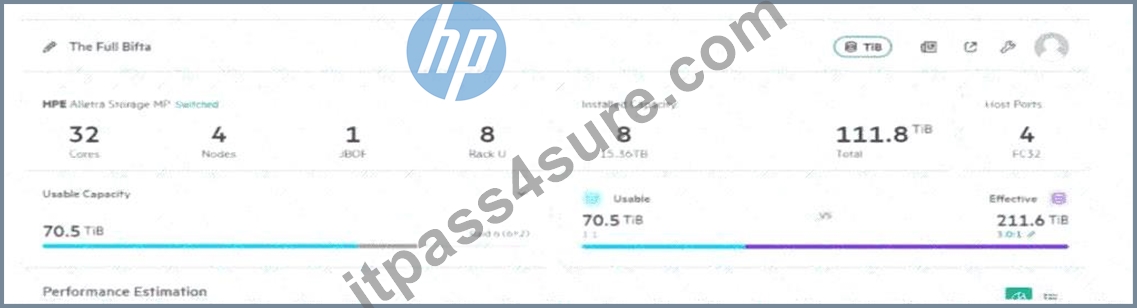
Answer:
Explanation: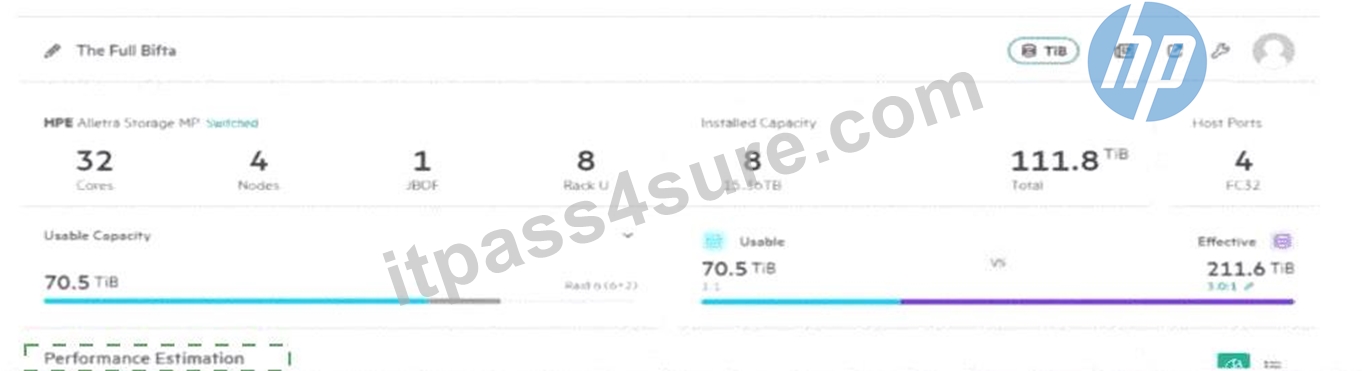
Explanation:
Performance Estimation
The HPE Ninja Sizer is a vital tool for storage architects to model the "Performance vs. Capacity" trade-offs of the HPE Alletra MP B10000 disaggregated architecture. In this scenario, the current configuration (as shown in the exhibit) consists of 4 nodes and 1 JBOF (with 8 drives of 15.36TB each).
To address poor read/write performance in Ninja Sizer, the partner must analyze the Performance Estimation pane. By clicking the chart/graph icon in the bottom right of the summary dashboard, the tool opens a detailed breakdown of the IOPS, throughput, and latency limits for the selected hardware. In a disaggregated shared-everything (DASE) architecture like the Alletra MP, performance is a direct function of the "node-to- drive" ratio. A configuration with only 8 drives (as seen in image_6491d0.png) may be "disk-bound," meaning the controllers have more compute power than the backend drive count can support in parallel.
By accessing the performance details, the partner can see if the bottleneck is at the node level (CPU/Cores) or the drive level (Flash bandwidth). To "correct this issue" and optimize the sizing, the partner would typically need to increase the drive count within the JBOF to allow for more parallel I/O streams or add additional JBOFs to scale the backend bandwidth. The Ninja Sizer provides real-time feedback; as the partner adds more
15.36TB drives, they will see the Performance Estimation bars move from yellow/red toward green, indicating an appropriately balanced solution that meets the customer's latency and throughput SLAs.
NEW QUESTION # 71
An HPE Partner is designing a software-defined storage (SDS) solution that includes HPE Alletra
4000 storage servers and the HPE Ezmeral Data Fabric software solution. The customer wants to manage the HPE Alletra 4000 storage servers using HPE GreenLake. Which component in HPE GreenLake should the customer use?
Answer: B
Explanation:
The HPE Alletra 4000 series (specifically the Alletra 4110 and 4120) are technically classified as Storage Servers. Unlike traditional "closed" storage arrays like the Alletra 6000 or 9000, the Alletra 4000s are open platforms derived from the HPE Apollo lineage, designed to run Software- Defined Storage (SDS) stacks such as HPE Ezmeral Data Fabric, Scality, or Qumulo. Because these systems are fundamentally high-density servers, their lifecycle management--including firmware updates (BIOS, iLO, controllers), health monitoring, and remote configuration--is integrated into the HPE GreenLake for Compute Ops Management (COM) service. COM provides a cloud-native console designed specifically for server administrators to manage fleets of ProLiant and Alletra 4000 servers from a single pane of glass.
NEW QUESTION # 72
An administrator needs to use a plug-in to provide monitoring of the performance of applications, servers, databases, tools, and services through an SaaS-based data analytics platform. Which Morpheus plug-in should the administrator install?
Answer: D
Explanation:
HPE Morpheus Enterprise provides extensive native monitoring for provisioned resources, but for deep, full-stack observability into applications, databases, and third-party services via a specialized SaaS- based analytics platform, it integrates with external providers through plugins.
The Datadog Integration Plugin is a primary example of this capability. Datadog is an industry- leading SaaS data analytics platform that monitors performance across every layer of the stack-- from infrastructure metrics to application traces and logs. By installing the Datadog plugin in Morpheus, the administrator bridges the gap between the orchestration engine (Morpheus) and the observability platform (Datadog). This plugin adds a contextual "Datadog" tab to instances within the Morpheus UI, pulling real-time performance telemetry directly from the SaaS backend into the Morpheus management pane. This allows the administrator to view workload health and deep-dive analytics without switching consoles.
NEW QUESTION # 73
......
We are pleased to inform you that we have engaged in this business for over ten years with our HPE7-J01 exam questions. Because of our past years’ experience, we are well qualified to take care of your worried about the HPE7-J01 Preparation exam and smooth your process with successful passing results. Our pass rate of the HPE7-J01 study materials is high as 98% to 100% which is unique in the market.
New HPE7-J01 Study Guide: https://www.itpass4sure.com/HPE7-J01-practice-exam.html
P.S. Free & New HPE7-J01 dumps are available on Google Drive shared by itPass4sure: https://drive.google.com/open?id=1swSxmqyAaKKTFS4F-Z4RhelEd__P-dI9