What's more, part of that VCEEngine DAA-C01 dumps now are free: https://drive.google.com/open?id=18B1_IV3zz7Noo4sQjYiY93I9R9EZPlXh
They work together and analyze the examination content to compile most probable DAA-C01 real dumps in three formats. These Snowflake Certification Exams questions will surely appear in the next Snowflake DAA-C01 exam. Memorizing these Snowflake DAA-C01 Valid Dumps will help you easily attempt the DAA-C01 exam within the allocated time. Thousands of aspirants have passed their DAA-C01 exam, and they all got help from our Snowflake DAA-C01 updated exam dumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Perform Predictive Analysis | 5–10% | - Forecasting and predictive modeling - Using Snowflake ML and built-in analytics |
| Topic 2: Prepare and Present Data | 10–15% | - Snowsight dashboards and sharing results - Data visualization and reporting - Align outputs with business requirements |
| Topic 3: Perform Simple Data Transformations for Analysis | 15–20% | - Views, materialized views, CTEs - Data cleansing, standardization, type conversion - Handling NULLs and structuring datasets |
| Topic 4: Use Built-in Functions and Create UDFs | 10–15% | - Scalar, aggregate, table, system functions - User-Defined Functions (UDFs) |
| Topic 5: Prepare and Load Data | 15–20% | - Data ingestion methods: COPY INTO, stages, Snowpipe - File formats: CSV, JSON, Parquet, Avro - External tables and data validation |
| Topic 6: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Complex joins, subqueries, window functions - Semi-structured data processing - Query optimization and troubleshooting |
| Topic 7: Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis - Anomaly detection and root cause analysis |
>> New Snowflake DAA-C01 Braindumps Questions <<
You can find yourself sitting in your dream office and enjoying the new opportunity. So, don't wait, get the Snowflake DAA-C01 certification by preparing through VCEEngine Snowflake DAA-C01 exam questions that will help you crack the Snowflake DAA-C01 Exam. VCEEngine will provide you with all the Snowflake DAA-C01 exam dumps, practice exams, and other necessary documentation that will help you understand the Snowflake DAA-C01 exam questions and pass the Snowflake DAA-C01 exam.
NEW QUESTION # 49
What are the PRIMARY reasons for using integrity constraints on Snowflake tables? (Select TWO).
Answer: B,C
Explanation:
Understanding how Snowflake handles integrity constraints is vital, as it differs significantly from traditional transactional databases like PostgreSQL or SQL Server. In Snowflake, most constraints are not enforced by the system, with one major exception.
* Enforcement vs. Documentation: Snowflake does not enforce PRIMARY KEY, FOREIGN KEY, or UNIQUE constraints during data loading or updates. If you define a primary key, Snowflake will still allow duplicate values to be inserted. The primary reason for including these is for documentation and metadata (Option C), allowing data analysts and BI tools to understand the intended relationships and schema design.
* The NOT NULL Exception: The only integrity constraint that Snowflake actively enforces is NOT NULL (Option B). If a column is defined as NOT NULL, any attempt to insert or update a record with a null value in that column will result in an error.
Evaluating the Options:
* Options A and D are incorrect because Snowflake does not actually enforce these constraints; it merely stores them as metadata.
* Option E is incorrect because while keys can be used for clustering, defining them as constraints is not a prerequisite for specifying them as clustering keys.
* Options B and C are the 100% correct reasons. They represent the practical application (enforcing data quality for nulls) and the architectural application (providing context for the data model).
NEW QUESTION # 50
A Data Analyst runs this query: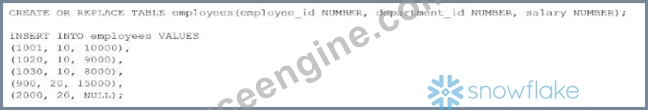
The Analyst men runs this query:
What will be the output?
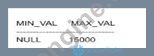
Answer: B
Explanation:
Understanding how Snowflake aggregate functions like MIN() and MAX() handle numerical data and NULL values is fundamental for accurate Data Analysis. In this scenario, we have a table with five records distributed across two departments.
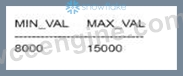
The MIN() function returns the smallest non-null value in the specified column across all rows in the group (or the entire table, if no GROUP BY is present). Looking at the salary column in the employees table, the values are: 10000, 9000, 8000, 15000, and NULL. The NULL value is ignored by the calculation. Among the remaining numerical values, 8000 is the smallest. Therefore, MIN_VAL will be 8000.
The MAX() function operates similarly, returning the largest non-null value from the set. Comparing the same list of numerical values-10000, 9000, 8000, and 15000-the largest value is clearly 15000. Consequently, MAX_VAL will be 15000.
Evaluating the Options based on the exhibit (image_8ca0df.png):
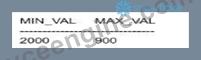
* Option A incorrectly identifies the minimum and maximum based on the employee_id column (where
2000 is max and 900 is min), rather than the requested salary column.
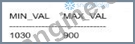
* Option B is incorrect as it seems to mix values from different columns or specific rows.
* Option C is incorrect because it mistakenly suggests that MIN() returns NULL if a NULL value is present in the column. In Snowflake, standard aggregate functions (except for specialized ones like ARRAY_AGG or certain window functions with specific clauses) skip NULL values entirely.
* Option D is the 100% correct output. It displays MIN_VAL as 8000 and MAX_VAL as 15000, which accurately reflects the mathematical minimum and maximum of the non-null entries in the salary column.
This behavior is consistent across all relational databases adhering to ANSI SQL standards, which Snowflake follows for these core aggregate operations.
NEW QUESTION # 51
You are responsible for a Snowflake data pipeline that loads data from various external sources into a data warehouse. You have implemented Snowpipe for continuous data ingestion from AWS S3. One of your data sources is known to occasionally produce corrupted data files. You need to design a resilient pipeline that can handle these corrupted files without halting the entire data loading process and allows for the identification and quarantine of these files for further investigation. Assume you have a table called 'RAW DATA' and you are using a file format 'MY CSV FORMAT. Select TWO actions which best address this situation:

Answer: B,E
Explanation:
Option B directly addresses the requirement for a resilient pipeline by utilizing 'ERROR INTEGRATION' to log errors and quarantine corrupt files. Setting ON_ERROR to CONTINUE avoids pipeline interruption, and creating a task to query the error stage and move files to a quarantine bucket achieves the desired outcome. Option C would be the 2nd best option because it provides for pre-processing and validation, which avoids loading the corrupted records into the RAW_DATA table in the first place. Option A only skips the file and doesn't log the errors or quarantine the file. Option D creates a stream on the RAW DATA table, but we would like to avoid writing erroneous records to the RAW DATA table in the first place. 'VALIDATE only checks the existing data, so it would not solve any problems in Data Load.
NEW QUESTION # 52
How does Snowflake's support for materialized views contribute to query optimization and data analysis?
Answer: A
Explanation:
Materialized views in Snowflake enhance query performance by pre-computing and storing query results, optimizing data analysis by providing faster access to aggregated data.
NEW QUESTION # 53
A ride-sharing company wants to analyze the density of ride requests in different city areas. They have a table 'RIDES' with a 'LOCATION' (GEOGRAPHY) column representing the pickup location of each ride. They want to divide the city into a grid of hexagonal cells and count the number of rides originating in each cell. Which sequence of steps would achieve this, assuming the 'city_boundary' is defined and accessible as a GEOGRAPHY object?
Answer: A
Explanation:
'ST HEXGRID is the correct function for generating a hexagonal grid. is used to check if a hexagonal cell contains a ride's location. Aggregating the ride counts for each cell provides the density information.
NEW QUESTION # 54
......
The web-based Snowflake DAA-C01 practice test software can be used through browsers like Firefox, Safari, and Google Chrome. The customers don't need to download or install any excessive plugins or software in order to use the web-based Snowflake DAA-C01 Practice Exam format. The web-based DAA-C01 practice test software format is supported by different operating systems like Mac, iOS, Linux, Windows, and Android.
DAA-C01 Authentic Exam Questions: https://www.vceengine.com/DAA-C01-vce-test-engine.html
2026 Latest VCEEngine DAA-C01 PDF Dumps and DAA-C01 Exam Engine Free Share: https://drive.google.com/open?id=18B1_IV3zz7Noo4sQjYiY93I9R9EZPlXh