Amazon MLA-C01 Test Free, MLA-C01 Braindumps Downloads
BONUS!!! Download part of ITExamDownload MLA-C01 dumps for free: https://drive.google.com/open?id=1IN1lK-ssdXXT0s1G2oCxuHD1Oi0NIluG
Combined with your specific situation and the characteristics of our MLA-C01 exam questions, our professional services will recommend the most suitable version of MLA-C01 study materials for you. We introduce a free trial version of the MLA-C01 learning guide because we want users to see our sincerity. MLA-C01 exam prep sincerely hopes that you can achieve your goals and realize your dreams.
| Topic | Details |
|---|
| Topic 1 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
| Topic 2 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| Topic 3 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| Topic 4 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
>> Amazon MLA-C01 Test Free <<
Free PDF 2026 Amazon Trustable MLA-C01: AWS Certified Machine Learning Engineer - Associate Test Free
In order to make sure your whole experience of buying our MLA-C01 study materials more comfortable, our company will provide all people with 24 hours online service. The experts and professors from our company designed the online service system for all customers. If you decide to buy the MLA-C01 Study Materials from our company, we can make sure that you will have the opportunity to enjoy the best online service provided by our excellent online workers.
Amazon AWS Certified Machine Learning Engineer - Associate Sample Questions (Q13-Q18):
NEW QUESTION # 13
A company's ML engineer is creating a classification model. The ML engineer explores the dataset and notices a column named day_of_week. The column contains the following values: Monday, Tuesday, Wednesday, Thursday, Friday, Saturday, and Sunday.
Which technique should the ML engineer use to convert this column's data to binary values?
- A. One-hot encoding
- B. Label encoding
- C. Binary encoding
- D. Tokenization
Answer: A
Explanation:
The day_of_week feature is a categorical variable with a small, fixed number of unique values and no inherent ordinal relationship. AWS machine learning best practices strongly recommend one-hot encoding for this type of categorical data when preparing features for classification models.
One-hot encoding converts each unique category into a separate binary feature (0 or 1). For example,
"Monday" becomes a column where Monday = 1 and all other days = 0. This ensures that the ML model does not incorrectly assume a numeric or ordered relationship between categories.
Option B (label encoding) assigns integer values to categories (e.g., Monday = 1, Tuesday = 2). AWS documentation cautions against this approach for nominal data because models may incorrectly infer ordinal meaning, leading to biased or inaccurate predictions.
Option A (binary encoding) is typically used for high-cardinality categorical features to reduce dimensionality. With only seven categories, AWS recommends one-hot encoding for clarity and interpretability.
Option D (tokenization) is used for text processing, such as NLP tasks, and is not appropriate for structured categorical features.
AWS SageMaker feature engineering guidelines emphasize that one-hot encoding is the preferred method for low-cardinality categorical variables in classification models, especially when using algorithms such as logistic regression, neural networks, and tree-based models.
Therefore, Option C is the correct and AWS-aligned choice.
NEW QUESTION # 14
A company stores time-series data about user clicks in an Amazon S3 bucket. The raw data consists of millions of rows of user activity every day. ML engineers access the data to develop their ML models.
The ML engineers need to generate daily reports and analyze click trends over the past 3 days by using Amazon Athena. The company must retain the data for 30 days before archiving the data.
Which solution will provide the HIGHEST performance for data retrieval?
- A. Create AWS Lambda functions to copy the time-series data into separate S3 buckets. Apply S3 Lifecycle policies to archive data that is older than 30 days to S3 Glacier Flexible Retrieval.
- B. Keep all the time-series data without partitioning in the S3 bucket. Manually move data that is older than 30 days to separate S3 buckets.
- C. Organize the time-series data into partitions by date prefix in the S3 bucket. Apply S3 Lifecycle policies to archive partitions that are older than 30 days to S3 Glacier Flexible Retrieval.
- D. Put each day's time-series data into its own S3 bucket. Use S3 Lifecycle policies to archive S3 buckets that hold data that is older than 30 days to S3 Glacier Flexible Retrieval.
Answer: C
Explanation:
Partitioning the time-series data by date prefix in the S3 bucket significantly improves query performance in Amazon Athena by reducing the amount of data that needs to be scanned during queries. This allows the ML engineers to efficiently analyze trends over specific time periods, such as the past 3 days. Applying S3 Lifecycle policies to archive partitions older than 30 days to S3 Glacier FlexibleRetrieval ensures cost- effective data retention and storage management while maintaining high performance for recent data retrieval.
NEW QUESTION # 15
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records per second.
The company needs a scalable AWS solution to identify anomalous data points with the LEAST operational overhead.
Which solution will meet these requirements?
- A. Ingest data into Amazon Kinesis Data Streams. Use the built-in RANDOM_CUT_FOREST function in Amazon Managed Service for Apache Flink to detect anomalies.
- B. Ingest data into Kinesis Data Streams. Deploy a SageMaker AI endpoint and use AWS Lambda to detect anomalies.
- C. Ingest data into Apache Kafka on Amazon EC2 and use SageMaker AI for detection.
- D. Send data to Amazon SQS and use AWS Glue ETL jobs for batch anomaly detection.
Answer: A
Explanation:
For real-time anomaly detection on streaming data, AWS recommends using Amazon Managed Service for Apache Flink, which provides serverless, scalable stream processing with built-in ML functions.
Apache Flink includes a native RANDOM_CUT_FOREST (RCF) function for unsupervised anomaly detection. This eliminates the need to deploy, manage, or scale custom ML endpoints. When combined with Amazon Kinesis Data Streams, the solution can process thousands of records per second with very low latency.
Option B introduces multiple services and custom logic, increasing operational overhead. Option C requires managing EC2 infrastructure and Kafka clusters. Option D is batch-oriented and does not meet real-time requirements.
AWS documentation explicitly highlights Kinesis + Managed Flink + RCF as the lowest-overhead solution for real-time anomaly detection.
Therefore, Option A is the correct and AWS-aligned choice.
NEW QUESTION # 16
A company is setting up a system to manage all of the datasets it stores in Amazon S3. The company would like to automate running transformation jobs on the data and maintaining a catalog of the metadata concerning the datasets. The solution should require the least amount of setup and maintenance.
Which solution will allow the company to achieve its goals?
- A. Create an Amazon EMR cluster with Apache Spark installed. Then, create an Apache Hive metastore and a script to run transformation jobs on a schedule.
- B. Create an Amazon EMR cluster with Apache Hive installed. Then, create a Hive metastore and a script to run transformation jobs on a schedule.
- C. Create an AWS Glue crawler to populate the AWS Glue Data Catalog. Then, author an AWS Glue ETL job, and set up a schedule for data transformation jobs.
- D. Create an Amazon SageMaker Jupyter notebook instance that transforms the data. Then, create an Apache Hive metastore and a script to run transformation jobs on a schedule.
Answer: C
Explanation:
AWS Glue is the correct answer because this option requires the least amount of setup and maintenance since it is serverless, and it does not require management of the infrastructure.
NEW QUESTION # 17
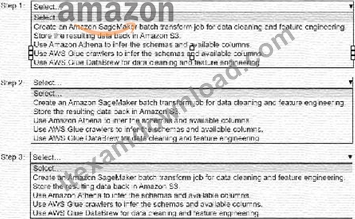
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
Answer:
Explanation:
Explanation:
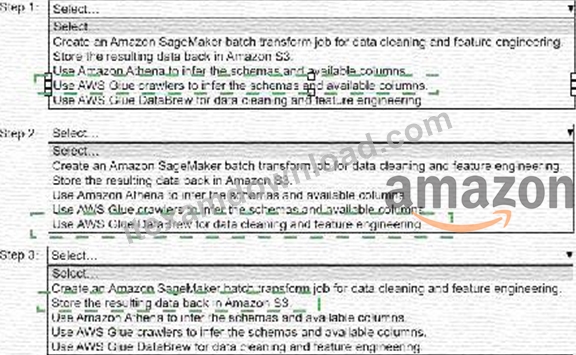
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 18
......
Provided you get the certificate this time with our MLA-C01 training guide, you may have striving and excellent friends and promising colleagues just like you. It is also as obvious magnifications of your major ability of profession, so MLA-C01 Learning Materials may bring underlying influences with positive effects. The promotion or acceptance of our MLA-C01 exam questions will be easy. So it is quite rewarding investment.
MLA-C01 Braindumps Downloads: https://www.itexamdownload.com/MLA-C01-valid-questions.html
- MLA-C01 Exam Bootcamp - MLA-C01 VCE Dumps - MLA-C01 Exam Simulation 🥳 The page for free download of ▶ MLA-C01 ◀ on ⮆ www.troytecdumps.com ⮄ will open immediately 🤿MLA-C01 Vce Exam
- Pass Guaranteed Quiz 2026 Amazon MLA-C01: AWS Certified Machine Learning Engineer - Associate – Efficient Test Free 👒 Search for ▷ MLA-C01 ◁ and easily obtain a free download on ▷ www.pdfvce.com ◁ 🕓MLA-C01 Latest Test Vce
- MLA-C01 Vce Exam 🦳 MLA-C01 Examcollection Vce 👏 MLA-C01 Reliable Exam Registration 🏟 Download ➥ MLA-C01 🡄 for free by simply searching on ➥ www.vce4dumps.com 🡄 🐔Exam MLA-C01 Labs
- Authoritative MLA-C01 Test Free bring you Practical MLA-C01 Braindumps Downloads for Amazon AWS Certified Machine Learning Engineer - Associate 🅰 Search for ▶ MLA-C01 ◀ and easily obtain a free download on ▛ www.pdfvce.com ▟ 🎳Exam MLA-C01 Material
- Trustworthy MLA-C01 Exam Torrent 🔆 MLA-C01 New Braindumps Pdf 🦕 Exam MLA-C01 Material 🏆 Easily obtain free download of ⏩ MLA-C01 ⏪ by searching on [ www.torrentvce.com ] 🥊MLA-C01 Testking
- Reliable MLA-C01 Exam Review ⚪ MLA-C01 Latest Test Vce 🏕 MLA-C01 Certification Sample Questions 🐐 Download ▷ MLA-C01 ◁ for free by simply searching on ▷ www.pdfvce.com ◁ 🟪MLA-C01 Valid Braindumps Ebook
- Exam MLA-C01 Material 🐠 MLA-C01 Examcollection Vce 👋 MLA-C01 Relevant Questions 🐧 Simply search for ▶ MLA-C01 ◀ for free download on ⇛ www.verifieddumps.com ⇚ 🎍Exam MLA-C01 Labs
- MLA-C01 Latest Test Simulator 🦙 MLA-C01 Reliable Exam Pattern 🧶 MLA-C01 Latest Test Simulator 📗 Search for ➠ MLA-C01 🠰 on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🕜Trustworthy MLA-C01 Exam Torrent
- Authoritative MLA-C01 Test Free bring you Practical MLA-C01 Braindumps Downloads for Amazon AWS Certified Machine Learning Engineer - Associate 🤏 Copy URL ➠ www.dumpsquestion.com 🠰 open and search for ⮆ MLA-C01 ⮄ to download for free ☮MLA-C01 Valid Exam Sims
- MLA-C01 Latest Exam Online 💖 MLA-C01 Latest Test Simulator 🧀 MLA-C01 Certification Exam Dumps ☃ Download ➡ MLA-C01 ️⬅️ for free by simply searching on ( www.pdfvce.com ) 🤱Reliable MLA-C01 Exam Review
- Exam MLA-C01 Material 🕟 MLA-C01 Examcollection Vce 🔲 MLA-C01 Examcollection Vce ⛪ Search for 《 MLA-C01 》 and easily obtain a free download on { www.pdfdumps.com } 💸MLA-C01 Examcollection Vce
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, telegra.ph, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, schoolido.lu, Disposable vapes
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by ITExamDownload: https://drive.google.com/open?id=1IN1lK-ssdXXT0s1G2oCxuHD1Oi0NIluG