Databricks Databricks-Certified-Data-Engineer-Professional Certification Book Torrent | Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet

TestBraindump is a website which is able to speed up your passing the Databricks certification Databricks-Certified-Data-Engineer-Professional exams. Our Databricks certification Databricks-Certified-Data-Engineer-Professional exam question bank is produced by TestBraindump's experts's continuously research of outline and previous exam. When you are still struggling to prepare for passing the Databricks certification Databricks-Certified-Data-Engineer-Professional Exams, please choose TestBraindump's latest Databricks certification Databricks-Certified-Data-Engineer-Professional exam question bank, and it will brings you a lot of help.
| Section | Objectives |
|---|
| Topic 1: Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
| Topic 2: Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
- Data governance concepts (Unity Catalog basics)
|
| Topic 3: Data Modeling and Transformation | - Dimensional modeling concepts
- Spark SQL transformations
- Performance optimization techniques
|
| Topic 4: Delta Lake and Data Management | - Time travel and versioning
- Delta Lake transactions and ACID properties
- Schema evolution and enforcement
|
| Topic 5: Data Ingestion and Processing | - ETL pipeline design patterns
- Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
|
>> Databricks Databricks-Certified-Data-Engineer-Professional Certification Book Torrent <<
Free PDF Quiz Databricks - Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam –Reliable Certification Book Torrent
If you are looking to advance in the fast-paced and technological world, TestBraindump is here to help you achieve this aim. TestBraindump provides you with the excellent Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice exam, which will make your dream come true of passing the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam on the first attempt.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q124-Q129):
NEW QUESTION # 124
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
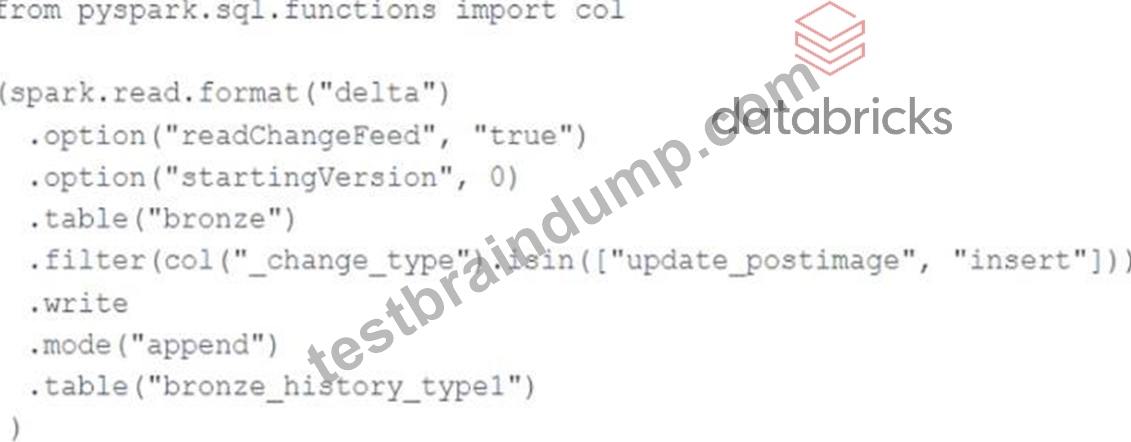
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- B. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- C. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- D. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- E. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
Answer: C
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 125
A data engineer is implementing Unity Catalog governance for a multi-team environment. Data scientists need interactive clusters for basic data exploration tasks, while automated ETL jobs require dedicated processing. How should the data engineer configure cluster isolation policies to enforce least privilege and ensure Unity Catalog compliance?
- A. Allow all users to create any cluster type and rely on manual configuration to enable Unity Catalog access modes.
- B. Configure all clusters with NO ISOLATION_SHARED access mode since Unity Catalog works with any cluster configuration.
- C. Create compute policies with STANDARD access mode for interactive workloads and DEDICATED access mode for automated jobs.
- D. Use only DEDICATED access mode for both interactive workloads and automated jobs to maximize security isolation.
Answer: C
Explanation:
Unity Catalog enforces governance and data isolation through cluster access modes and compute policies. According to Databricks documentation, "Interactive clusters that multiple users share should use Standard access mode, while automated jobs and production pipelines should use Dedicated access mode for stricter isolation." Standard access mode allows multiple users to share the same compute resources but still respects Unity Catalog permissions. Dedicated access mode isolates the job run's execution environment, ensuring that data access is limited to the job's identity. Configuring these modes within compute policies enforces least privilege and ensures all compute complies with Unity Catalog security standards. Options A and C are incorrect because using only Dedicated clusters reduces resource efficiency, while "No isolation" clusters are not Unity Catalog compliant.
NEW QUESTION # 126
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
- A. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to compute the daily aggregated distance and fuel efficiency per truck_id reporting. Create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
- B. Define a materialized view to ingest and store the raw telemetry data, and create a streaming table to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
- C. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to incrementally compute the latest location, speed, and fuel_level per truck_id for real-time monitoring. Create a materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
- D. Define a streaming table to ingest and store the raw telemetry data, and create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
Answer: C
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 127
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
- A. sha1(email)
- B. mask(email, '?')
- C. sha2(email, 0)
- D. hash(email)
Answer: D
Explanation:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
NEW QUESTION # 128
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- B. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- C. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
- D. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
- E. Tables created with SHALLOW CLONE are automatically deleted after their default retention threshold of 7 days.
Answer: C
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
NEW QUESTION # 129
......
Our Databricks-Certified-Data-Engineer-Professional study materials are the accumulation of professional knowledge worthy practicing and remembering. There are so many specialists who join together and contribute to the success of our Databricks-Certified-Data-Engineer-Professional guide quiz just for your needs. As well as responsible and patient staff who has being trained strictly before get down to business and interact with customers on our Databricks-Certified-Data-Engineer-Professional Exam Questions. You can contact with our service, and they will give you the most professional guide.
Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet: https://www.testbraindump.com/Databricks-Certified-Data-Engineer-Professional-exam-prep.html
- Realistic Databricks Databricks-Certified-Data-Engineer-Professional Certification Book Torrent 🔸 Search for ( Databricks-Certified-Data-Engineer-Professional ) and download it for free on ➠ www.dumpsquestion.com 🠰 website 😥Databricks-Certified-Data-Engineer-Professional Latest Test Vce
- Valid Databricks-Certified-Data-Engineer-Professional Test Review 🦆 Dumps Databricks-Certified-Data-Engineer-Professional Guide 🧰 Databricks-Certified-Data-Engineer-Professional Latest Test Vce 😫 Search for { Databricks-Certified-Data-Engineer-Professional } and obtain a free download on 【 www.pdfvce.com 】 😈Databricks-Certified-Data-Engineer-Professional Trustworthy Practice
- Free PDF 2026 High-quality Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Certification Book Torrent 🌶 Download ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free by simply searching on ➥ www.prepawayexam.com 🡄 🦄Databricks-Certified-Data-Engineer-Professional Test Collection Pdf
- Hot Databricks Databricks-Certified-Data-Engineer-Professional Certification Book Torrent Are Leading Materials - Fast Download Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet 💭 Search on { www.pdfvce.com } for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to obtain exam materials for free download 🧷Databricks-Certified-Data-Engineer-Professional Trustworthy Practice
- Databricks-Certified-Data-Engineer-Professional Test Collection Pdf 🧊 Databricks-Certified-Data-Engineer-Professional Trustworthy Practice 📄 Databricks-Certified-Data-Engineer-Professional Reliable Test Blueprint 🏋 Open ✔ www.easy4engine.com ️✔️ enter ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download 🚍Databricks-Certified-Data-Engineer-Professional Latest Test Vce
- Databricks-Certified-Data-Engineer-Professional Reliable Test Labs 🔗 Databricks-Certified-Data-Engineer-Professional Free Vce Dumps 🐞 Databricks-Certified-Data-Engineer-Professional Latest Test Vce ℹ Search on ( www.pdfvce.com ) for 【 Databricks-Certified-Data-Engineer-Professional 】 to obtain exam materials for free download 🔵Exam Dumps Databricks-Certified-Data-Engineer-Professional Free
- Pass Guaranteed Databricks - Efficient Databricks-Certified-Data-Engineer-Professional Certification Book Torrent 🕥 Easily obtain free download of ▶ Databricks-Certified-Data-Engineer-Professional ◀ by searching on ☀ www.vceengine.com ️☀️ 🆕New Databricks-Certified-Data-Engineer-Professional Test Prep
- Hot Databricks Databricks-Certified-Data-Engineer-Professional Certification Book Torrent Are Leading Materials - Fast Download Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet 🚇 Open website ▷ www.pdfvce.com ◁ and search for ( Databricks-Certified-Data-Engineer-Professional ) for free download 😹Databricks-Certified-Data-Engineer-Professional Practice Exam
- Valid Databricks-Certified-Data-Engineer-Professional Test Review 🍼 Valid Databricks-Certified-Data-Engineer-Professional Test Review 📸 Databricks-Certified-Data-Engineer-Professional Practice Exam 🧆 Open ☀ www.vce4dumps.com ️☀️ enter [ Databricks-Certified-Data-Engineer-Professional ] and obtain a free download 🧭Databricks-Certified-Data-Engineer-Professional Positive Feedback
- Databricks-Certified-Data-Engineer-Professional Practice Exam ❔ Databricks-Certified-Data-Engineer-Professional Positive Feedback 😚 Databricks-Certified-Data-Engineer-Professional Free Vce Dumps 😦 Open [ www.pdfvce.com ] and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download exam materials for free 📇Databricks-Certified-Data-Engineer-Professional Free Vce Dumps
- Exam Dumps Databricks-Certified-Data-Engineer-Professional Free 🎁 Valid Databricks-Certified-Data-Engineer-Professional Test Review 🪂 Databricks-Certified-Data-Engineer-Professional Reliable Test Labs ◀ Copy URL 「 www.practicevce.com 」 open and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to download for free 🥵New Databricks-Certified-Data-Engineer-Professional Test Prep
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes