P.S. Free & New AB-100 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1B9Ho9HgPcSgbii2VNQLuIAvvt1kIXd1W
Do you want to pass AB-100 exam certification at your first attempt to attend AB-100 test? With SurePassExams, we will meet all of your needs, and make you pass AB-100 certification exam at one time in a limited time. Because SurePassExams have AB-100 Exam Certification training materials, which are summarized by experienced IT experts with many years' practice, and is a combination of AB-100 exam dumps and answers, you can't regret to choose SurePassExams.
| Section | Weight | Objectives |
|---|---|---|
| Plan AI-powered business solutions | 25% | - AI strategy and requirements analysis
|
| Deploy AI-powered business solutions | 45% | - Security, governance, and ALM
|
| Design AI-powered business solutions | 30% | - Agent and solution design
|
>> AB-100 Latest Exam Duration <<
Our Microsoft AB-100 training materials are compiled by professional experts. All the necessary points have been mentioned in our Agentic AI Business Solutions Architect AB-100 practice engine particularly. About some tough questions or important points, they left notes under them. Besides, our experts will concern about changes happened in Agentic AI Business Solutions Architect AB-100 study prep all the time.
NEW QUESTION # 55
A company has a Microsoft Copilot Studio agent that provides answers based on a knowledge base for customer support.
Users report that, occasionally, the agent provides inaccurate answers.
You need to use metrics from the Analytics tab in Copilot Studio to identify the cause of the inaccuracies.
Which two options should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answers are B. session information and session outcomes and E. quality of generated answers .
This scenario is focused on a knowledge base-driven Copilot Studio agent where users report that the agent sometimes gives inaccurate answers . The question asks which Analytics tab metrics should be used to identify the cause of those inaccuracies.
That means you need metrics that help you examine:
* how the answer was generated
* what happened in the conversation when the bad answer occurred
Why E. quality of generated answers is correct
This is the most direct metric for this scenario.
Because the agent is answering from a knowledge base , the problem is tied to the quality of the generated response itself. The quality of generated answers metric helps assess whether the generated responses are relevant, useful, and accurate enough for the user's request.
From an AI business solutions perspective, this metric is essential because it helps diagnose problems such as:
* weak grounding from the knowledge source
* irrelevant retrieval
* poor answer formulation
* hallucination-like behavior
* mismatch between user question and available source content
If the issue is inaccurate answers, the first place to investigate is the quality signal tied to generated answers.
Why B. session information and session outcomes is correct
To find the cause of inaccuracies, you also need to inspect the broader conversational context. Session information and session outcomes help you see:
* what the user asked
* how the agent responded
* whether the conversation was resolved
* whether the user abandoned, escalated, or retried
* where the conversation broke down
This is important because an inaccurate answer may not come only from poor generation quality. It may also come from:
* the way the user phrased the request
* lack of sufficient grounding context
* repeated failed attempts in a session
* escalation after an unhelpful answer
* patterns in unsuccessful conversations
In other words, quality of generated answers tells you about answer quality, while session information and outcomes help you understand the operational context in which those inaccuracies appear.
Together, these two give the strongest diagnostic view.
Why the other options are incorrect
A). survey results
Survey results can tell you whether users were happy or unhappy, but they do not directly help identify the cause of inaccurate knowledge-based responses. They are more of a feedback signal than a root-cause metric.
C). topic usage and topics with low resolution
This is more relevant for agents built around explicit topics and topic flows. The scenario specifically describes an agent that provides answers based on a knowledge base , so generated-answer analytics are more appropriate than topic-resolution analysis.
D). engagement, resolution, and escalation rates
These are useful high-level operational KPIs, but they are not the best metrics for diagnosing why answers are inaccurate. They show outcome trends, not the direct cause of answer-quality issues.
NEW QUESTION # 56
You are designing a testing solution for a Microsoft Copilot Studio agent that integrates with Microsoft Dynamics 365 Customer Service and Dynamics 365 Sales.
You need to design end-to-end scenarios to test the agent ' s ability to perform the following actions:
Coordinate tasks and data interactions across both Dynamics 365 apps.
Interpret user input and provide contextually relevant outputs.
Which test scenario and metric should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.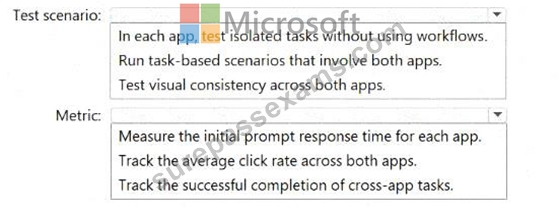
Answer:
Explanation: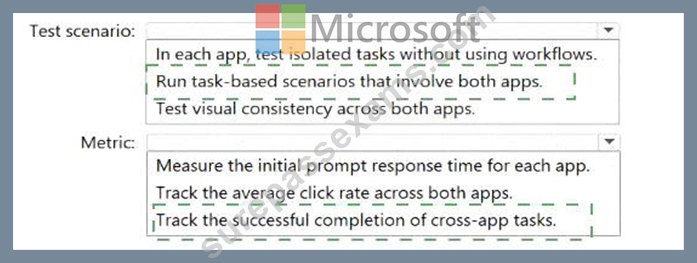
Explanation:
Test scenario # Run task-based scenarios that involve both apps; Metric # Track the successful completion of cross-app tasks Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is D:
Test scenario # Run task-based scenarios that involve both apps
Metric # Track the successful completion of cross-app tasks
Why this test scenario is correct
The question explicitly asks for an end-to-end testing design for a Copilot Studio agent that integrates with both:
Dynamics 365 Customer Service
Dynamics 365 Sales
The required capabilities are:
coordinating tasks and data interactions across both apps
interpreting user input and returning contextually relevant outputs
That means the testing approach cannot be isolated to one app at a time. It must validate the agent's behavior across the full multi-application business workflow.
That is why the correct test scenario is:
Run task-based scenarios that involve both apps
This kind of test validates whether the agent can successfully move through realistic business processes such as:
reading customer context from one app
updating or retrieving related sales information in the other
maintaining context through the workflow
responding appropriately based on user intent across systems
From an agentic AI business solutions perspective, this is the right design because true enterprise agent validation must focus on workflow execution, not just component-level checks.
Why this metric is correct
The best metric is:
Track the successful completion of cross-app tasks
This is the most direct way to measure whether the agent is actually achieving the intended business outcome across both Dynamics 365 applications.
Why this matters:
The requirement is about coordination across apps
The test is end-to-end
The goal is not just speed or UI consistency
The agent must complete business tasks successfully across systems
A cross-app completion metric shows whether the agent can:
understand the user's request
maintain context
retrieve or update the right information
finish the workflow correctly across app boundaries
This is much more meaningful than measuring clicks or simple response time.
Why the other options are incorrect
A). In each app, test isolated tasks without using workflows / Measure initial prompt response time This fails the end-to-end requirement. Isolated tasks do not validate cross-app orchestration, and response time does not prove successful workflow execution.
B). Run task-based scenarios that involve both apps / Track average click rate across both apps The scenario part is good, but average click rate is not the right success metric for Copilot task orchestration.
Clicks do not reliably measure whether the business process was completed correctly.
C). Test visual consistency across both apps / Track successful completion of cross-app tasks The metric is good, but the test scenario is wrong. Visual consistency is a UI concern, not an end-to-end functional validation of cross-app agent behavior.
Expert reasoning
For exam questions like this:
If the requirement says end-to-end across multiple apps, choose task-based scenarios involving both apps If the goal is business workflow success, choose a metric tied to task completion, not visual design, click rate, or raw response speed
NEW QUESTION # 57
A company uses a fine-tuned Microsoft Foundry model that requires frequent updates as new customer feedback becomes available.
You need to design an application lifecycle management (ALM) process that meets the following requirements:
* Data changes must be tracked and versioned.
* The model must be retrained consistently by using approved training data.
Which two actions should you include in the design?
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics Designing an ALM process for fine #tuned Microsoft Foundry models requires two critical capabilities:
* Version-controlled training data
* A consistent, governed pipeline for retraining
Let's break down the reasoning using modern Agentic AI lifecycle , data governance , and model retraining best practices .
E). Store the training data in Azure Blob Storage that has version control enabled - # Correct This directly satisfies the requirement:
"Data changes must be tracked and versioned."
Azure Blob Storage with versioning provides:
* Automatic version history for every training dataset
* Immutable snapshots for audit and rollback
* Governance controls for approved data
* Integration with CI/CD pipelines for model retraining
In an agentic AI lifecycle, data versioning is mandatory because:
* Training data evolves frequently
* Retraining must be reproducible
* Regulatory audits require traceability
* Model drift must be monitored
Blob Storage with versioning is the Microsoft#recommended approach for enterprise AI ALM.
D). Upload the training data to Microsoft Foundry data files - # Correct Foundry fine #tuning jobs require training data to be stored in Foundry data files .
This ensures:
* The fine #tuning job always uses the approved dataset
* The model retraining pipeline is consistent
* The data is validated and formatted correctly
* The training job references a stable, governed data source
This aligns with the requirement:
"The model must be retrained consistently by using approved training data." In agentic AI systems, the training pipeline must be deterministic.
Uploading the data to Foundry data files ensures that the fine#tuning job always uses the correct dataset version.
# Why the other options are NOT correct
A). Associate the storage location to the fine-tuning job - Not sufficient This does not provide:
* Data versioning
* Governance
* Tracking of changes
It simply points the job to a location, not a controlled ALM process.
B). Create a content filter - Not related to ALM or training data
Content filters are for safety , not:
* Versioning
* Data governance
* Retraining consistency
They do not help with the ALM requirements.
C). Store the training data in Azure Files - Not appropriate
Azure Files does not provide:
* Built#in versioning
* Immutable snapshots
* ALM integration for ML pipelines
Blob Storage is the correct choice for AI training data.
Final Answer: D, E
* D. Upload the training data to Microsoft Foundry data files
* E. Store the training data in Azure Blob Storage that has version control enabled These two actions together create a governed, versioned, repeatable ALM pipeline for fine #tuned Foundry models
NEW QUESTION # 58
A company uses Azure OpenAI models that use grounding data from Microsoft Fabric for agents. The models are fine-tuned by using proprietary datasets.
You need to design a governance solution that meets the following requirements:
Restricts access to the grounding data to only assigned roles
Restricts model fine-tuning to only the AI engineering team
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.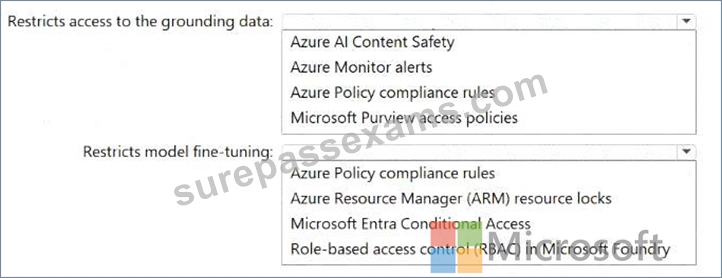
Answer:
Explanation: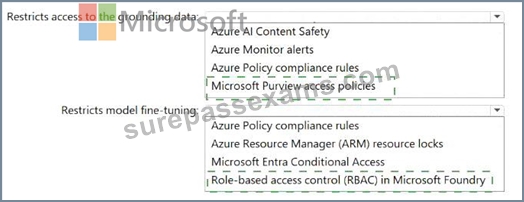
Explanation:
Restricts access to grounding data # Microsoft Purview access policies; Restricts model fine-tuning # Role- based access control (RBAC) in Microsoft Foundry Why Microsoft Purview access policies is correct The grounding data is stored in Microsoft Fabric, and the requirement is to restrict access to that data to only assigned roles.
That is a data governance and access control requirement. Microsoft Purview access policies are the best fit because they are designed to govern and control access to data across enterprise data estates. In this case, they help ensure that only authorized roles can access the grounding data used by the agents.
From an AI business solutions perspective, grounding data is often one of the most sensitive parts of the solution because it can contain:
proprietary business knowledge
internal documents
regulated operational information
contextual data used to shape model outputs
Purview helps enforce governed access to that data layer rather than relying only on general infrastructure controls.
Why RBAC in Microsoft Foundry is correct
The second requirement is to ensure that only the AI engineering team can perform model fine-tuning.
That is an action-level platform permission requirement. The best control for that is role-based access control (RBAC) in Microsoft Foundry.
RBAC allows the organization to assign permissions based on job function, so only authorized users or groups can:
create or modify fine-tuning jobs
manage model assets
update training configurations
control deployment-related AI resources
This is the right governance pattern because fine-tuning changes model behavior and can introduce:
security risk
compliance risk
quality drift
misuse of proprietary datasets
Restricting that capability to the AI engineering team through RBAC creates a clear separation of duties.
Why the other options are incorrect
Azure AI Content Safety
This is used to detect and filter harmful content. It does not control access to Fabric grounding data.
Azure Monitor alerts
Alerts help observe activity, but they do not enforce role-based access to data.
Azure Policy compliance rules
Azure Policy is useful for enforcing resource configuration standards, but it is not the best answer for role- based access to Fabric grounding data or for limiting fine-tuning actions to a specific team.
Azure Resource Manager (ARM) resource locks
Resource locks help prevent deletion or modification of Azure resources, but they do not provide the right permission model for controlling who can perform model fine-tuning operations.
Microsoft Entra Conditional Access
Conditional Access is mainly about sign-in and access conditions, such as device, location, or risk context. It is not the best direct control for restricting fine-tuning permissions inside Foundry.
Expert reasoning
Use this exam shortcut:
Need to control access to enterprise data # think Purview access policies Need to restrict who can perform AI platform actions like fine-tuning # think RBAC in the AI platform So the correct mapping is:
Restricts access to the grounding data: Microsoft Purview access policies Restricts model fine-tuning: Role-based access control (RBAC) in Microsoft Foundry
NEW QUESTION # 59
A company deploys a Microsoft Copilot Studio agent that integrates with a Microsoft Power Automate desktop flow.
You need to recommend a testing solution that meets the following requirements:
Test cases must validate the most recent changes to the agent before the agent is released.
The flow must be validated as part of the agent ' s orchestration.
What should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.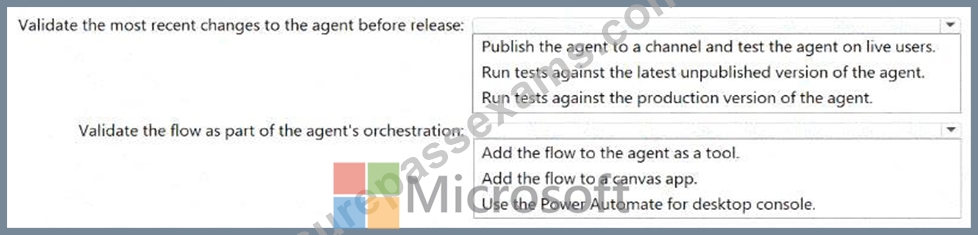
Answer:
Explanation: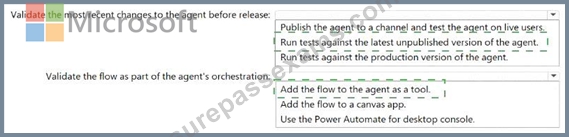
Explanation:
Validate most recent changes # Run tests against the latest unpublished version of the agent; Validate the flow as part of orchestration # Add the flow to the agent as a tool Why the first selection is correct The requirement says the company must validate the most recent changes to the agent before the agent is released. That means testing must happen on the newest working version that has not yet been published to production.
So the correct recommendation is:
Run tests against the latest unpublished version of the agent
This is the safest and most appropriate pre-release testing pattern because it allows the team to:
verify recent changes before users see them
catch regressions early
validate orchestration logic in a controlled state
reduce production risk
From an AI business solutions perspective, pre-release testing is critical for Copilot agents because even small changes in prompts, tools, orchestration, or data connections can affect:
response quality
workflow behavior
escalation paths
compliance behavior
user trust
Testing unpublished changes ensures that governance and quality assurance happen before release, not after deployment.
Why the second selection is correct
The question also requires that the Power Automate desktop flow be validated as part of the agent ' s orchestration.
That means the flow must participate directly in the agent's runtime action path. The correct way to do that is:
Add the flow to the agent as a tool
When a flow is added as a tool, the agent can invoke it during its orchestration. This allows test cases to validate not only the conversational layer, but also the actual execution of the flow inside the end-to-end agent behavior.
From an agentic AI design perspective, tools are how agents connect reasoning with action. If the flow is meant to be part of orchestration, it must be exposed to the agent in a way that allows the agent to call it during task execution.
That is the correct enterprise pattern for validating integrated behavior.
NEW QUESTION # 60
......
As a matter of fact, long-time study isn’t a necessity, but learning with high quality and high efficient is the key method to assist you to succeed. We provide several sets of AB-100 test torrent with complicated knowledge simplified and with the study content easy to master, thus limiting your precious time but gaining more important knowledge. Our Agentic AI Business Solutions Architect guide torrent is equipped with time-keeping and simulation test functions, it’s of great use to set up a time keeper to help adjust the speed and stay alert to improve efficiency. Our expert team has designed a high efficient training process that you only need 20-30 hours to prepare the exam with our AB-100 Certification Training. With an overall 20-30 hours’ training plan, you can also make a small to-do list to remind yourself of how much time you plan to spend in a day with AB-100 test torrent.
Dumps AB-100 PDF: https://www.surepassexams.com/AB-100-exam-bootcamp.html
P.S. Free 2026 Microsoft AB-100 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1B9Ho9HgPcSgbii2VNQLuIAvvt1kIXd1W