Trusted Databricks-Certified-Data-Engineer-Professional Practice Exam Questions & Leader in Qualification Exams & Valid Databricks-Certified-Data-Engineer-Professional Latest Training

Moreover, it is portable enabling you to prepare for the Databricks Databricks-Certified-Data-Engineer-Professional exam from everywhere and at any time. You will find another convenience to make notes on Databricks Databricks-Certified-Data-Engineer-Professional files combined with the facility to print them out. The Databricks-Certified-Data-Engineer-Professional Dumps PDF format can turn your preparation systematic and hassle-free. It will function smoothly on all smart devices.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Topic 2: Monitoring and Troubleshooting | 16% | - Monitoring
- Troubleshooting
- Performance Optimization
|
| Topic 3: Databricks Lakehouse Platform | 24% | - Delta Lake
- Unity Catalog
- Data Management
- Lakehouse Architecture
|
| Topic 4: Data Modeling and Storage | 20% | - File Formats
- Data Modeling
- Storage Optimization
|
| Topic 5: Data Processing | 28% | - Structured Streaming
- Spark SQL
- ETL Pipelines
- Data Transformation
|
>> Databricks-Certified-Data-Engineer-Professional Practice Exam Questions <<
Databricks Certified Data Engineer Professional Exam valid exam simulator & Databricks Certified Data Engineer Professional Exam exam study torrent & Databricks Certified Data Engineer Professional Exam test training guide
ITExamDownload offers the Databricks-Certified-Data-Engineer-Professional exam questions in a convenient PDF format, allowing you to easily download them on your PC, laptop, Mac, tablet, or smartphone. With this accessibility, you can access the Databricks Databricks-Certified-Data-Engineer-Professional PDF questions anytime and from anywhere. Having all the information about the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) Exam at your fingertips enhances your studying experience, making it easier and more effective, whether you're at home or on the go.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q245-Q250):
NEW QUESTION # 245
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Define a view against the products_per_order table and define the dashboard against this view.
- B. Configure a webhook to execute an incremental read against products_per_order each time the dashboard is refreshed.
- C. Populate the dashboard by configuring a nightly batch job to save the required values as a table overwritten with each update.
- D. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- E. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
Answer: C
NEW QUESTION # 246
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
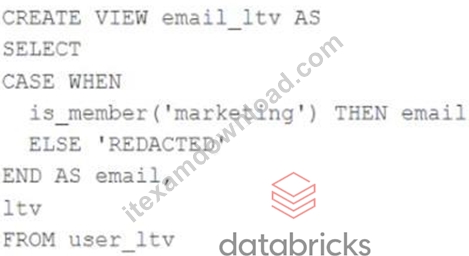
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. The email and ltv columns will be returned with the values in user itv.
- B. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - C. Only the email and itv columns will be returned; the email column will contain all null values.
- D. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- E. The email, age. and ltv columns will be returned with the values in user ltv.
Answer: B
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 247
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table")
\
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
- A. The Delta table lacks optimization that enables dynamic file pruning.
- B. The filter condition involves a data type excluded from data skipping support.
- C. The filter is executed only after the full data scan, preventing data skipping.
- D. The event_date column is outside the table's partitioning and Z-ordering scheme.
Answer: D
Explanation:
Delta Lake's data skipping relies on partitioning and clustering (such as Z-ordering) on the filtered columns. If event_date is neither a partition column nor included in the table's clustering strategy, Spark must scan most files because file-level statistics cannot be effectively used to prune irrelevant data.
NEW QUESTION # 248
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
- A. Configure connections and foreign catalog in Unity Catalog, then grant access to foreign catalogs, schemas, and tables using Unity Catalog permissions.
- B. Mirror the external datasets into Delta Lake using Auto Loader, and govern them using Data Lineage and System Tables.
- C. Use Partner Connect to create linked datasets, and apply table ACLs at the source system to govern access through Databricks.
- D. Create external locations and storage credentials to connect to each database, then register foreign tables in Unity Catalog.
Answer: A
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 249
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context.
Assuming the job is already deployed, they need to trigger its execution while ensuring the target- specific configuration is respected. Which command will trigger the job execution?
- A. databricks bundle run my_project_job -t prod
- B. databricks job run my_project_job --env prod
- C. databricks run my_project_job -t prod
- D. databricks execute my_project_job -e prod
Answer: A
Explanation:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 250
......
Databricks-Certified-Data-Engineer-Professional study material is suitable for all people. Whether you are a student or an office worker, whether you are a veteran or a rookie who has just entered the industry, Databricks-Certified-Data-Engineer-Professional test answers will be your best choice. For office workers, Databricks-Certified-Data-Engineer-Professional test dumps provide you with more flexible study time. You can download learning materials to your mobile phone and study at anytime, anywhere. And as an industry rookie, those unreadable words and expressions in professional books often make you feel mad, but Databricks-Certified-Data-Engineer-Professional Study Materials will help you to solve this problem perfectly.
Databricks-Certified-Data-Engineer-Professional Latest Training: https://www.itexamdownload.com/Databricks-Certified-Data-Engineer-Professional-valid-questions.html
- Get Unparalleled Databricks-Certified-Data-Engineer-Professional Practice Exam Questions and Pass Exam in First Attempt 🔶 Go to website { www.prep4sures.top } open and search for “ Databricks-Certified-Data-Engineer-Professional ” to download for free 🧽Exam Databricks-Certified-Data-Engineer-Professional Quiz
- Test Databricks-Certified-Data-Engineer-Professional Dumps.zip 📫 Clearer Databricks-Certified-Data-Engineer-Professional Explanation 🎢 Test Databricks-Certified-Data-Engineer-Professional Dumps.zip 🔤 Immediately open ⮆ www.pdfvce.com ⮄ and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain a free download 🤶Clearer Databricks-Certified-Data-Engineer-Professional Explanation
- Valid Databricks-Certified-Data-Engineer-Professional Exam Topics 🟪 Databricks-Certified-Data-Engineer-Professional Latest Study Materials ❔ Clearer Databricks-Certified-Data-Engineer-Professional Explanation ⚛ Go to website “ www.prepawaypdf.com ” open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 🚊Exam Databricks-Certified-Data-Engineer-Professional Quiz
- Valid Databricks-Certified-Data-Engineer-Professional Exam Topics 😑 Clearer Databricks-Certified-Data-Engineer-Professional Explanation 🧼 Databricks-Certified-Data-Engineer-Professional Latest Study Materials 🥦 Easily obtain “ Databricks-Certified-Data-Engineer-Professional ” for free download through ⇛ www.pdfvce.com ⇚ 🦗Databricks-Certified-Data-Engineer-Professional Exam Material
- Unparalleled Databricks-Certified-Data-Engineer-Professional Practice Exam Questions | Easy To Study and Pass Exam at first attempt - Trustable Databricks Databricks Certified Data Engineer Professional Exam ⭕ Open website ▶ www.examcollectionpass.com ◀ and search for ( Databricks-Certified-Data-Engineer-Professional ) for free download 📔Exam Databricks-Certified-Data-Engineer-Professional Quiz
- Databricks-Certified-Data-Engineer-Professional Reliable Test Testking ⚫ Databricks-Certified-Data-Engineer-Professional Reliable Test Testking ⬅️ Databricks-Certified-Data-Engineer-Professional Exam Study Solutions 🌽 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ on ✔ www.pdfvce.com ️✔️ immediately to obtain a free download 🥏Valid Databricks-Certified-Data-Engineer-Professional Exam Topics
- Latest Databricks-Certified-Data-Engineer-Professional Exam Dumps 🔼 Study Databricks-Certified-Data-Engineer-Professional Demo 🏖 Latest Real Databricks-Certified-Data-Engineer-Professional Exam 🤲 Copy URL ⮆ www.examcollectionpass.com ⮄ open and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to download for free 🧮Databricks-Certified-Data-Engineer-Professional Reliable Test Testking
- Exam Databricks-Certified-Data-Engineer-Professional Blueprint 🔔 Online Databricks-Certified-Data-Engineer-Professional Lab Simulation 💯 Online Databricks-Certified-Data-Engineer-Professional Lab Simulation 🐒 Open [ www.pdfvce.com ] enter ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ and obtain a free download ⛽Latest Databricks-Certified-Data-Engineer-Professional Exam Dumps
- Get Unparalleled Databricks-Certified-Data-Engineer-Professional Practice Exam Questions and Pass Exam in First Attempt 🦽 Open ▷ www.vceengine.com ◁ and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to download exam materials for free 🍍Premium Databricks-Certified-Data-Engineer-Professional Files
- Trustworthy Databricks-Certified-Data-Engineer-Professional Practice 📂 Latest Real Databricks-Certified-Data-Engineer-Professional Exam 🗻 Test Databricks-Certified-Data-Engineer-Professional Dumps.zip 🍸 ▷ www.pdfvce.com ◁ is best website to obtain [ Databricks-Certified-Data-Engineer-Professional ] for free download 🍳Valid Databricks-Certified-Data-Engineer-Professional Exam Materials
- Databricks-Certified-Data-Engineer-Professional Testking Exam Questions 🥓 Latest Real Databricks-Certified-Data-Engineer-Professional Exam 🥜 Clearer Databricks-Certified-Data-Engineer-Professional Explanation ⤴ Easily obtain { Databricks-Certified-Data-Engineer-Professional } for free download through ➠ www.examcollectionpass.com 🠰 🎒Test Databricks-Certified-Data-Engineer-Professional Dumps.zip
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes