P.S.Tech4ExamがGoogle Driveで共有している無料の2026 Snowflake ARA-C01ダンプ:https://drive.google.com/open?id=1ZWKTzx55M4S72Y1S5jxSXLmGiDB3Du-l
ARA-C01トレーニングテストの購入は複雑ではありません。Snowflake主に4つのステップがあります。最初に、必要に応じて対応するバージョンを選択できます。 次に、正しいメールアドレスを入力する必要があります。 また、その後のリリースでユーザーがメールを変更した場合は、Tech4Examメールを更新する必要があります。 次に、ユーザーは購入するためにARA-C01学習教材の支払いページに入る必要があります。 最後に、支払いから10分以内に、システムは自動的にSnowPro Advanced Architect CertificationのARA-C01学習資料をユーザーのメールアドレスに送信します。 そして、すぐにARA-C01試験に合格して合格することができます。
Snowflake ARA-C01(SnowPro Advanced Architect Certification)は、複雑なSnowflakeクラウドデータプラットフォームを設計および実装することに特化したデータアーキテクトおよびエンジニアのスキルと知識を認定するためのプロフェッショナル認定試験です。この認定試験は、データ管理、データウェアハウジング、および分析ニーズにSnowflakeを使用する企業によって、世界的に認識されています。
Snowflake ARA-C01(Snowpro Advanced Architect認定)認定試験は、Snowflakeプラットフォームの技術的側面における個人の習熟度をテストするために設計された厳格な認定試験です。この認定試験は、高度なスノーフレークソリューションの設計と実装における知識とスキルを検証しようとしている経験豊富な建築家とエンジニアを対象としています。 Snowflake ARA-C01試験では、スノーフレークアーキテクチャ、セキュリティ、パフォーマンスチューニング、データウェアハウジング、データ統合など、幅広いトピックをカバーしています。
IT業種は急激に発展しているこの時代で、IT専門家を称賛しなければならないです。彼らは自身が持っている先端技術で色々な便利を作ってくれます。それに、会社に大量な人的·物的資源を節約させると同時に、案外のうまい効果を取得しました。彼らの給料は言うまでもなく高いです。そのような人になりたいのですか。羨ましいですか。心配することはないです。Tech4ExamのSnowflakeのARA-C01トレーニング資料はあなたに期待するものを与えますから。Tech4Examを選ぶのは、成功を選ぶということになります。
Snowflake ARA-C01試験は、グローバルに認知されているベンダー非依存型の認定資格です。この試験は、Snowflakeアーキテクチャと設計の専門家のスキルと知識を検証するために設計されており、求職市場でより競争力のある人材になることができます。この試験に合格することで、候補者がSnowflakeについて深い理解を持ち、高い効率性、拡張性、セキュリティレベルを備えた複雑なSnowflakeソリューションを設計および実装できることが証明されます。全体的に、Snowflake ARA-C01試験は、Snowflakeアーキテクチャと設計のキャリアを進めたい専門家にとって優れた機会です。
質問 # 200
An Architect is defining transaction rules to adhere to ACID properties to ensure that executed statements are either committed or rolled back. Based on this scenario, what characteristics of transactions should be considered? (Select TWO).
正解:C、E
解説:
Comprehensive and Detailed 150 to 250 words of Explanation From Snowflake SnowPro Architect exam scope and all publicly documented material:
Snowflake supports transactional behavior for DML (and SELECT statements within a transaction context), but DDL statements have special behavior: many DDL operations implicitly commit the current transaction.
Because of that, mixing DDL with DML inside an explicit transaction undermines the "all-or-nothing" rollback expectations and complicates ACID-driven rules. Therefore, a key design characteristic is that explicit transactions should generally be limited to DML and query statements, while recognizing that DDL can implicitly commit and break transactional boundaries (Choice C). Additionally, Snowflake supports explicit transaction control statements using standard SQL forms; BEGIN WORK and COMMIT WORK are valid ways to open and close an explicit transaction (Choice D). From an architecting standpoint, this matters for pipeline design, error handling, and idempotency: multi-step loads/merges should group logically atomic DML steps into an explicit transaction so they commit together or roll back together, but DDL (like CREATE
/ALTER) should be separated or executed with full awareness of implicit commits. This is consistent with SnowPro Architect expectations around reliable data engineering patterns and correctness under failure.
=========
質問 # 201
Please select the correct hierarchy from below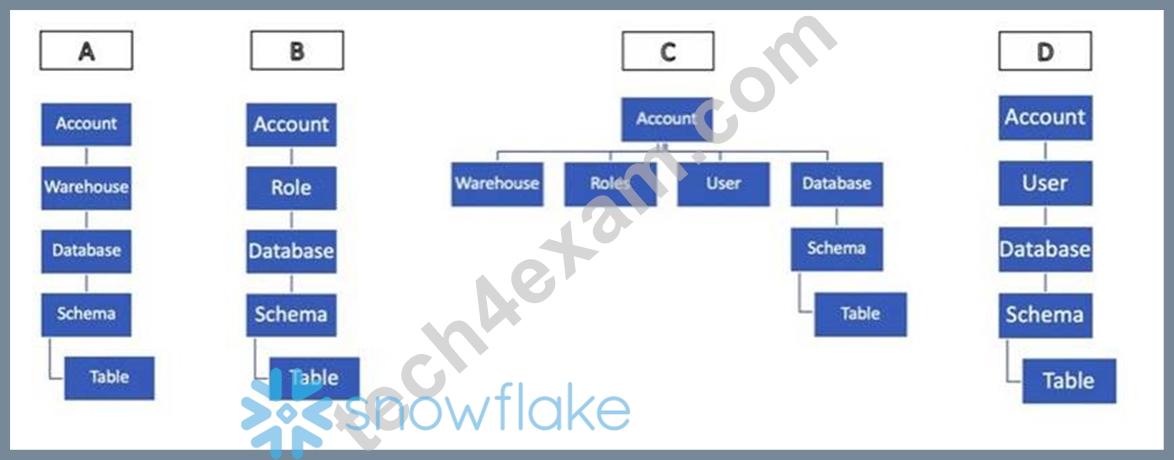
正解:B
質問 # 202
Which columns can be included in an external table schema? (Select THREE).
正解:B、E、F
解説:
An external table schema defines the columns and data types of the data stored in an external stage. All external tables include the following columns by default:
* VALUE: A VARIANT type column that represents a single row in the external file.
* METADATA$FILENAME: A pseudocolumn that identifies the name of each staged data file included in the external table, including its path in the stage.
* METADATA$FILE_ROW_NUMBER: A pseudocolumn that shows the row number for each record in a staged data file.
You can also create additional virtual columns as expressions using the VALUE column and/or the pseudocolumns. However, the following columns are not valid for external tables and cannot be included in the schema:
* METADATASROW_ID: This column is only available for internal tables and shows the unique identifier for each row in the table.
* METADATASISUPDATE: This column is only available for internal tables and shows whether the row was inserted or updated by a merge operation.
* METADATASEXTERNAL TABLE PARTITION: This column is not a valid column name and does not exist in Snowflake.
Introduction to External Tables, CREATE EXTERNAL TABLE
質問 # 203
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
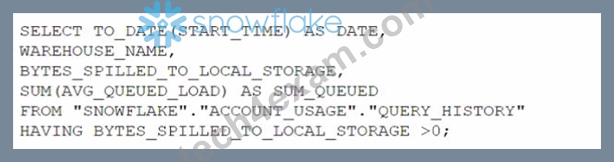
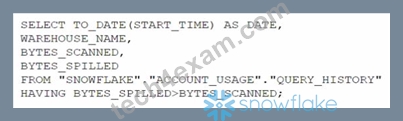
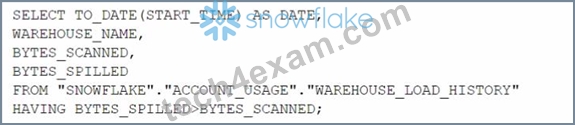
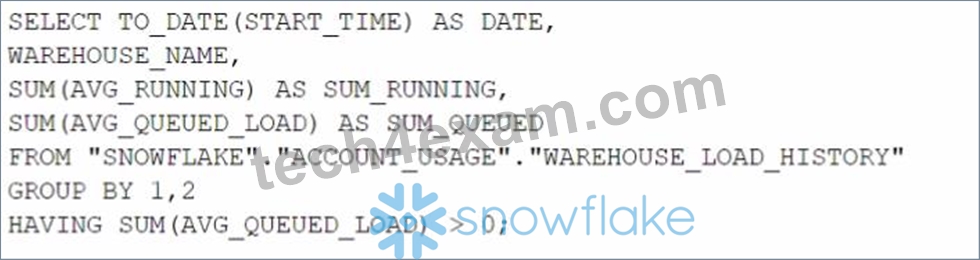
正解:C
解説:
A multi-cluster warehouse is a virtual warehouse that can scale compute resources by adding or removing clusters based on the workload demand. A multi-cluster warehouse can improve the performance of a particular workload by reducing the query queue time and the data spillage to local storage. To identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse, you need to analyze the query history and look for the following indicators:
High average queued load: This metric shows the average number of queries waiting in the queue for each warehouse cluster. A high value indicates that the warehouse is overloaded and cannot handle the concurrency demand.
High bytes spilled to local storage: This metric shows the amount of data that was spilled from memory to local disk during query processing. A high value indicates that the warehouse size is too small and cannot fit the data in memory.
High variation in workload: This metric shows the fluctuation in the number of queries submitted to the warehouse over time. A high variation indicates that the workload is unpredictable and dynamic, and requires a flexible scaling policy.
The query in option C is the best one to identify these indicators, as it selects the date, warehouse name, bytes spilled to local storage, and sum of average queued load from the query history table, and filters the results where bytes spilled to local storage is greater than zero. This query will show the days and warehouses that experienced data spillage and high queue time, and could benefit from a multi-cluster warehouse with auto-scale mode.
The query in option A is not correct, as it only selects the date and warehouse name, and does not include any metrics to measure the performance of the workload. The query in option B is not correct, as it selects the date, warehouse name, and average execution time, which is not a good indicator of the need for a multi-cluster warehouse. The query in option D is not correct, as it selects the date, warehouse name, and average credits used, which is not a good indicator of the need for a multi-cluster warehouse either.
質問 # 204
What will happen if you try to ALTER a COLUMN(which has NULL values) to set it to NOT NULL
正解:B
質問 # 205
......
ARA-C01復習範囲: https://www.tech4exam.com/ARA-C01-pass-shiken.html
2026年Tech4Examの最新ARA-C01 PDFダンプおよびARA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1ZWKTzx55M4S72Y1S5jxSXLmGiDB3Du-l