Databricks Databricks-Certified-Professional-Data-Engineer Actual Dump & Free Databricks-Certified-Professional-Data-Engineer Brain Dumps

If you have a strong desire to get the Databricks certificate, our Databricks-Certified-Professional-Data-Engineer study materials are the best choice for you. At present, the certificate has gained wide popularity. So the official test syllabus of the Databricks-Certified-Professional-Data-Engineer exam begins to become complicated. So you must accept professional guidance. After all, lots of people are striving to compete with many candidates. Powerful competitiveness is crucial to pass the Databricks-Certified-Professional-Data-Engineer Exam. Our company has mastered the core technology of the Databricks-Certified-Professional-Data-Engineer study materials. What’s more, your main purpose is to get the certificate quickly and easily. Our goal is to aid your preparation of the Databricks-Certified-Professional-Data-Engineer exam. Our study materials are an indispensable helper for you anyway. Please pay close attention to our Databricks-Certified-Professional-Data-Engineer study materials.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
|---|
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
|---|
| Real Exam Qty: | 60 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | $200 USD |
|---|
| Exam Duration: | 90 minutes |
|---|
| Exam Format: | Multiple Select, Multiple Choice |
|---|
| Related Certifications: | Databricks Certified Data Analyst Associate
Databricks Certified Associate Developer |
|---|
| Available Languages: | English |
|---|
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
|---|
| Exam Way: | Online proctored exam (Pearson VUE) |
|---|
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
|---|
>> Databricks Databricks-Certified-Professional-Data-Engineer Actual Dump <<
Free Databricks Databricks-Certified-Professional-Data-Engineer Brain Dumps, Valid Test Databricks-Certified-Professional-Data-Engineer Experience
The CertkingdomPDF is one of the top-rated and trusted platforms that are committed to making the entire Databricks Databricks-Certified-Professional-Data-Engineer exam preparation journey fast and successful. To achieve this goal the "CertkingdomPDF" is offering valid, updated, and real Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions. These CertkingdomPDF Databricks-Certified-Professional-Data-Engineer exam questions are checked and verified by qualified subject matter experts.
Databricks Certified Professional Data Engineer certification exam is a hands-on exam that requires candidates to demonstrate their skills in building data pipelines and workflows using Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of a set of performance-based tasks that require candidates to design, implement, and manage data solutions in a Databricks environment. Candidates are given a set of data engineering scenarios and must use Databricks to build solutions that meet the requirements of each scenario.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q37-Q42):
NEW QUESTION # 37
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- B. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
- C. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
- D. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
Answer: D
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. Thesestatistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations
/index.html).
NEW QUESTION # 38
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
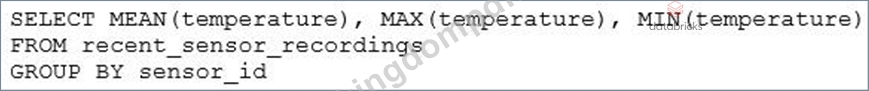
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
- B. The source query failed to update properly for three consecutive minutes and then restarted
- C. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- D. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
- E. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
Answer: E
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified Reference: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
NEW QUESTION # 39
Which of the statements are incorrect when choosing between lakehouse and Datawarehouse?
- A. Lakehouse cannot serve low query latency with high reliability for BI workloads, only suitable for batch workloads.
- B. Lakehouse uses standard data formats like Parquet.
- C. Lakehouse can be accessed through various API's including but not limited to Py-thon/R/SQL
- D. Traditional Data warehouses have storage and compute are coupled.
- E. Lakehouse can have special indexes and caching which are optimized for Machine learning
Answer: A
Explanation:
Explanation
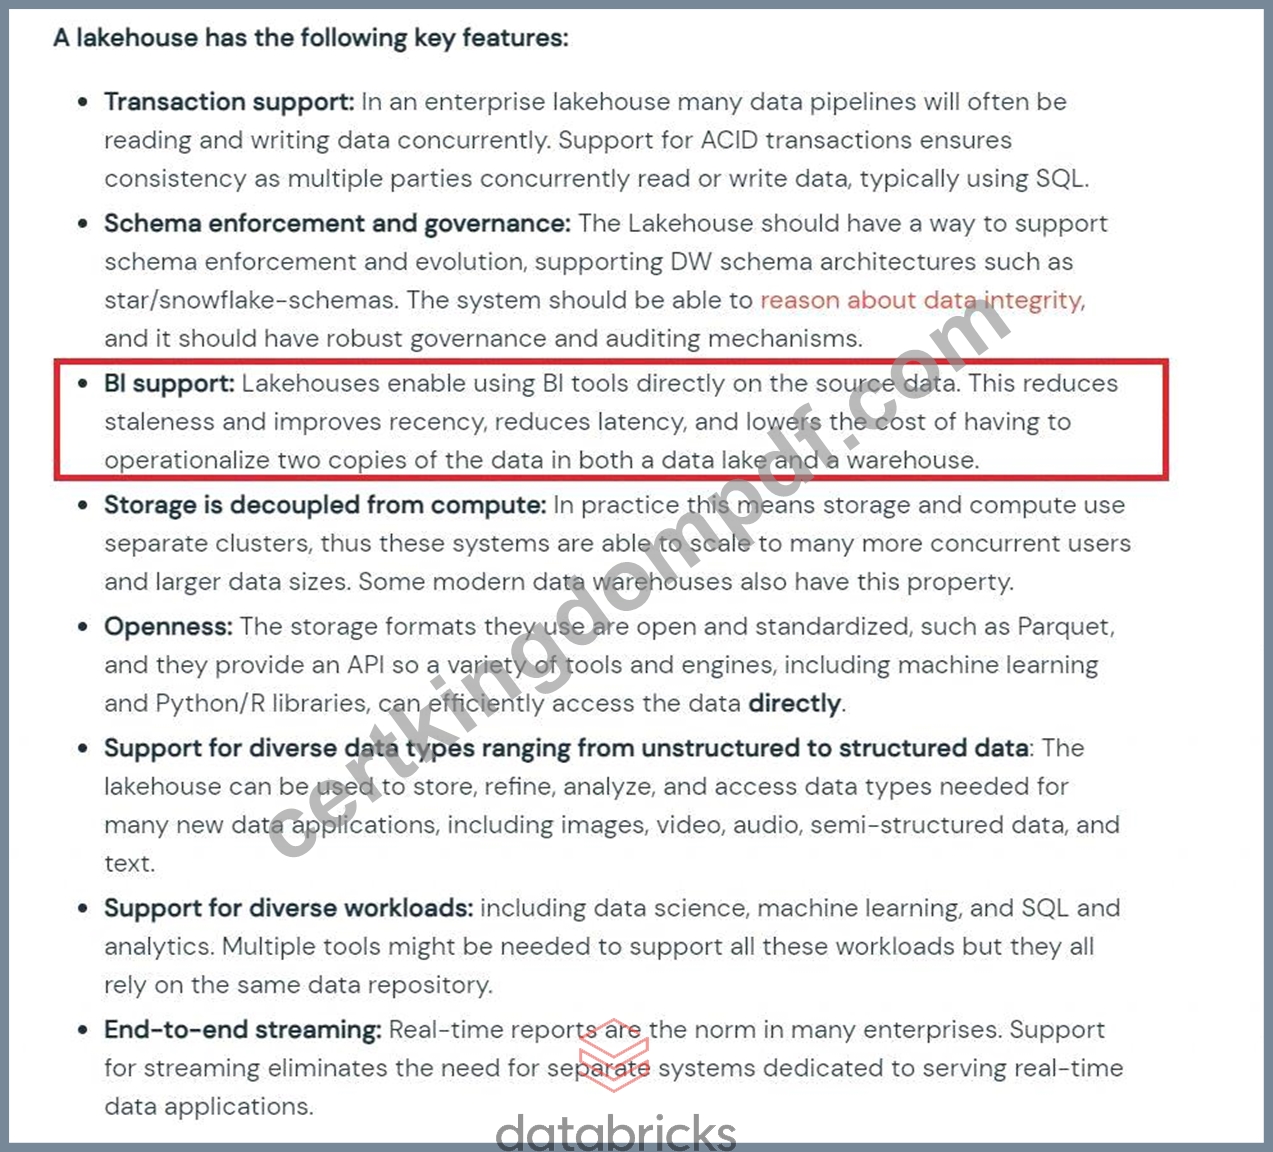
The answer is Lakehouse cannot serve low query latency with high reliability for BI workloads, only suitable for batch workloads.
Lakehouse can replace traditional warehouses by leveraging storage and compute optimizations like caching to serve them with low query latency with high reliability.
Focus on comparisons between Spark Cache vs Delta Cache.
https://docs.databricks.com/delta/optimizations/delta-cache.html
What Is a Lakehouse? - The Databricks Blog
Graphical user interface, text, application Description automatically generated
Bottom of Form
Top of Form
NEW QUESTION # 40
An external object storage container has been mounted to the location/mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
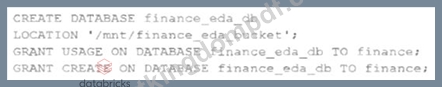
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
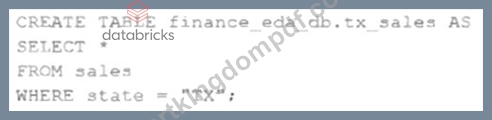
If all users on the finance team are members of thefinancegroup, which statement describes how thetx_sales table will be created?
- A. A managed table will be created in the DBFS root storage container.
- B. An managed table will be created in the storage container mounted to /mnt/finance eda bucket.
- C. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- D. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- E. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
Answer: B
Explanation:
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 41
A Data engineer wants to run unit's tests using common Python testing frameworks on python functions defined across several Databricks notebooks currently used in production.
How can the data engineer run unit tests against function that work with data in production?
- A. Run unit tests against non-production data that closely mirrors production
- B. Define units test and functions within the same notebook
- C. Define and unit test functions using Files in Repos
- D. Define and import unit test functions from a separate Databricks notebook
Answer: A
Explanation:
The best practice for running unit tests on functions that interact with data is to use a dataset that closely mirrors the production data. This approach allows data engineers to validate the logic of their functions without the risk of affecting the actual production data. It's important to have a representative sample of production data to catch edge cases and ensure the functions will work correctly when used in a production environment.
References:
* Databricks Documentation on Testing: Testing and Validation of Data and Notebooks
NEW QUESTION # 42
......
Free Databricks-Certified-Professional-Data-Engineer Brain Dumps: https://www.certkingdompdf.com/Databricks-Certified-Professional-Data-Engineer-latest-certkingdom-dumps.html
- Databricks-Certified-Professional-Data-Engineer Valid Real Exam ➕ Databricks-Certified-Professional-Data-Engineer Latest Test Question 🍐 Demo Databricks-Certified-Professional-Data-Engineer Test 📁 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on ▷ www.practicevce.com ◁ immediately to obtain a free download 🖱New Databricks-Certified-Professional-Data-Engineer Exam Question
- Databricks-Certified-Professional-Data-Engineer Exam Simulations ↪ Databricks-Certified-Professional-Data-Engineer Latest Test Question 🐭 Exam Databricks-Certified-Professional-Data-Engineer Blueprint 🛣 Easily obtain free download of ➤ Databricks-Certified-Professional-Data-Engineer ⮘ by searching on “ www.pdfvce.com ” 🔬Databricks-Certified-Professional-Data-Engineer Detailed Study Plan
- Databricks-Certified-Professional-Data-Engineer Actual Exam 🔂 Exam Databricks-Certified-Professional-Data-Engineer Blueprint 🐅 Databricks-Certified-Professional-Data-Engineer Latest Test Question 🧿 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and download it for free immediately on { www.vce4dumps.com } 🛷Latest Databricks-Certified-Professional-Data-Engineer Test Report
- Latest Databricks-Certified-Professional-Data-Engineer Test Online 👘 Latest Databricks-Certified-Professional-Data-Engineer Test Online 🥚 Latest Databricks-Certified-Professional-Data-Engineer Test Report 🃏 Enter [ www.pdfvce.com ] and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download for free 🔙Databricks-Certified-Professional-Data-Engineer Exam Simulations
- Ace Your Databricks-Certified-Professional-Data-Engineer Exam with Databricks's Exam Questions and Achieve Success 🟫 Enter ⏩ www.practicevce.com ⏪ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to download for free 🌉Databricks-Certified-Professional-Data-Engineer Latest Test Question
- Pass Guaranteed 2026 Databricks-Certified-Professional-Data-Engineer: Professional Databricks Certified Professional Data Engineer Exam Actual Dump 👆 “ www.pdfvce.com ” is best website to obtain ( Databricks-Certified-Professional-Data-Engineer ) for free download 👄Databricks-Certified-Professional-Data-Engineer Valid Real Exam
- Databricks-Certified-Professional-Data-Engineer Latest Dumps Book 🌁 Databricks-Certified-Professional-Data-Engineer Valid Real Exam 🆚 Valid Dumps Databricks-Certified-Professional-Data-Engineer Ebook 🎠 Download “ Databricks-Certified-Professional-Data-Engineer ” for free by simply entering ➥ www.troytecdumps.com 🡄 website ✊Valid Dumps Databricks-Certified-Professional-Data-Engineer Ebook
- 2026 Valid Databricks-Certified-Professional-Data-Engineer Actual Dump | Databricks Certified Professional Data Engineer Exam 100% Free Free Brain Dumps 🦡 Immediately open [ www.pdfvce.com ] and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to obtain a free download 🦱New Databricks-Certified-Professional-Data-Engineer Exam Pattern
- Ace Your Databricks-Certified-Professional-Data-Engineer Exam with Databricks's Exam Questions and Achieve Success 🤠 Copy URL 《 www.pdfdumps.com 》 open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free ☂Demo Databricks-Certified-Professional-Data-Engineer Test
- Databricks-Certified-Professional-Data-Engineer Flexible Testing Engine 🍖 Databricks-Certified-Professional-Data-Engineer Exam Cram Questions 😜 New Databricks-Certified-Professional-Data-Engineer Exam Pattern 🩺 Copy URL 【 www.pdfvce.com 】 open and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 to download for free 🏣Braindump Databricks-Certified-Professional-Data-Engineer Free
- Databricks-Certified-Professional-Data-Engineer Latest Test Question 🥫 New Databricks-Certified-Professional-Data-Engineer Exam Pattern 🎧 Exam Databricks-Certified-Professional-Data-Engineer Blueprint ↙ Search on 【 www.exam4labs.com 】 for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ to obtain exam materials for free download 🤵Databricks-Certified-Professional-Data-Engineer Exam Simulations
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.fundable.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes