BONUS!!! Fast2test Databricks-Certified-Professional-Data-Engineer 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1Fp-XDA65mnQjltbSk6NwtRHLQUqZNxYS
Fast2test의 Databricks Databricks-Certified-Professional-Data-Engineer덤프는 Databricks Databricks-Certified-Professional-Data-Engineer시험문제변경에 따라 주기적으로 업데이트를 진행하여 덤프가 항상 가장 최신버전이도록 업데이트를 진행하고 있습니다.구매한 Databricks Databricks-Certified-Professional-Data-Engineer덤프가 업데이트되면 저희측에서 자동으로 구매시 사용한 메일주소에 업데이트된 최신버전을 발송해드리는데 해당 덤프의 구매시간이 1년미만인 분들은 업데이트서비스를 받을수 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Handling missing or inconsistent data - Standardization and normalization |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
| Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
>> Databricks-Certified-Professional-Data-Engineer시험대비자료 <<
Fast2test에서 출시한 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프는 실제시험문제 커버율이 높아 시험패스율이 가장 높습니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험을 통과하여 자격증을 취득하면 여러방면에서 도움이 됩니다. Fast2test에서 출시한 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 구매하여Databricks인증 Databricks-Certified-Professional-Data-Engineer시험을 완벽하게 준비하지 않으실래요? Fast2test의 실력을 증명해드릴게요.
질문 # 95
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.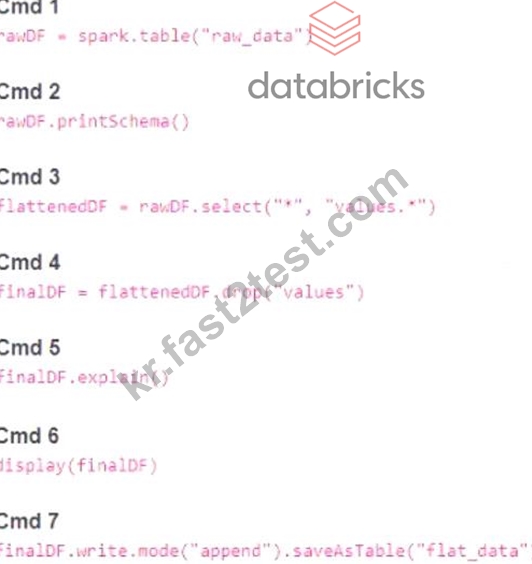
Which command should be removed from the notebook before scheduling it as a job?
정답:D
설명:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
질문 # 96
When defining external tables using formats CSV, JSON, TEXT, BINARY any query on the exter-nal tables caches the data and location for performance reasons, so within a given spark session any new files that may have arrived will not be available after the initial query. How can we address this limitation?
정답:D
설명:
Explanation
The answer is REFRESH TABLE table_name
REFRESH TABLE table_name will force Spark to refresh the availability of external files and any changes.
When spark queries an external table it caches the files associated with it, so that way if the table is queried again it can use the cached files so it does not have to retrieve them again from cloud object storage, but the drawback here is that if new files are available Spark does not know until the Refresh command is ran.
질문 # 97
The operations team is interested in monitoring the recently launched product, team wants to set up an email alert when the number of units sold increases by more than 10,000 units. They want to monitor this every 5 mins.
Fill in the below blanks to finish the steps we need to take
* Create ___ query that calculates total units sold
* Setup ____ with query on trigger condition Units Sold > 10,000
* Setup ____ to run every 5 mins
* Add destination ______
정답:C
설명:
Explanation
The answer is SQL, Alert, Refresh, email address
Here the steps from Databricks documentation,
Create an alert
Follow these steps to create an alert on a single column of a query.
1.Do one of the following:
*Click Create in the sidebar and select Alert.
*Click Alerts in the sidebar and click the + New Alert button.
2.Search for a target query.
Graphical user interface, text, application Description automatically generated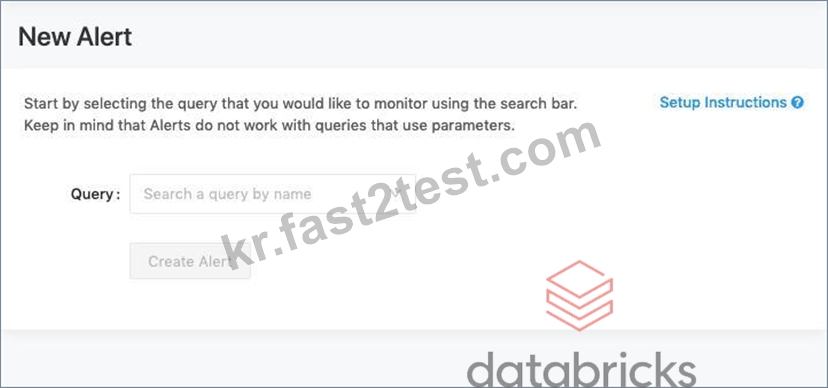
To alert on multiple columns, you need to modify your query. See Alert on multiple col-umns.
3.In the Trigger when field, configure the alert.
*The Value column drop-down controls which field of your query result is evaluated.
*The Condition drop-down controls the logical operation to be applied.
*The Threshold text input is compared against the Value column using the Condition you specify.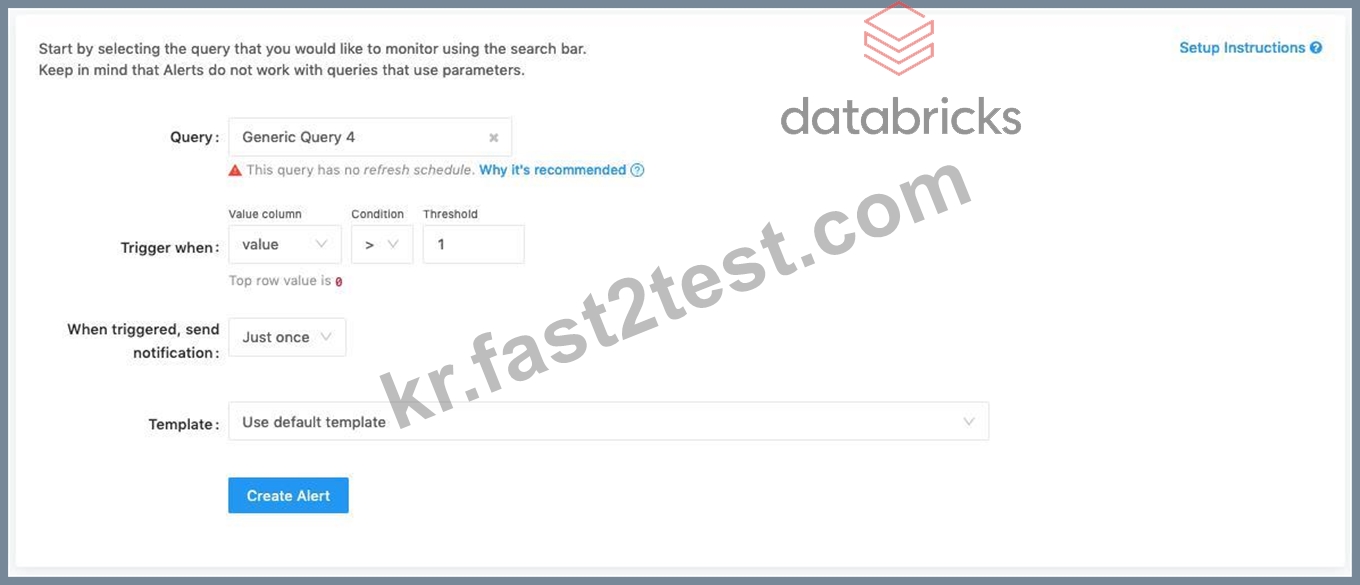
Note
If a target query returns multiple records, Databricks SQL alerts act on the first one. As you change the Value column setting, the current value of that field in the top row is shown beneath it.
4.In the When triggered, send notification field, select how many notifications are sent when your alert is triggered:
*Just once: Send a notification when the alert status changes from OK to TRIGGERED.
*Each time alert is evaluated: Send a notification whenever the alert status is TRIGGERED regardless of its status at the previous evaluation.
*At most every: Send a notification whenever the alert status is TRIGGERED at a spe-cific interval. This choice lets you avoid notification spam for alerts that trigger of-ten.
Regardless of which notification setting you choose, you receive a notification whenever the status goes from OK to TRIGGERED or from TRIGGERED to OK. The schedule settings affect how many notifications you will receive if the status remains TRIGGERED from one execution to the next. For details, see Notification frequency.
5.In the Template drop-down, choose a template:
*Use default template: Alert notification is a message with links to the Alert configuration screen and the Query screen.
*Use custom template: Alert notification includes more specific information about the alert.
a.A box displays, consisting of input fields for subject and body. Any static content is valid, and you can incorporate built-in template variables:
*ALERT_STATUS: The evaluated alert status (string).
*ALERT_CONDITION: The alert condition operator (string).
*ALERT_THRESHOLD: The alert threshold (string or number).
*ALERT_NAME: The alert name (string).
*ALERT_URL: The alert page URL (string).
*QUERY_NAME: The associated query name (string).
*QUERY_URL: The associated query page URL (string).
*QUERY_RESULT_VALUE: The query result value (string or number).
*QUERY_RESULT_ROWS: The query result rows (value array).
*QUERY_RESULT_COLS: The query result columns (string array).
An example subject, for instance, could be: Alert "{{ALERT_NAME}}" changed status to
{{ALERT_STATUS}}.
b.Click the Preview toggle button to preview the rendered result.
Important
The preview is useful for verifying that template variables are rendered cor-rectly. It is not an accurate representation of the eventual notification content, as each alert destination can display notifications differently.
c.Click the Save Changes button.
6.In Refresh, set a refresh schedule. An alert's refresh schedule is independent of the query's refresh schedule.
*If the query is a Run as owner query, the query runs using the query owner's cre-dential on the alert's refresh schedule.
*If the query is a Run as viewer query, the query runs using the alert creator's cre-dential on the alert's refresh schedule.
7.Click Create Alert.
8.Choose an alert destination.
Important
If you skip this step you will not be notified when the alert is triggered.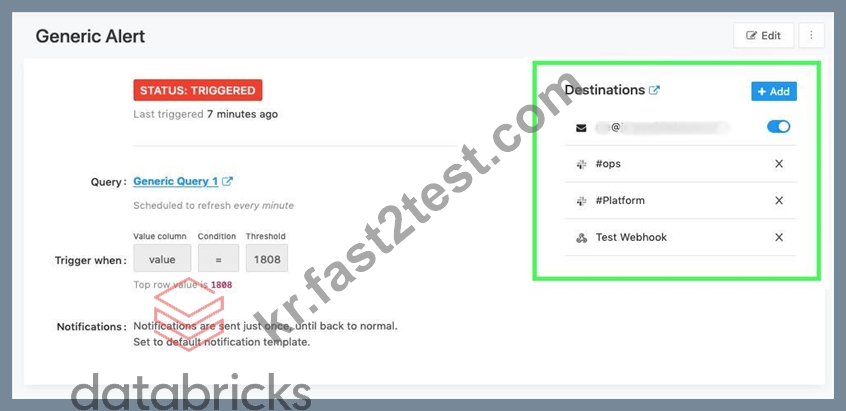
질문 # 98
Which of the following approaches can the data engineer use to obtain a version-controllable con-figuration of the Job's schedule and configuration?
정답:D
질문 # 99
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).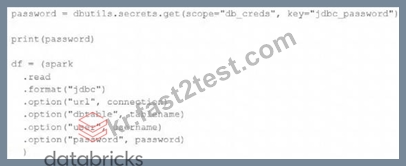
Which statement describes what will happen when the above code is executed?
정답:A
설명:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified Reference: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under "Secrets" section.
질문 # 100
......
여러분은 우선 우리 Fast2test사이트에서 제공하는Databricks인증Databricks-Certified-Professional-Data-Engineer시험덤프의 일부 문제와 답을 체험해보세요. 우리 Fast2test를 선택해주신다면 우리는 최선을 다하여 여러분이 꼭 한번에 시험을 패스할 수 있도록 도와드리겠습니다.만약 여러분이 우리의 인증시험덤프를 보시고 시험이랑 틀려서 패스를 하지 못하였다면 우리는 무조건 덤프비용전부를 환불해드립니다.
Databricks-Certified-Professional-Data-Engineer완벽한 덤프문제: https://kr.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
그리고 Fast2test Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1Fp-XDA65mnQjltbSk6NwtRHLQUqZNxYS