Die Forschungsmaterialien haben gezeigt, dass es schwierig ist, die Microsoft AI-200 Zertifizierungsprüfung zu bestehen. Unser ZertPruefung hat erfahrungsreiche IT-Experten, die durch harte Arbeit die neuesten Schulungsunterlagen zur Microsoft AI-200 Zertifizierungsprüfung bearbeitet haben. Unser ZertPruefung hat die besten Ressourcen, die Ihnen beim Bestehen der Microsoft AI-200 Prüfung helfen. Sie enthalten sowohl Fragen, als auch Antworten. Sie brauchen sich nicht so viel Mühe dafür auszugeben und können trotzdem eine hohe Note in der Prüfung bekommen. Wählen Sie doch die Schulungsunterlagen zur Microsoft AI-200 Zertifizierungsprüfung, die Ihnen sehr helfen können.
| Section | Objectives |
|---|---|
| Connect to and consume Azure services | - Integrate Azure services
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
>> Microsoft AI-200 Prüfungen <<
Das Zertifikat von Microsoft AI-200 kann Ihnen sehr viel helfen. Mit dem Zertifikat können Sie befördert werden. Und Ihr Lebensniveau wird sich sicher verbessern. Das Microsoft AI-200 Zertifikat bedeutet für Sie einen großen Reichtum. Die Microsoft AI-200 (Developing AI Cloud Solutions on Azure) Zertifizierungsprüfung ist ein Test für die IT-Fachleute. Die Prüfungsmaterialien zur Microsoft AI-200 Zertifizierungsprüfung sind die besten und umfassendsten. Nun stellt ZertPruefung Ihnen die besten und optimalen Prüfungsmaterialien zur AI-200 Zertifizierungsprüfung zur Verfügung, die Prüfungsfragen und Antworten enthalten.
121. Frage
You are implementing a Retrieval-Augmented Generation (RAG) system by using the native vector search capabilities of Azure Cosmos DB for NoSQL API.
You have a container named Documents that stores technical articles. Each article includes a property named embedding.
You must ensure that the system can perform efficient similarity searches between user queries and the stored articles.
You need to configure the database resources to support semantic retrieval.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.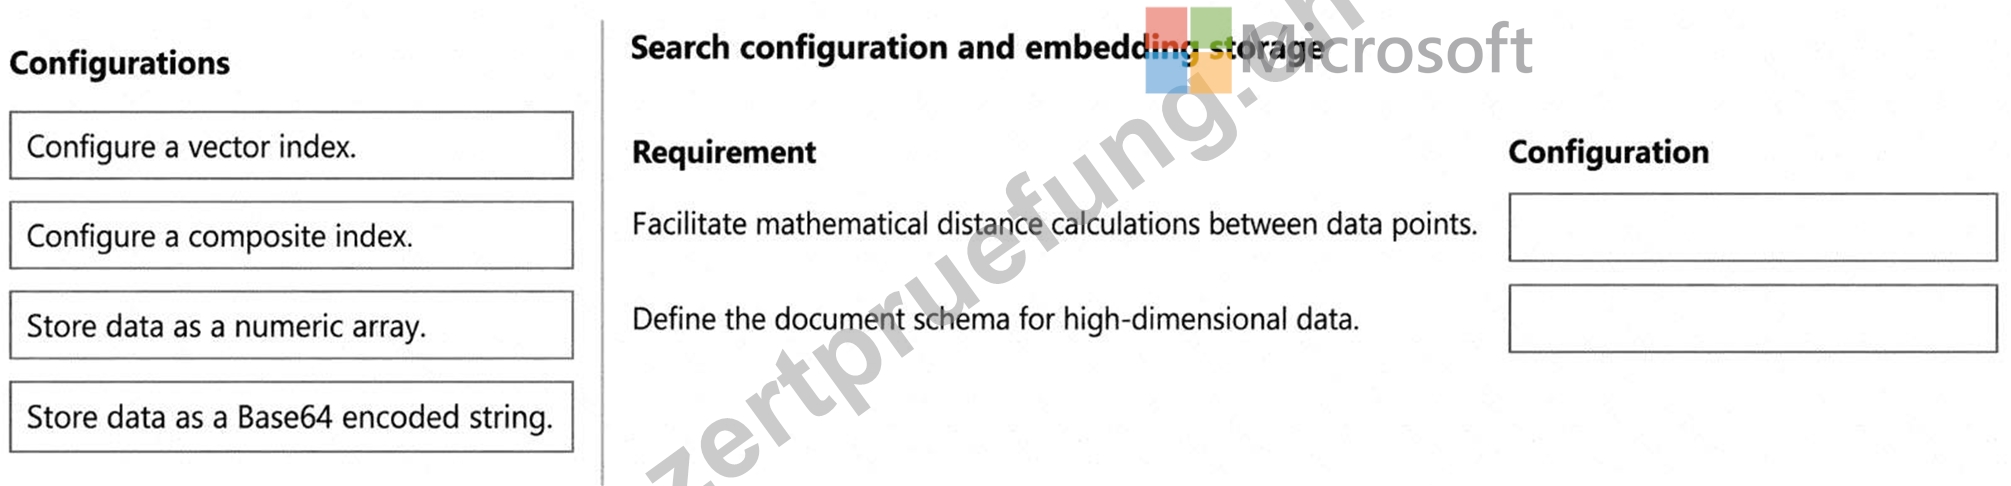
Antwort:
Begründung: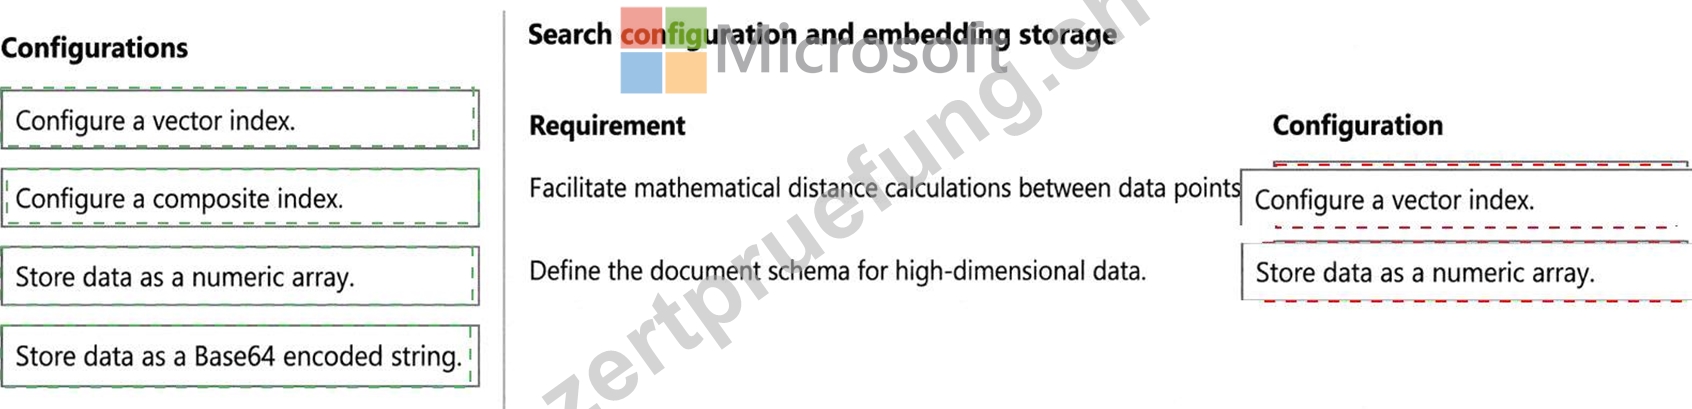
Explanation:
* Facilitate mathematical distance calculations between data points: Configure a vector index.
* Define the document schema for high-dimensional data: Store data as a numeric array.
Azure Cosmos DB for NoSQL supports native vector search by storing embeddings directly in JSON documents and defining a vector embedding policy plus a vector index on the embedding path. Microsoft documents that vector search compares a query vector with stored vectors by calculating similarity or distance through the VectorDistance() system function. A vector index materially improves this process by reducing search latency, increasing throughput, and lowering RU consumption compared with an unindexed vector scan.
The embedding property itself must be stored as an array of numeric values . Microsoft examples show embedding properties such as " contentVector " : [2, -1, 4, ...] and define the associated vector policy with attributes including path, data type, dimensions, and distance function. This representation is required because embeddings are high-dimensional numerical vectors generated by an embedding model.
A composite index optimizes queries involving multiple scalar properties but does not provide vector- distance indexing. A Base64-encoded string cannot be used directly for native vector similarity calculations because Cosmos DB expects the vector field to contain numeric values matching the configured dimensionality.
Study Guide references: Azure Cosmos DB for NoSQL # vector embedding policies; vector indexes; VectorDistance(); numeric embedding arrays; native vector search.
122. Frage
You need to give an Azure OpenAI-based agent the ability to call a company's internal REST API to check order status during a conversation. What should you implement?
Antwort: A
Begründung:
Function calling lets you describe available functions/tools with a JSON schema; the model decides when to invoke them and with what arguments, and your application executes the actual API call and returns results to the model.
123. Frage
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
Antwort: D
124. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store connection strings in the Function app application settings configured in the Azure Portal.
Does the solution meet the goal?
Antwort: B
Begründung:
Correct:
* Use App Configuration with Key Vault references to store environment-specific settings and secrets, accessed from the function app by using a managed identity.
This is an industry-standard best practice architectural pattern.
Using Azure App Configuration combined with Azure Key Vault references completely satisfies your compliance requirements. It centralizes feature flags and non-sensitive configurations, keeps sensitive data safely out of source control, handles multi-environment deployments cleanly, and eliminates credentials via a passwordless Managed Identity.
Incorrect:
* Store connection strings in the Function app application settings configured in the Azure Portal.
* Store production secrets in environment variables set by the Dockerfile.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
125. Frage
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to deploy a batch retraining workload.
How should you complete the scaling configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.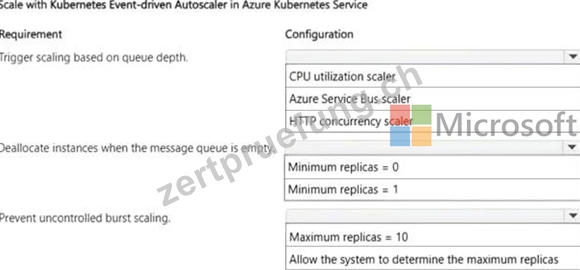
Antwort:
Begründung: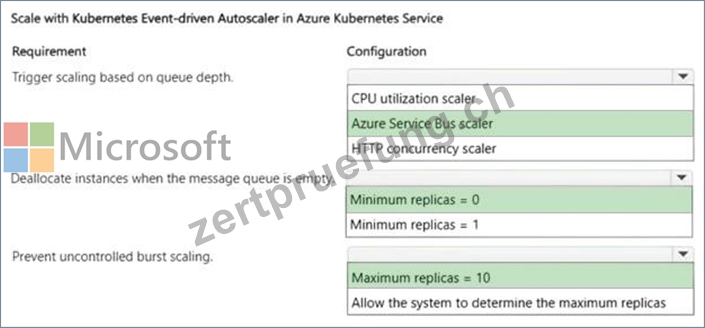
Explanation:
Box 1: Azure Service Bus scaler
An Azure Service Bus scaler needs to be set up to meet this requirement.
Queue-Depth Metrics: To trigger scaling based strictly on queue depth, the orchestration layer (such as Azure Container Apps or AKS using KEDA) requires a scaler that can natively communicate with the message broker and monitor metrics like active message count.
Scale-to-Zero Support: Unlike standard resource scalers, an Azure Service Bus scaler enables event-driven batch workloads to spin up consumers when messages arrive and scale all the way down to zero instances when the queue is completely empty.
Box 2: Minimum replicas = 0.
You need to set Minimum replicas = 0.
Setting the minimum replicas to 0 enables the system to scale down to zero instances when there are no messages left in the queue, completely deallocating resources and eliminating idle compute costs.
Box 3: Maximum replicas = 10
To prevent uncontrolled burst scaling during your batch retraining workloads, you need to set maximum replicas = 10.
Enforcing Upper Bounds: Allowing the system to determine the maximum replica gives the underlying autoscaler (such as KEDA or the Horizontal Pod Autoscaler in Azure Kubernetes Service) the freedom to scale out infinitely or up to large default platform limits. This directly risks uncontrolled burst scaling when a massive batch queue is processed.
Resource and Cost Protection: Hard-coding a ceiling (like maximum replicas = 10) ensures that the batch workload cannot consume more cluster resources than allocated, preventing resource starvation for customer-facing recommendation APIs and keeping operational costs predictable.
Reference:
https://azure.github.io/aca-dotnet-workshop/aca/09-aca-autoscale-keda/
https://kserve.github.io/website/docs/reference/crd-api
126. Frage
......
Überlegen Sie nicht länger. Wenn Sie die Inhalte der Microsoft AI-200 Dumps probieren, klicken Sie bitte ZertPruefung Website. Sie können die Microsoft AI-200 Demo von der Website herunterladen. Vor dem Kauf könnten Sie sich auch mehr über diese Website informieren. Außerdem können Sie auch die volle Rückerstattung für den Durchfall der Microsoft AI-200 Prüfungen zuvor kennen lernen. ZertPruefung ist unbedingt eine Website, die Ihre alle Interesse garantieren und an Ihnen denken wollen.
AI-200 Simulationsfragen: https://www.zertpruefung.ch/AI-200_exam.html