Databricks-Certified-Professional-Data-Engineer Studienmaterialien: Databricks Certified Professional Data Engineer Exam & Databricks-Certified-Professional-Data-Engineer Zertifizierungstraining

P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Fast2test verfügbar: https://drive.google.com/open?id=1rZlMfotlp5w1c9mH83viwPDY3bEv8m5V
Die Ausbildungsmaterialien zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung aus Fast2test verfügen über hohe Genauigkeiten und große Reichweite, sie können nicht nur Ihre Kenntnisse, sondern auch Ihre Operationsfähigkeiten verbessern, so dass Sie zu einem Eliten in der IT-Branche werden und eine gut bezahlte Arbeit bekommen können. Bevor Sie unsere Ausbildungsmaterialien zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung kaufen, können Sie einige kostenlosen Prüfungsfragen und Antworten als Testversion herunterladen.
Die Zertifizierung zum Databricks Certified Professional Data Engineer ist eine stark nachgefragte Zertifizierung in der Daten-Engineering-Industrie. Sie soll die Fähigkeiten und das Wissen von Daten-Ingenieuren testen, die mit Databricks arbeiten, einer cloud-basierten Plattform, die Organisationen bei der Verwaltung großer Datenmengen und der Durchführung fortschrittlicher Analysen unterstützt.
Die Databricks Certified Professional Data Engineer Prüfung ist eine wertvolle Zertifizierung für Datenprofis, die mit der Databricks-Plattform arbeiten. Indem sie ihre Expertise in der Verwendung von Databricks für Daten-Engineering-Aufgaben demonstrieren, können Kandidaten ihre Karriereaussichten verbessern und zum Erfolg ihrer Organisationen beitragen.
>> Databricks-Certified-Professional-Data-Engineer Unterlage <<
Databricks-Certified-Professional-Data-Engineer Testking - Databricks-Certified-Professional-Data-Engineer Fragen&Antworten
Die Prüfungen, die ITer ablegen wollen, sind vielleicht Databricks Zertifizierungsprüfungen. Als die international zertifizierte Prüfung sind Databricks Prüfungen immer mehr populärer. In dieser Prüfung ist Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung die wichtigste Prüfung. Diese Zertifizierung kann Ihre sehr ausgezeichnete Fähigkeit beweisen. Aber diese Prüfung ist sehr schwierig wie die Wichtigkeit der Prüfungen. Aber sorgen Sie sich bitte nicht um den Erfolg, weil Fast2test Ihnen helfen, diese Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu bestehen.
Die Prüfung ist ideal für Daten-Ingenieure, die ihre Expertise im Entwurf, Aufbau und der Wartung von Big-Data-Verarbeitungspipelines mit Databricks demonstrieren möchten. Die Zertifizierungsprüfung ist auf die spezifischen Rollen und Verantwortlichkeiten eines Daten-Ingenieurs zugeschnitten und umfasst eine Reihe von Themen, einschließlich Daten-Erfassung, Daten-Transformationen, Daten-Speicherung und Daten-Analyse. Durch das Bestehen der Prüfung können Kandidaten ihre Kompetenz im Umgang mit Databricks bei der Lösung komplexer Big-Data-Herausforderungen demonstrieren.
Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Prüfungsfragen mit Lösungen (Q24-Q29):
24. Frage
The data engineering team maintains the following code:
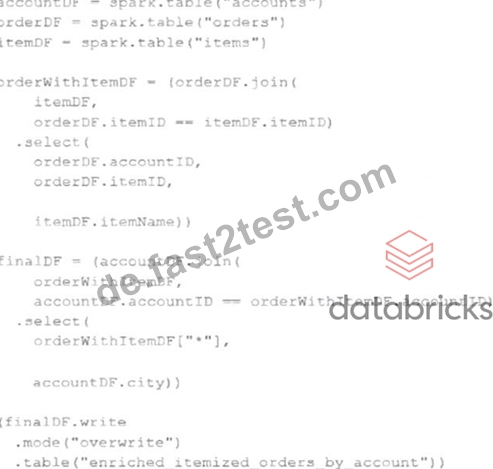
Assuming that this code produces logically correct results and the data in the source tables has been de- duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- B. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- C. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
Antwort: B
Begründung:
The provided PySpark code performs the following operations:
* Reads Data from silver_customer_sales Table:
* The code starts by accessing the silver_customer_sales table using the spark.table method.
* Groups Data by customer_id:
* The .groupBy("customer_id") function groups the data based on the customer_id column.
* Aggregates Data:
* The .agg() function computes several aggregate metrics for each customer_id:
* F.min("sale_date").alias("first_transaction_date"): Determines the earliest sale date for the customer.
* F.max("sale_date").alias("last_transaction_date"): Determines the latest sale date for the customer.
* F.mean("sale_total").alias("average_sales"): Calculates the average sale amount for the customer.
* F.countDistinct("order_id").alias("total_orders"): Counts the number of unique orders placed by the customer.
* F.sum("sale_total").alias("lifetime_value"): Calculates the total sales amount (lifetime value) for the customer.
* Writes Data to gold_customer_lifetime_sales_summary Table:
* The .write.mode("overwrite").table("gold_customer_lifetime_sales_summary") command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
* The mode("overwrite") specifies that the existing data in the
gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: "The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job." References:
* PySpark DataFrame groupBy
* PySpark Basics
25. Frage
A Delta Lake table was created with the below query:
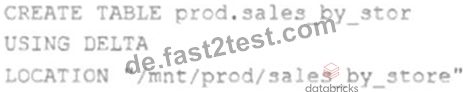
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. The table reference in the metastore is updated and all data files are moved.
- B. The table reference in the metastore is updated and no data is changed.
- C. A new Delta transaction log Is created for the renamed table.
- D. The table name change is recorded in the Delta transaction log.
- E. All related files and metadata are dropped and recreated in a single ACID transaction.
Antwort: B
Begründung:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
26. Frage
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable.
Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- B. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- C. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- D. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
Antwort: B
Begründung:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
27. Frage
Which statement describes Delta Lake optimized writes?
- A. Optimized writes logical partitions instead of directory partitions partition boundaries are only represented in metadata fewer small files are written.
- B. A shuffle occurs prior to writing to try to group data together resulting in fewer files instead of each executor writing multiple files based on directory partitions.
- C. Before a job cluster terminates, OPTIMIZE is executed on all tables modified during the most recent job.
- D. An asynchronous job runs after the write completes to detect if files could be further compacted; yes, an OPTIMIZE job is executed toward a default of 1 GB.
Antwort: B
Begründung:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table. The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
References:
* Databricks documentation on Delta Lake performance tuning: https://docs.databricks.com/delta
/optimizations/auto-optimize.html
28. Frage
Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other's branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution.
How should the data engineers resolve this merge conflict using Databricks Git folders?
- A. Abort the merge, discard all local changes, and try the merge operation again without reviewing the conflicting code.
- B. Use the Git CLI in the cluster's web terminal to force-push the conflicted merge (git push -force), overriding the remote branch with the local version and discarding changes.
- C. Delete the conflicted notebook file via the Databricks workspace UI, commit the deletion, and recreate the notebook from scratch in a new commit to bypass the conflict entirely.
- D. Use the Git folders UI to manually edit the notebook file, selecting the desired lines from both versions and removing the conflict markers, then mark the conflict as resolved.
Antwort: D
Begründung:
In the Databricks Git folders integration, when merge conflicts arise in notebooks, the UI provides a visual diff editor that highlights conflicting code segments. Users can manually choose which changes to keep from each branch, edit directly in the notebook UI, and remove conflict markers.
After resolving, the engineer must mark the conflict as resolved, save, and commit the final version.
This process ensures that both contributors' valid code segments are merged correctly and version history is maintained.
Forcing a push (C) or deleting notebooks (B) introduces data loss or versioning issues. Aborting without review (A) violates collaborative best practices. Therefore, D is the only correct and Databricks-approved way to resolve notebook merge conflicts.
29. Frage
......
Databricks-Certified-Professional-Data-Engineer Testking: https://de.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
- Databricks-Certified-Professional-Data-Engineer Fragenpool 🍀 Databricks-Certified-Professional-Data-Engineer Originale Fragen 🙀 Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen 🦦 Suchen Sie auf ➡ www.deutschpruefung.com ️⬅️ nach ▛ Databricks-Certified-Professional-Data-Engineer ▟ und erhalten Sie den kostenlosen Download mühelos 🐆Databricks-Certified-Professional-Data-Engineer Prüfungs
- Databricks-Certified-Professional-Data-Engineer zu bestehen mit allseitigen Garantien 🟦 Suchen Sie auf ⏩ www.itzert.com ⏪ nach ➤ Databricks-Certified-Professional-Data-Engineer ⮘ und erhalten Sie den kostenlosen Download mühelos 🌽Databricks-Certified-Professional-Data-Engineer Unterlage
- Databricks-Certified-Professional-Data-Engineer Testking 🌶 Databricks-Certified-Professional-Data-Engineer Prüfungsaufgaben ➖ Databricks-Certified-Professional-Data-Engineer Schulungsangebot 🦎 Suchen Sie einfach auf ▷ de.fast2test.com ◁ nach kostenloser Download von ▛ Databricks-Certified-Professional-Data-Engineer ▟ ⚠Databricks-Certified-Professional-Data-Engineer Originale Fragen
- Databricks-Certified-Professional-Data-Engineer Antworten 👔 Databricks-Certified-Professional-Data-Engineer Vorbereitung 🌝 Databricks-Certified-Professional-Data-Engineer Online Prüfung ↖ Sie müssen nur zu 《 www.itzert.com 》 gehen um nach kostenloser Download von 《 Databricks-Certified-Professional-Data-Engineer 》 zu suchen 📆Databricks-Certified-Professional-Data-Engineer Fragenpool
- Neueste Databricks Certified Professional Data Engineer Exam Prüfung pdf - Databricks-Certified-Professional-Data-Engineer Prüfung Torrent 📽 Suchen Sie jetzt auf “ www.zertpruefung.ch ” nach ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ um den kostenlosen Download zu erhalten 🎽Databricks-Certified-Professional-Data-Engineer Originale Fragen
- Databricks-Certified-Professional-Data-Engineer Übungsmaterialien 🖤 Databricks-Certified-Professional-Data-Engineer Prüfungs 🌖 Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen ↪ ▛ www.itzert.com ▟ ist die beste Webseite um den kostenlosen Download von ➽ Databricks-Certified-Professional-Data-Engineer 🢪 zu erhalten 🦱Databricks-Certified-Professional-Data-Engineer Online Prüfung
- Databricks-Certified-Professional-Data-Engineer Übungsmaterialien - Databricks-Certified-Professional-Data-Engineer realer Test - Databricks-Certified-Professional-Data-Engineer Testvorbereitung 🎴 Suchen Sie auf der Webseite ➤ www.pruefungfrage.de ⮘ nach [ Databricks-Certified-Professional-Data-Engineer ] und laden Sie es kostenlos herunter 😝Databricks-Certified-Professional-Data-Engineer Prüfungsmaterialien
- Databricks-Certified-Professional-Data-Engineer Übungsmaterialien 🤱 Databricks-Certified-Professional-Data-Engineer Schulungsangebot 🛰 Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen 📿 Sie müssen nur zu 【 www.itzert.com 】 gehen um nach kostenloser Download von 《 Databricks-Certified-Professional-Data-Engineer 》 zu suchen 🚂Databricks-Certified-Professional-Data-Engineer Fragenpool
- Databricks-Certified-Professional-Data-Engineer Studienmaterialien: Databricks Certified Professional Data Engineer Exam - Databricks-Certified-Professional-Data-Engineer Torrent Prüfung - Databricks-Certified-Professional-Data-Engineer wirkliche Prüfung 🏘 Öffnen Sie die Webseite ➽ www.deutschpruefung.com 🢪 und suchen Sie nach kostenloser Download von ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ 🐂Databricks-Certified-Professional-Data-Engineer Online Prüfung
- Databricks-Certified-Professional-Data-Engineer Prüfungsmaterialien 😓 Databricks-Certified-Professional-Data-Engineer Deutsche Prüfungsfragen 🦆 Databricks-Certified-Professional-Data-Engineer Unterlage 🌸 Öffnen Sie die Webseite ( www.itzert.com ) und suchen Sie nach kostenloser Download von ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ 📗Databricks-Certified-Professional-Data-Engineer Antworten
- Databricks-Certified-Professional-Data-Engineer Deutsche Prüfungsfragen 🍷 Databricks-Certified-Professional-Data-Engineer Examsfragen 📥 Databricks-Certified-Professional-Data-Engineer Unterlage ⬛ Suchen Sie auf ☀ www.itzert.com ️☀️ nach kostenlosem Download von { Databricks-Certified-Professional-Data-Engineer } 🐷Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Fast2test verfügbar: https://drive.google.com/open?id=1rZlMfotlp5w1c9mH83viwPDY3bEv8m5V