DOWNLOAD the newest FreeDumps Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1U4oLuCaNm8D0UD4vN3zHt_vqG1y3fLh9
We provide you the free download and tryout of our Databricks-Generative-AI-Engineer-Associate study tool before your purchase our product and we provide the demo of the product to let the client know our product fully. After you visit the pages of our Databricks-Generative-AI-Engineer-Associate test torrent on the websites, you can know the characteristics and merits of the Databricks-Generative-AI-Engineer-Associate Guide Torrent. In the pages of our product on the website, you can find the details and guarantee and the contact method, the evaluations of the client on our Databricks-Generative-AI-Engineer-Associate test torrent and other information about our Databricks-Generative-AI-Engineer-Associate exam questions. So it is very convenient for you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Assembling and Deploying Apps | 22% | - Use Vector Search - Package and deploy models - Build and deploy RAG pipelines |
| Topic 2: Application Development | 30% | - Implement prompt engineering - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains |
| Topic 3: Design Applications | 14% | - Design and architect applications - Define functional requirements - Select appropriate models |
| Topic 4: Evaluation and Monitoring | 12% | - Evaluate model quality and performance - Monitor deployed applications |
| Topic 5: Data Preparation | 14% | - Prepare data for RAG applications - Manage data quality and chunking |
| Topic 6: Governance | 8% | - Manage permissions and logging - Apply safety filters and guidelines |
>> Databricks-Generative-AI-Engineer-Associate Latest Test Cost <<
Our Databricks-Generative-AI-Engineer-Associate practice materials are your optimum choices which contain essential know-hows for your information. If you really want to get the certificate successfully, only Databricks-Generative-AI-Engineer-Associate practice materials with intrinsic contents can offer help they are preeminent materials can satisfy your both needs of studying or passing with efficiency. You may strand on some issues at sometimes, all confusions will be answered by their bountiful contents. Wrong choices may engender wrong feed-backs, we are sure you will come a long way by our Databricks-Generative-AI-Engineer-Associate practice material.
NEW QUESTION # 91
A Generative AI Engineer developed an LLM application using the provisioned throughput Foundation Model API. Now that the application is ready to be deployed, they realize their volume of requests are not sufficiently high enough to create their own provisioned throughput endpoint. They want to choose a strategy that ensures the best cost-effectiveness for their application.
What strategy should the Generative AI Engineer use?
Answer: C
Explanation:
* Problem Context: The engineer needs a cost-effective deployment strategy for an LLM application with relatively low request volume.
* Explanation of Options:
* Option A: Switching to external models may not provide the required control or integration necessary for specific application needs.
* Option B: Using a pay-per-token model is cost-effective, especially for applications with variable or low request volumes, as it aligns costs directly with usage.
* Option C: Changing to a model with fewer parameters could reduce costs, but might also impact the performance and capabilities of the application.
* Option D: Manually throttling requests is a less efficient and potentially error-prone strategy for managing costs.
OptionBis ideal, offering flexibility and cost control, aligning expenses directly with the application's usage patterns.
NEW QUESTION # 92
A Generative AI Engineer I using the code below to test setting up a vector store: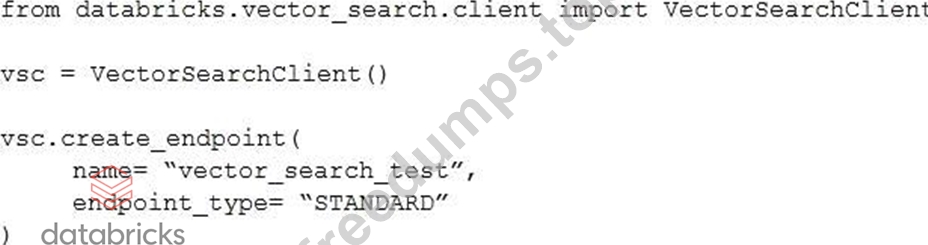
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 93
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: D
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval- Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
* Ingest documents from a source : This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
* Index the documents and save to Vector Search : Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
* User submits queries against an LLM : Users interact with the application by submitting their queries. These queries will be passed to the LLM.
* LLM retrieves relevant documents : The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
* LLM generates a response : Using the retrieved documents, the LLM generates a response that is tailored to the user ' s question.
* Evaluate model : After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
* Deploy it using Model Serving : Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 94
A Generative AI Engineer is developing a patient-facing healthcare-focused chatbot. If the patient's question is not a medical emergency, the chatbot should solicit more information from the patient to pass to the doctor' s office and suggest a few relevant pre-approved medical articles for reading. If the patient's question is urgent, direct the patient to calling their local emergency services.
Given the following user input:
"I have been experiencing severe headaches and dizziness for the past two days." Which response is most appropriate for the chatbot to generate?
Answer: A
Explanation:
* Problem Context: The task is to design responses for a healthcare-focused chatbot that appropriately addresses the urgency of a patient's symptoms.
* Explanation of Options:
* Option A: Suggesting articles might be suitable for less urgent inquiries but is inappropriate for symptoms that could indicate a serious condition.
* Option B: Given the description of severe symptoms like headaches and dizziness, directing the patient to emergency services is prudent. This aligns with medical guidelines that recommend immediate professional attention for such severe symptoms.
* Option C: Offering well-wishes does not address the potential seriousness of the symptoms and lacks appropriate action.
* Option D: While gathering more information is part of a detailed assessment, the immediate need here suggests a more urgent response.
Given the potential severity of the described symptoms,Option Bis the most appropriate, ensuring the chatbot directs patients to seek urgent care when needed, potentially saving lives.
NEW QUESTION # 95
A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.
Which action should they take to elicit the desired behavior from this LLM?
Answer: A
Explanation:
The LLM classifies mushroom species accurately but includes unwanted reasoning text, and the engineer wants only the label. Let's assess how to control output format effectively.
Option A: Use few shot prompting to instruct the model on expected output format Few-shot prompting provides examples (e.g., input: description, output: label). It can work but requires crafting multiple examples, which is effort-intensive and less direct than a clear instruction.
Databricks Reference: "Few-shot prompting guides LLMs via examples, effective for format control but requires careful design" ("Generative AI Cookbook").
Option B: Use zero shot prompting to instruct the model on expected output format Zero-shot prompting relies on a single instruction (e.g., "Return only the label") without examples. It's simpler than few-shot but may not consistently enforce succinctness if the LLM's default behavior is verbose.
Databricks Reference: "Zero-shot prompting can specify output but may lack precision without examples" ("Building LLM Applications with Databricks").
Option C: Use zero shot chain-of-thought prompting to prevent a verbose output format Chain-of-Thought (CoT) encourages step-by-step reasoning, which increases verbosity-opposite to the desired outcome. This contradicts the goal of label-only output.
Databricks Reference: "CoT prompting enhances reasoning but often results in detailed responses" ("Databricks Generative AI Engineer Guide").
Option D: Use a system prompt to instruct the model to be succinct in its answer A system prompt (e.g., "Respond with only the species label, no additional text") sets a global instruction for the LLM's behavior. It's direct, reusable, and effective for controlling output style across queries.
Databricks Reference: "System prompts define LLM behavior consistently, ideal for enforcing concise outputs" ("Generative AI Cookbook," 2023).
Conclusion: Option D is the most effective and straightforward action, using a system prompt to enforce succinct, label-only responses, aligning with Databricks' best practices for output control.
NEW QUESTION # 96
......
As the tech industry continues to evolve and adapt to new technologies, professionals who hold the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certification are better equipped to navigate these changes and stay ahead of the curve, increasing their value to employers and clients. In today's fast-paced and ever-changing Databricks sector, having the Databricks Databricks-Generative-AI-Engineer-Associate Certification has become a necessary requirement for individuals looking to advance their careers and stay competitive in the job market.
Exam Questions Databricks-Generative-AI-Engineer-Associate Vce: https://www.freedumps.top/Databricks-Generative-AI-Engineer-Associate-real-exam.html
BONUS!!! Download part of FreeDumps Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1U4oLuCaNm8D0UD4vN3zHt_vqG1y3fLh9