We are aware that the IT industry is a new industry. It is one of the chain to drive economic development. So its status can not be ignored. IT certification is one of the means of competition in the IT industry. Passed the certification exam you will get to a good rise. But pass the exam is not easy. It is recommended that using training tool to prepare for the exam. If you want to choose this certification training resources, ExamcollectionPass's Databricks Databricks-Certified-Professional-Data-Engineer Exam Training materials will be the best choice. The success rate is 100%, and can ensure you pass the exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Passing Score: | 70% |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Real Exam Qty: | 60-70 |
| Exam Price: | USD 200 |
| Available Languages: | English |
| Exam Format: | Scenario-based questions, Multiple choice, Multiple select |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 120 minutes |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Certified-Professional-Data-Engineer Exam Duration <<
The operation of our Databricks-Certified-Professional-Data-Engineer exam torrent is very flexible and smooth. Once you enter the interface and begin your practice on our windows software. You will easily find there are many useful small buttons to assist your learning. The correct answer of the Databricks-Certified-Professional-Data-Engineer exam torrent is below every question, which helps you check your answers. We have checked all our answers. So you can check the answers breezily. In addition, the small button beside every question can display or hide answers of the Databricks-Certified-Professional-Data-Engineer Test Answers. You can freely choose the two modes. At the same time, there is specific space below every question for you to make notes. So you can quickly record the important points or confusion of the Databricks-Certified-Professional-Data-Engineer exam guides.
Databricks Certified Professional Data Engineer certification is highly valued by organizations that use the Databricks platform for their data processing and analytics needs. By earning this certification, data engineers can demonstrate their expertise and proficiency in using the Databricks platform to design and implement complex data projects. Databricks Certified Professional Data Engineer Exam certification can also help data engineers advance their careers and increase their earning potential, as it is recognized and respected by employers in the data engineering field.
NEW QUESTION # 105
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: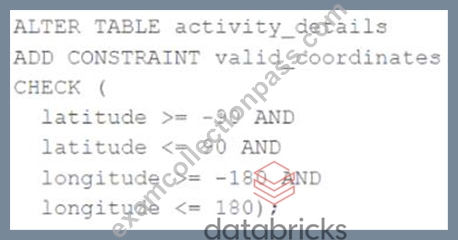
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
Answer: E
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints: https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions: https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 106
You are using k-means clustering to classify heart patients for a hospital. You have chosen Patient Sex,
Height, Weight, Age and Income as measures and have used 3 clusters. When you create a pair-wise plot of
the clusters, you notice that there is significant overlap between the clusters. What should you do?
Answer: B
NEW QUESTION # 107
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 108
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
Answer: C
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
:
Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
NEW QUESTION # 109
A security analytics pipeline must enrich billions of raw connection logs with geolocation data. The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events (# 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges (# 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Question:
Which change will most dramatically accelerate the query while preserving its logic?
Answer: A
Explanation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort- merge joins because:
* Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition , broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
* Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
* Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint , Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute-force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
* It leverages range-join optimization , which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
* This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
Reference: Databricks SQL Performance Tuning Guide - Range Joins and Join Hints (RANGE_JOIN, BROADCAST, MERGE).
NEW QUESTION # 110
......
Valid Databricks-Certified-Professional-Data-Engineer Cram Materials: https://www.examcollectionpass.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html