P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PracticeMaterial: https://drive.google.com/open?id=1JA9naFoay5IdiSdM579XCvO8mSWzj7HU
Owing to our high-quality Professional-Machine-Learning-Engineer real dump sand high passing rate, our company has been developing faster and faster and gain good reputation in the world. Our education experts are adept at designing and researching exam questions and answers of Professional-Machine-Learning-Engineer study materials. What’s more, we can always get latest information resource. Our high passing rate is the leading position in this field. We are the best choice for candidates who are eager to Pass Professional-Machine-Learning-Engineer Exam and acquire the certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Train and deploy models | 20% | - Configure training jobs and environments - Deploy models for online, batch, and streaming prediction - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure |
| Topic 2: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder |
| Topic 3: Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Address data privacy, compliance, and governance |
| Topic 4: Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage |
| Topic 5: Scale prototypes into AI models | 18% | - Select appropriate model architectures and frameworks - Optimize model performance and generalization - Work with foundation models and generative AI techniques - Design and run experiments |
| Topic 6: Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows - Automate retraining and model updates - Implement CI/CD for ML systems |
>> Valid Google Professional-Machine-Learning-Engineer Exam Notes <<
This free Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions demo download facility is available in all three Professional-Machine-Learning-Engineer exam dumps formats. Just choose the best PracticeMaterial Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam demo questions format and download it quickly. If you think that Professional-Machine-Learning-Engineer exam dumps can work for you then take your buying decision.
NEW QUESTION # 95
You work for an advertising company and want to understand the effectiveness of your company's latest advertising campaign. You have streamed 500 MB of campaign data into BigQuery. You want to query the table, and then manipulate the results of that query with a pandas dataframe in an Al Platform notebook. What should you do?
Answer: D
NEW QUESTION # 96
You work for a large social network service provider whose users post articles and discuss news. Millions of comments are posted online each day, and more than 200 human moderators constantly review comments and flag those that are inappropriate. Your team is building an ML model to help human moderators check content on the platform. The model scores each comment and flags suspicious comments to be reviewed by a human.
Which metric(s) should you use to monitor the model's performance?
Answer: D
Explanation:
* Precision measures the fraction of messages flagged by the model that are actually inappropriate, while recall measures the fraction of inappropriate messages that are flagged by the model. These metrics are useful for evaluating how well the model can identify and filter out inappropriate comments.
* Option A is not a good metric because it does not account for the accuracy of the model. The model might flag many messages that are not inappropriate, or miss many messages that are inappropriate.
* Option B is better than option A, but it still does not account for the recall of the model. The model might flag only a few messages that are highly likely to be inappropriate, but miss many other messages that are less obvious but still inappropriate.
* Option C is not a good metric because it does not focus on the messages that are flagged by the model.
The random sample of 0.1% of raw messages might contain very few inappropriate messages, making the precision and recall estimates unreliable.
NEW QUESTION # 97
You have written unit tests for a Kubeflow Pipeline that require custom libraries. You want to automate the execution of unit tests with each new push to your development branch in Cloud Source Repositories. What should you do?
Answer: C
Explanation:
Cloud Build is a service that executes your builds on Google Cloud Platform infrastructure. Cloud Build can import source code from Cloud Source Repositories, Cloud Storage, GitHub, or Bitbucket, execute a build to your specifications, and produce artifacts such as Docker containers or Java archives1 Cloud Build allows you to set up automated triggers that start a build when changes are pushed to a source code repository. You can configure triggers to filter the changes based on the branch, tag, or file path2 To automate the execution of unit tests for a Kubeflow Pipeline that require custom libraries, you can use Cloud Build to set an automated trigger to execute the unit tests when changes are pushed to your development branch in Cloud Source Repositories. You can specify the steps of the build in a YAML or JSON file, such as installing the custom libraries, running the unit tests, and reporting the results. You can also use Cloud Build to build and deploy the Kubeflow Pipeline components if the unit tests pass3 The other options are not recommended or feasible. Writing a script that sequentially performs the push to your development branch and executes the unit tests on Cloud Run is not a good practice, as it does not leverage the benefits of Cloud Build and its integration with Cloud Source Repositories. Setting up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories and using a Pub/Sub trigger for Cloud Run or Cloud Function to execute the unit tests is unnecessarily complex and inefficient, as it adds extra steps and latency to the process. Cloud Run and Cloud Function are also not designed for executing unit tests, as they have limitations on the memory, CPU, and execution time45 References: 1: Cloud Build overview 2: Creating and managing build triggers 3: Building and deploying Kubeflow Pipelines using Cloud Build 4: Cloud Run documentation 5: Cloud Functions documentation
NEW QUESTION # 98
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?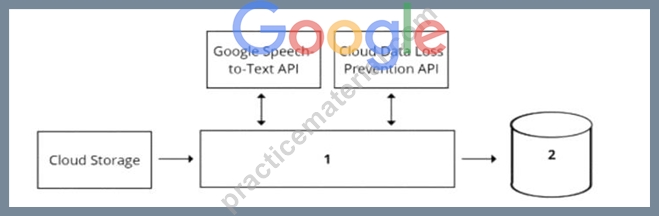
Answer: B
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 99
You are the Director of Data Science at a large company, and your Data Science team has recently begun using the Kubeflow Pipelines SDK to orchestrate their training pipelines. Your team is struggling to integrate their custom Python code into the Kubeflow Pipelines SDK. How should you instruct them to proceed in order to quickly integrate their code with the Kubeflow Pipelines SDK?
Answer: A
Explanation:
The func_to_container_op function in the Kubeflow Pipelines SDK is specifically designed to convert Python functions into containerized components that can be executed in a Kubernetes cluster. By using this function, the Data Science team can easily integrate their custom Python code into the Kubeflow Pipelines SDK without having to learn the details of containerization or Kubernetes.
NEW QUESTION # 100
......
With the cumulative effort over the past years, our Professional-Machine-Learning-Engineer study guide has made great progress with passing rate up to 98 to 100 percent among the market. A lot of professional experts concentrate to making our Professional-Machine-Learning-Engineerpreparation materials by compiling the content so they have gained reputation in the market for their proficiency and dedication. About some esoteric points, they illustrate with examples for you on the Professional-Machine-Learning-Engineer Exam Braindumps.
Practice Professional-Machine-Learning-Engineer Exam Fee: https://www.practicematerial.com/Professional-Machine-Learning-Engineer-exam-materials.html
2026 Latest PracticeMaterial Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1JA9naFoay5IdiSdM579XCvO8mSWzj7HU