The only aim of our company is to help each customer pass their exam as well as getting the important certification in a short time. If you want to pass your exam and get the AI-200 certification which is crucial for you successfully, I highly recommend that you should choose the AI-200 certification preparation materials from our company so that you can get a good understanding of the exam that you are going to prepare for. We believe that if you decide to buy the AI-200 Exam Materials from our company, you will pass your exam and get the certification in a more relaxed way than other people.
| Section | Weight | Objectives |
|---|---|---|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
>> AI-200 Training Materials <<
You plan to place an order for our Microsoft AI-200 test questions answers; you should have a credit card. Mostly we just support credit card. If you just have debit card, you should apply a credit card or you can ask other friend to help you pay for AI-200 Test Questions Answers.
NEW QUESTION # 111
You are building a RAG (retrieval-augmented generation) solution using Azure AI Foundry. The knowledge base consists of 50,000 PDF documents stored in Azure Blob Storage.
You need to make the document content searchable by the language model with minimal custom code.
What should you use?
Answer: C
Explanation:
Use Azure AI Search integrated vectorization with a skillset . Integrated vectorization automates the main ingestion stages required for RAG: an Azure AI Search indexer can read documents directly from a supported data source such as Azure Blob Storage, extract and split document content into chunks, invoke an embedding model, and store both searchable text and vector representations in the search index. Microsoft specifically states that integrated vectorization reduces development and maintenance effort because developers do not need to implement the chunking and embedding pipeline manually.
A skillset can include a Text Split skill for chunking and an Azure OpenAI Embedding skill or another supported embedding skill for vector generation. At query time, a matching vectorizer can convert user questions into vectors so Azure AI Search can perform similarity or hybrid retrieval for grounding the language model.
Custom text classification solves a different NLP problem. Building Azure Functions to process all 50,000 PDFs manually would introduce unnecessary custom orchestration and maintenance. Azure Table Storage does not provide the native vector-search and RAG indexing capabilities required here.
Study Guide references: Azure AI Search # integrated vectorization; indexers; skillsets; Text Split skill; embedding skills; vector indexes; RAG retrieval.
NEW QUESTION # 112
You are building a RAG (retrieval-augmented generation) solution using Azure AI Foundry. The knowledge base consists of 50,000 PDF documents stored in Azure Blob Storage. You need to make the document content searchable by the language model with minimal custom code. What should you use?
Answer: C
Explanation:
Azure AI Search's integrated vectorization feature lets you point a skillset directly at a blob data source, and it handles chunking, embedding generation (via an Azure OpenAI embedding model), and indexing automatically -- minimizing custom code compared to manually building a chunking/embedding pipeline.
NEW QUESTION # 113
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to deploy Azure Function resources and apps to meet the business and technical requirements. What should you use?
Answer: B
Explanation:
GitHub Actions is the correct tool to use.
Automated Pipeline: It natively automates infrastructure deployment (Bicep) and code compilation through version-controlled workflows.
Eliminates Local Deployments: Workloads are triggered by repository events (like a code merge), removing the need for manual command-line interventions.
Auditability & Repeatability: It keeps a centralized log of every deployment, ensuring a clear audit trail for governance.
Scenario:
Technical Requirements
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Business Requirements
Development efforts must be minimized.
Reference:
https://github.com/marketplace/actions/azure-functions-action
NEW QUESTION # 114
Hotspot Question
You are building a semantic search feature for a chatbot. You store document embeddings in Redis.
You review the following Python code that connects to Redis and stores an embedding value: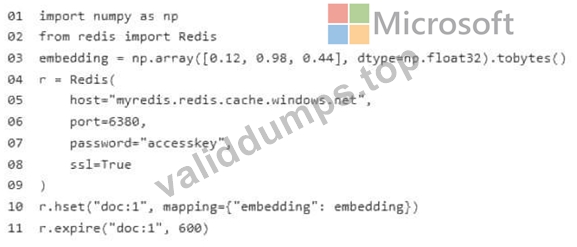
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.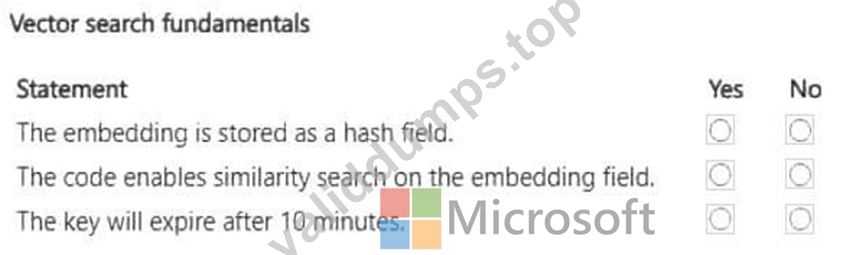
Answer:
Explanation: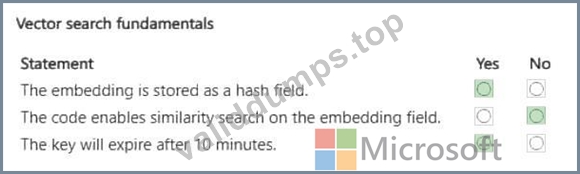
Explanation:
Box 1: Yes
The line r.hset("doc:1", mapping={"embedding": embedding}) will store the embedding as a field within a Redis Hash.
Box 2: No
Box 3: Yes
Reference:
https://redis.io/docs/latest/commands/expire/
NEW QUESTION # 115
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts. You need a solution that requires no custom model training. What should you use?
Answer: D
Explanation:
The prebuilt invoice model in Azure AI Document Intelligence is trained to recognize common invoice fields (vendor, total, line items, invoice number) out of the box across varied layouts, requiring no training data or custom model.
NEW QUESTION # 116
......
The format name of AI-200 practice test questions is APICS PDF Questions file, desktop practice test software, and web-based practice test software. Choose the nay type of AI-200 Practice Exam Questions that fit your AI-200 exam preparation requirement and budget and start preparation without wasting further time.
Exam Dumps AI-200 Free: https://www.validdumps.top/AI-200-exam-torrent.html