さらに、Japancert DP-600ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1Ff0fcQD7ljKTu7ZuoWosY30vrCTjUWn2
MicrosoftのDP-600試験に趣味があると、躊躇わなく、我々Japancertで問題集のデーモをダウンロードして試すことができます。デーモ版によって、このDP-600問題集はあなたに適合するかと判断します。適合すると、あなたは安心で購買できます。弊社JapancertのDP-600問題集は必ずあなたの成功へ道の秘訣です。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Exam Duration: | 120 minutes |
| Available Languages: | Korean, Chinese (Simplified), English, Japanese |
| Certificate Validity Period: | 1 year |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Exam Format: | Case studies, Multiple-choice, Drag-and-drop |
| Passing Score: | 700/1000 |
| Exam Price: | $165 USD |
| Real Exam Qty: | 40-60 |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
Microsoft DP-600テスト質問の回答を注文する予定です。 クレジットカードが必要です。 ほとんどの場合、クレジットカードをサポートしています。 デビットカードをお持ちの場合は、クレジットカードを申請するか、他の友人にDP-600テスト質問の回答の支払いを手伝ってもらってください。 通常、候補者はPayPalで支払うことをお勧めします。ここでは、PayPalアカウントを持っている必要はありません。 [PayPal]をクリックすると、クレジットカード支払いに振り替えられます。 DP-600テストの質問の回答にSWREG支払いを選択した場合、一部の国では追加の税金がかかります。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 134
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.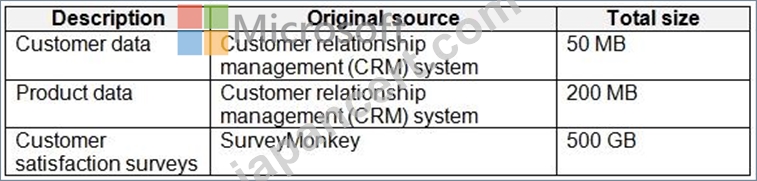
The Product data contains a single table and the following columns.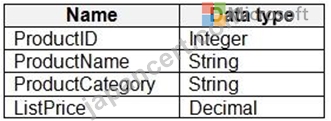
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
Which type of data store should you recommend in the AnalyticsPOC workspace?
正解:C
解説:
The data store must handle semi-structured and unstructured data, therefore a Lakehouse should be the optimal solution supporting read access with T-SQL and Python.
質問 # 135
You have a Fabric tenant that contains two workspaces named Workspace1 and Workspace2.
Workspace1 is used as the development environment.
Workspace2 is used as the production environment.
Each environment uses a different storage account.
Workspace1 contains a Dataflow Gen2 named Dataflow1. The data source of Dataflow1 is a CSV file in blob storage.
You plan to implement a deployment pipeline to deploy items from Workspace1 to Workspace2.
You need to ensure that the data source references the correct location in the production environment.
What should you do?
正解:A
解説:
Scenario:
Dev = Workspace1 with Dataflow Gen2 (source = blob storage CSV).
Prod = Workspace2, different storage account.
Need: ensure deployed dataflow points to the production storage location .
Analysis:
Data source rules : used to remap data sources between environments (e.g., blob storage dev # blob storage prod).
Parameter rules : used when the data source location is parameterized (for example, a parameter storing the file path or connection string).
Best practice: use parameters in the dataflow for connection strings, then apply parameter rules in deployment pipelines.
In this case, since the requirement is about ensuring the reference updates correctly, only parameter rules are needed (not data source rules).
.
質問 # 136
You have a Microsoft Power BI semantic model.
You need to identify any surrogate key columns in the model that have the Summarize By property set to a value other than to None. The solution must minimize effort.
What should you use?
正解:C
解説:
Best Practice Analyzer should be able to identify these with some rules.
質問 # 137
You are creating a report and a semantic model in Microsoft Power Bl Desktop.
The Value measure has the expression shown in the following exhibit.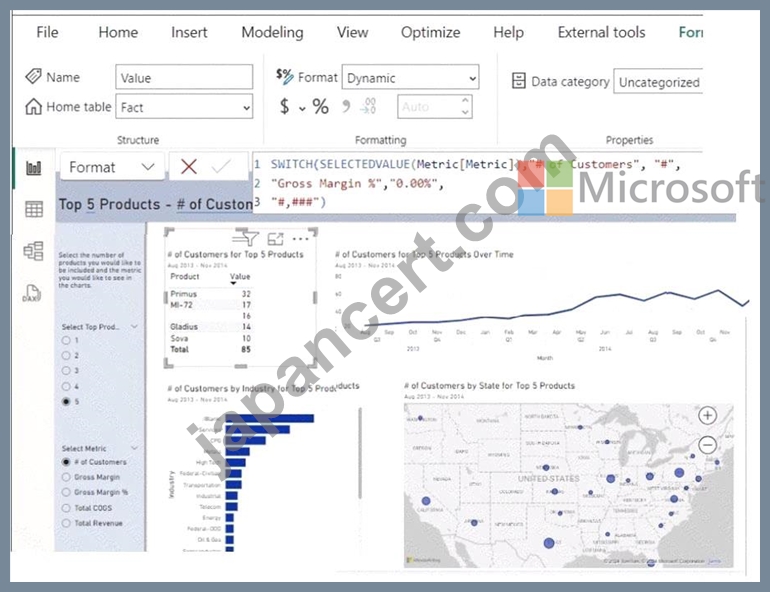
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.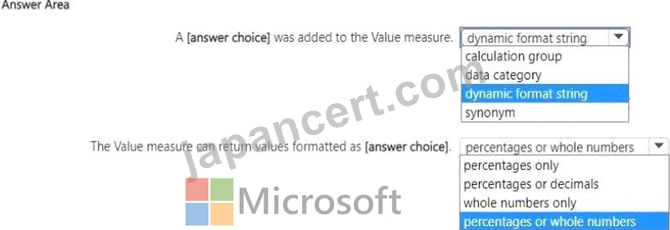
正解:
解説: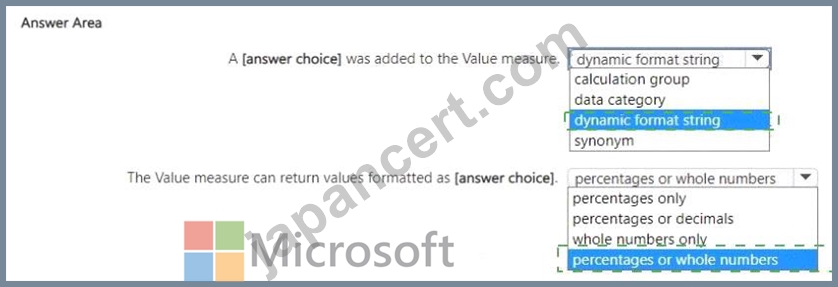
Explanation: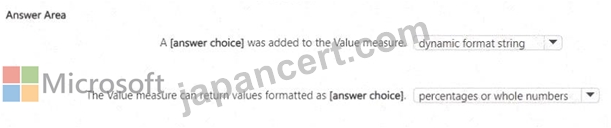
Comprehensive Detailed Explanation
Step 1: Reviewing the provided DAX expression
SWITCH(
SELECTEDVALUE(Metric[Metric]),
" # of Customers " , " # " ,
" Gross Margin % " , " 0.00% " ,
" #,### "
)
This is applied as a dynamic format string.
It changes the display formatting of the Value measure depending on the selected metric.
Step 2: Identify the feature
The screenshot shows Format = Dynamic in the Power BI Modeling tab.
This confirms that a dynamic format string has been applied.
So, for the first blank # dynamic format string.
Step 3: Identify the output formats
If the metric = # of Customers # format is " # " # whole numbers.
If the metric = Gross Margin % # format is " 0.00% " # percentages.
Fallback # " #,### " # also whole numbers.
Thus, the measure supports both whole numbers and percentages.
So, for the second blank # percentages or whole numbers.
References
Dynamic format strings in Power BI
SWITCH function in DAX
質問 # 138
You have a Fabric tenant that contains a Microsoft Power Bl report named Report 1.
Report1 is slow to render. You suspect that an inefficient DAX query is being executed.
You need to identify the slowest DAX query, and then review how long the query spends in the formula engine as compared to the storage engine.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.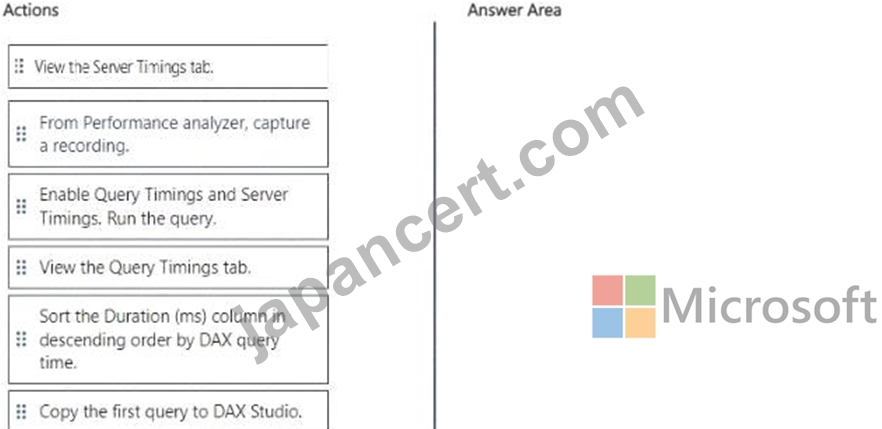
正解:
解説: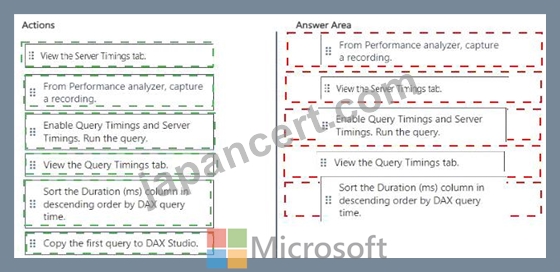
Explanation:
To identify the slowest DAX query and analyze the time it spends in the formula engine compared to the storage engine, you should perform the following actions in sequence:
* From Performance analyzer, capture a recording.
* View the Server Timings tab.
* Enable Query Timings and Server Timings. Run the query.
* View the Query Timings tab.
* Sort the Duration (ms) column in descending order by DAX query time.
質問 # 139
......
DP-600コンポーネント: https://www.japancert.com/DP-600.html
2026年Japancertの最新DP-600 PDFダンプおよびDP-600試験エンジンの無料共有:https://drive.google.com/open?id=1Ff0fcQD7ljKTu7ZuoWosY30vrCTjUWn2