2026 Latest LatestCram DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL
A bold attempt is half success. Stop hesitating again, just try and choose our DP-750 test braindump. Please trust me, if you pay attention on dumps content, even just remember the questions and answers you will clear your exam surely. DP-750 test braindump will be the right key to your exam success. As long as the road is right, success is near. Don't be over-anxious, wasting time is robbing oneself. Our Microsoft DP-750 test braindump will be definitely useful for your test and 100% valid. Money Back Guaranteed!
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
One of the key factors for passing the exam is practice. Candidates must use DP-750 practice test material to be able to perform at their best on the real exam. This is why LatestCram has developed three formats to assist candidates in their Microsoft DP-750 Preparation. These formats include desktop-based Microsoft DP-750 practice test software, web-based practice test, and a PDF format.
NEW QUESTION # 18
Drag and Drop Question
You have an Azure Databricks workspace that contains an all-purpose compute cluster named Cluster1. Cluser1 is used for interactive development.
You need to configure Cluster1 to meet the following requirements:
- Automatically add and remove worker nodes based on workload demand.
- Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.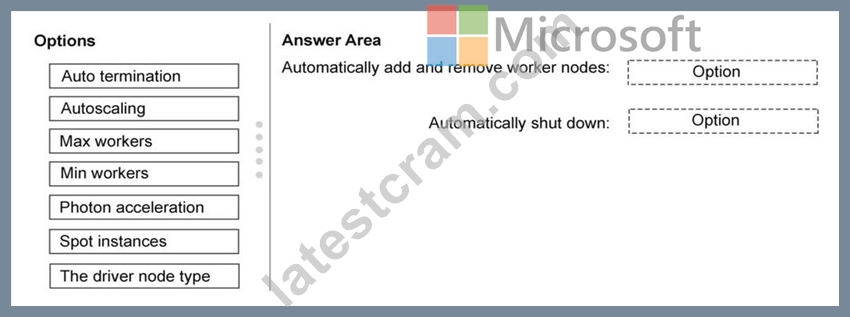
Answer:
Explanation: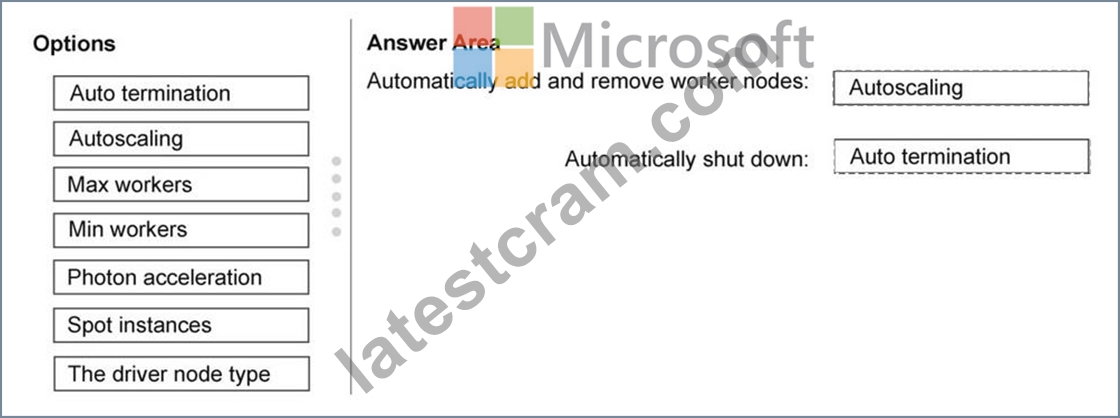
NEW QUESTION # 19
What improves join performance for small lookup tables?
Answer: C
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.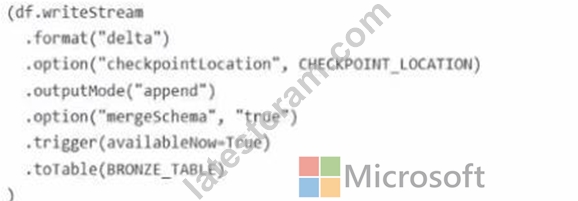
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.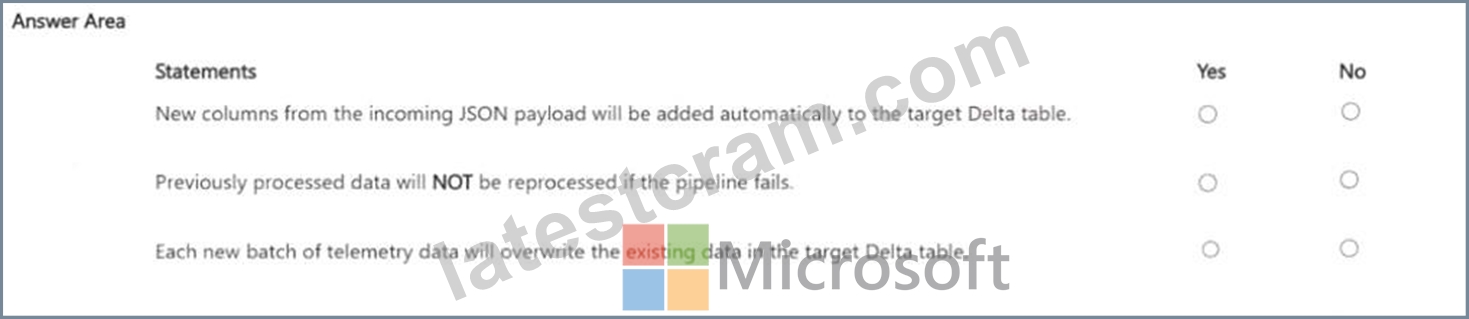
Answer:
Explanation: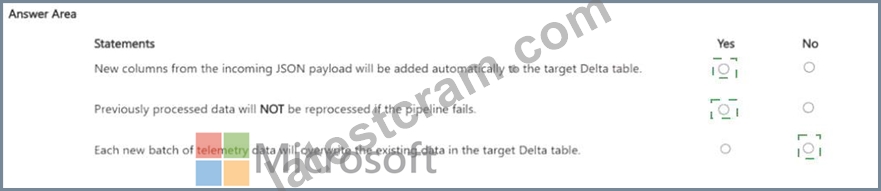
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 21
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.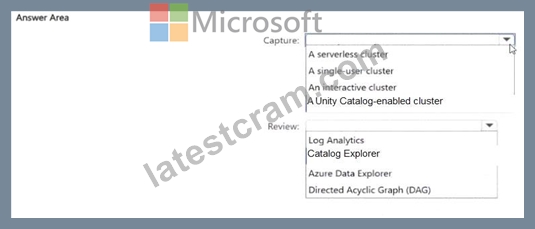
Answer:
Explanation: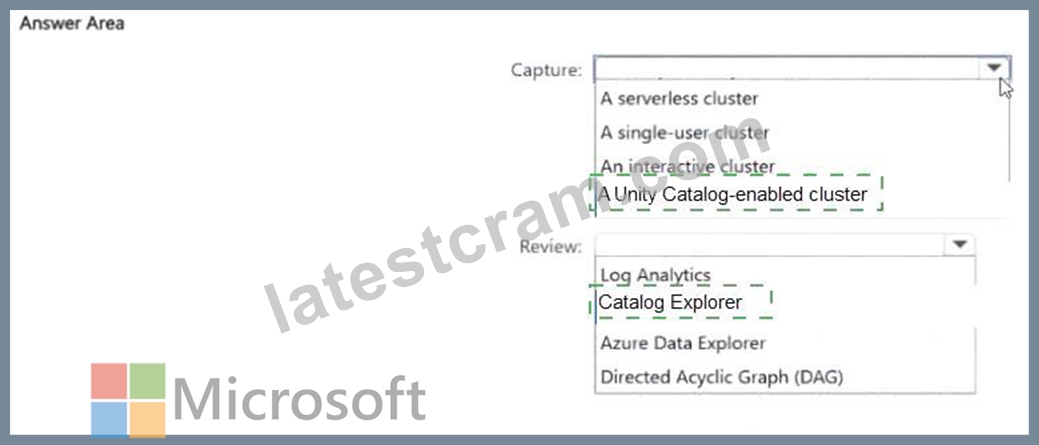
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 22
You have an Azure Databricks workspace that is enabled for Unity Catalog You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Answer: C
Explanation:
The correct answer is B - configure a checkpoint location.
A checkpoint is the Structured Streaming mechanism for fault tolerance. Databricks writes the committed offset (i.e., how far through the source stream the job has successfully read and processed) to a durable path in ADLS Gen2 or DBFS after each micro-batch. When the cluster restarts, the engine reads that offset and resumes from the next unprocessed record - nothing is reprocessed, nothing is skipped.
Option A (increase trigger interval) affects how frequently micro-batches run but does nothing to record progress between runs. Option C (watermark) handles late-arriving events in event-time windows but doesn't control source offset tracking. Option D (enable CDF on the target table) tracks changes made to a Delta table for downstream consumers - it has no bearing on the streaming job's own fault tolerance or offset management.
Checkpointing is a required configuration for any production streaming job. Without it, every cluster restart triggers a full replay from the source.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 23
......
I believe that people want to have good prospects of career whatever industry they work in. Of course, there is no exception in the competitive IT industry. IT Professionals working in the IT area also want to have good opportunities for promotion of job and salary. A lot of IT professional know that Microsoft Certification DP-750 Exam can help you meet these aspirations. LatestCram is a website which help you successfully pass Microsoft DP-750.
Valid DP-750 Exam Tutorial: https://www.latestcram.com/DP-750-exam-cram-questions.html
DOWNLOAD the newest LatestCram DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL