Our Developing AI Cloud Solutions on Azure exam question has been widely praised by all of our customers in many countries and our company has become the leader in this field. Our product boost varied functions and they include the self-learning and the self-assessment functions, the timing function and the function to stimulate the exam to make you learn efficiently and easily. Thus you could decide whether it is worthy to buy our product or not after you understand the features of details of our product carefully on the pages of our AI-200 Study Tool on the website.
| Section | Objectives |
|---|---|
| Topic 1: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 4: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> AI-200 Valid Braindumps Files <<
Improvement in AI-200 science and technology creates unassailable power in the future construction and progress of society. AI-200 practice test can be your optimum selection and useful tool to deal with the urgent challenge. With over a decade's striving, our AI-200 training materials have become the most widely-lauded and much-anticipated products in industry. We have full technical support from our professional elites in planning and designing AI-200 Practice Test. Do not hesitate anymore. You will never regret buying AI-200 study engine!
NEW QUESTION # 134
You develop an application that sells Al generated images based on user input. You recently started a marketing campaign that displays unique ads every second day.
Sales data is stored in Azure Cosmos 06 with the date of each sale being stored in a property named whenFinished ' . The marketing department requires a view that shows the number of sales grouped into two- day periods You need to implement the query for the view.
How should you complete the query? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.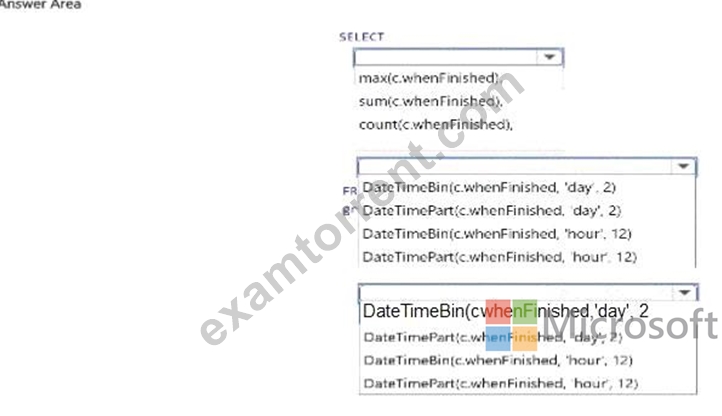
Answer:
Explanation: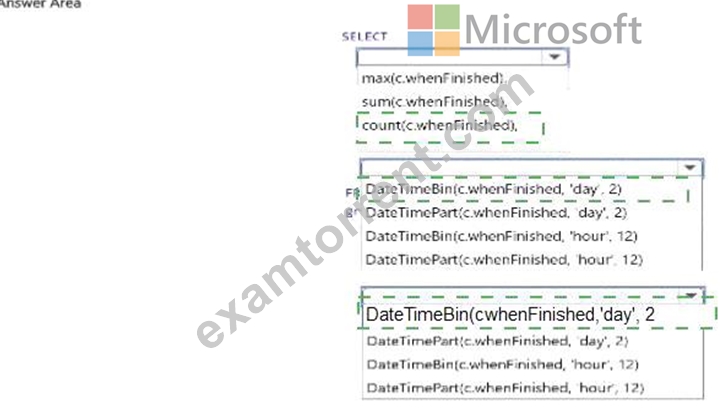
Explanation: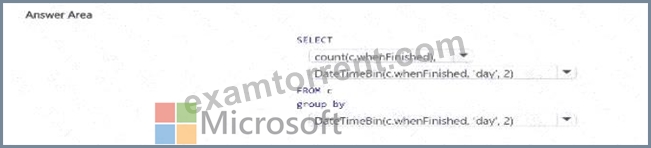
NEW QUESTION # 135
You plan to deploy a container to an Azure App Service API app named api1. You host the source code for api1 in a GitHub repository. The container uses the API key at runtime to connect to a backend service.
The container must be able to retrieve the API key at runtime without exposing it in the source repository or Git commit history. The API key must not be stored in application configuration directly. The API key must be accessed securely from Azure Key Vault.
You need to ensure that the API key is stored securely in Azure Key Vault and is available to the container at runtime without being exposed in source control or Git commit history.
Solution: Store the API key as an App Service application setting configured through the Azure Portal.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 136
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.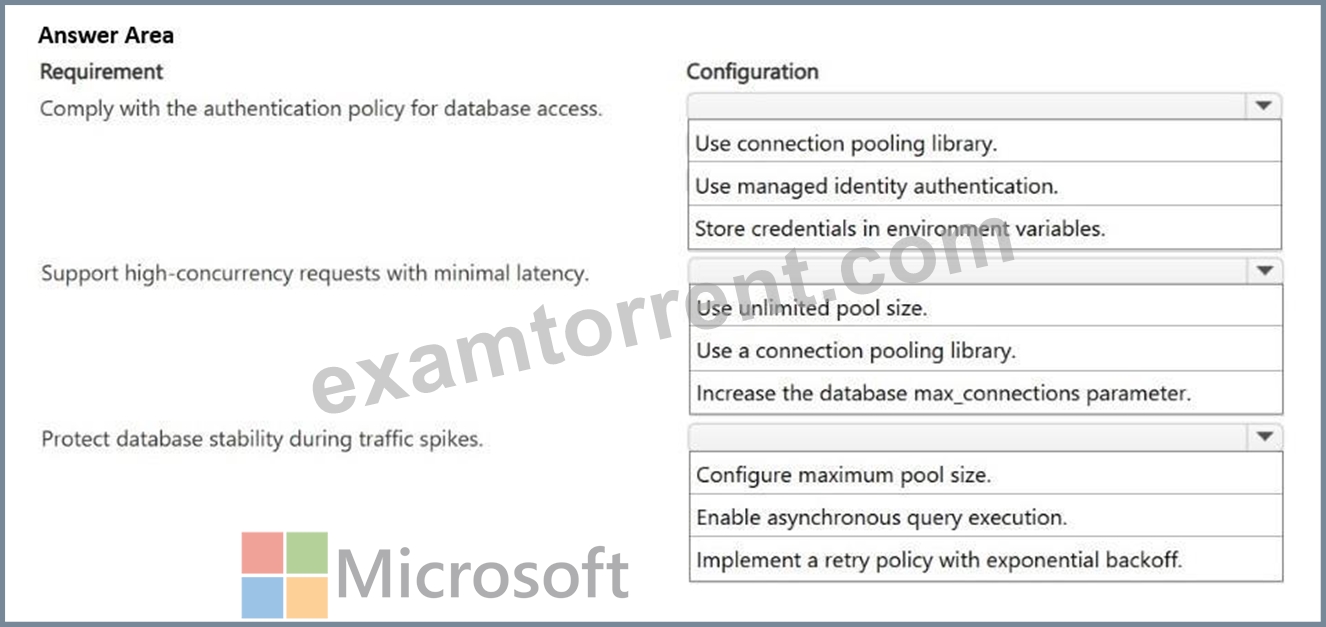
Answer:
Explanation: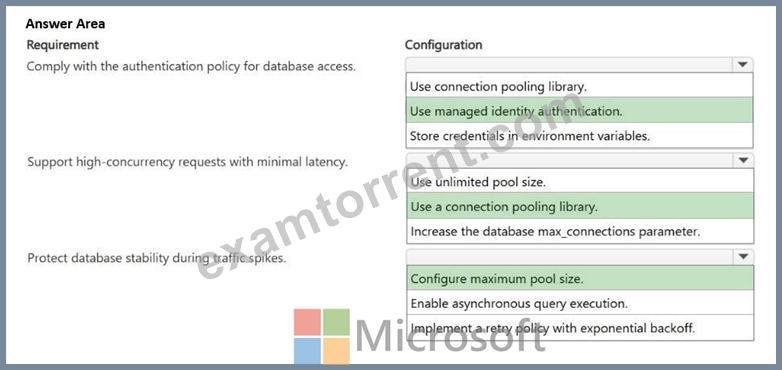
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
NEW QUESTION # 137
You configure ACR Tasks to automate image builds.
Container images must rebuild when:
- Application updates occur.
- Base image updates occur, such as when the underlying OS image is
updated.
- Regular scheduled rebuilds are required.
You need to configure ACR Tasks to support automated image rebuilds.
Which three triggers should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C,D
Explanation:
To support automated container image rebuilds based on your requirements, you need to configure source triggers, base image triggers, and timer triggers in Azure Container Registry (ACR) Tasks.
Timer Triggers: Automates regular scheduled rebuilds. This uses a cron schedule expression to run image builds at specific intervals (e.g., weekly or monthly) regardless of code changes.
Source Triggers: Automates rebuilds when application updates occur. This monitors changes in your source code repository (like GitHub or Azure Repos) and fires a build when code is committed.
Base Image Triggers: Automates rebuilds when the underlying OS or framework image updates.
ACR tracks dependencies and automatically kicks off a new build when your defined FROM image changes in the public registry or your private registry.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-acr-tasks-for-automated-container-image-builds-on-git-commit/view
NEW QUESTION # 138
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule.
You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
[A]
QeueName: The exact name of the specific Azure Storage queue your app is polling is required.
[C]
Why Trigger Type is Required
When configuring a custom scale rule in Azure Container Apps (ACA), the platform utilizes KEDA underneath. Because a custom rule can connect to many different event sources (such as Kafka, Redis, or Azure Storage), you must explicitly define the Trigger type (e.g., azure-queue) so KEDA knows which specific scaler to initiate.
Reference:
https://techcommunity.microsoft.com/blog/fasttrackforazureblog/container-apps-a-practical-scaling-with-azure-queue-scale-rule/3722075
NEW QUESTION # 139
......
There is no such excellent exam material like our ExamTorrent AI-200 exam materials. We not only provide all candidates with most reliable guarantee, but also have best customer support. Our AI-200 exam material’s efficient staff is always prompt to respond you. If you have any doubts about our exam materials and need detailed answer, you can send emails to our customers’ care department. If you are in hurry, you can consult our AI-200 exam material’s online customer service. We will solve your problem as soon as possible. Our customer support is available for you 24/7. 365 days a Year. Our ExamTorrent AI-200 Exam Materials have managed to build an excellent relationship with our users through the mutual respect and attention we provide to everyone. We believed that you will pass the AI-200 exam in the first attempt without any obstacles, and will get your ideal job.
AI-200 Latest Material: https://www.examtorrent.com/AI-200-valid-vce-dumps.html