The high pass rate coming from our customers who have passed the exam after using our Databricks-Certified-Data-Engineer-Associate exam software, and our powerful technical team make us proudly say that our BraindumpsPass is very professional. The after-sale customer service is an important standard to balance whether a company is better or not, so in order to make it, we provide available 24/7 online service, one-year free update service after payment, and the promise of "No help, full refund", so please be rest assured to choose our product if you want to pass the Databricks-Certified-Data-Engineer-Associate Exam.
| Section | Objectives |
|---|---|
| Topic 1: Databricks Lakehouse Platform Fundamentals | - Clusters, notebooks, and basic Databricks environment usage - Workspace, architecture, and core platform concepts |
| Topic 2: Data Processing and Transformations | - User-defined functions (UDFs) - PySpark DataFrame transformations - Apache Spark SQL operations (joins, aggregations, filtering) - Delta Lake fundamentals (tables, transactions, optimization) |
| Topic 3: Productionizing Data Pipelines | - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration - Pipeline deployment and operationalization |
| Topic 4: Data Governance and Quality | - Data access control and governance - Data quality concepts and management - Unity Catalog basics |
| Topic 5: Data Ingestion and ELT Development | - ETL patterns and transformations - Data ingestion using Spark SQL and PySpark - Handling structured and semi-structured data |
>> Exam Databricks-Certified-Data-Engineer-Associate Collection Pdf <<
Our Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) PDF dumps format contains Databricks Databricks-Certified-Data-Engineer-Associate questions that are real and updated. You can print these Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) questions if you prefer an off-screen study. Otherwise, you can use this Databricks-Certified-Data-Engineer-Associate PDF document from any location via your laptops, tablets, and smartphones. Time restrictions do not halt Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam preparation as you can use Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps pdf whenever you have free time.
NEW QUESTION # 177
A data engineering team has two tables. The first table march_transactions is a collection of all retail transactions in the month of March. The second table april_transactions is a collection of all retail transactions in the month of April. There are no duplicate records between the tables.
Which of the following commands should be run to create a new table all_transactions that contains all records from march_transactions and april_transactions without duplicate records?
Answer: C
Explanation:
The correct command to create a new table that contains all records from two tables without duplicate records is to use the UNION operator. The UNION operator combines the results of two queries and removes any duplicate rows. The INNER JOIN, OUTER JOIN, and MERGE operators do not remove duplicate rows, and the INTERSECT operator only returns the rows that are common to both tables. Therefore, option B is the only correct answer. References: Databricks SQL Reference - UNION, Databricks SQL Reference - JOIN, Databricks SQL Reference - MERGE, [Databricks SQL Reference - INTERSECT]
NEW QUESTION # 178
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: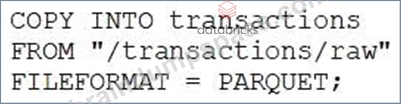
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: E
Explanation:
Explanation
https://docs.databricks.com/en/ingestion/copy-into/index.html The COPY INTO SQL command lets you load data from a file location into a Delta table. This is a re-triable and idempotent operation; files in the source location that have already been loaded are skipped. if there are no new records, the only consistent choice is C no new files were loaded because already loaded files were skipped.
NEW QUESTION # 179
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
Answer: B
Explanation:
In Production mode, the pipeline runs continuously and updates the output tables whenever new data is available in the input sources. The compute resources are allocated on demand and released when the pipeline is stopped. This mode is suitable for production workloads that require high availability and reliability. Reference: Configure pipeline settings for Delta Live Tables, Tutorial: Run your first Delta Live Tables pipeline, Building Reliable Data Pipelines Using DataBricks' Delta Live Tables
NEW QUESTION # 180
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: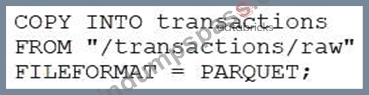
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: E
Explanation:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
NEW QUESTION # 181
A data engineer needs to apply custom logic to identify employees with more than 5 years of experience in array column employees in table stores. The custom logic should create a new column exp_employees that is an array of all of the employees with more than 5 years of experience for each row. In order to apply this custom logic at scale, the data engineer wants to use the FILTER higher-order function.
Which of the following code blocks successfully completes this task?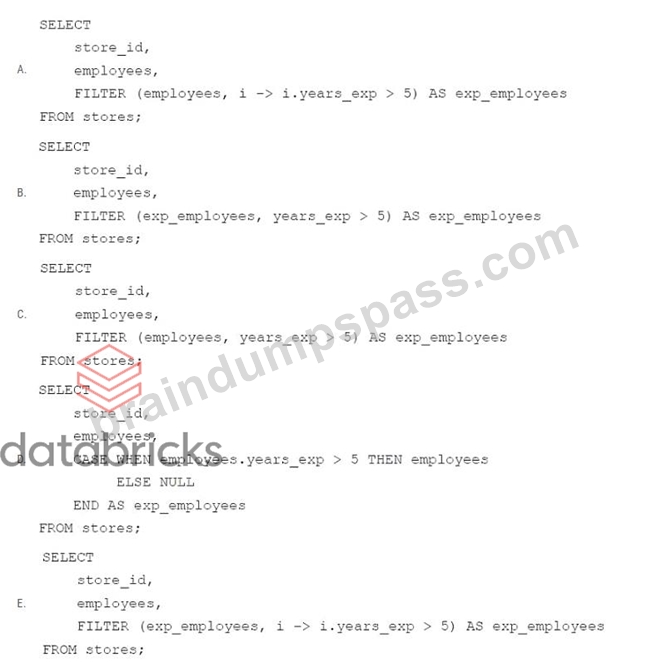
Answer: D
Explanation:
Option A is the correct answer because it uses the FILTER higher-order function correctly to filter out employees with more than 5 years of experience from the array column "employees". It applies a lambda function i -> i.years_exp > 5 that checks if the years of experience of each employee in the array is greater than 5. If this condition is met, the employee is included in the new array column "exp_employees".
The use of higher-order functions like FILTER can be referenced from Databricks documentation on Higher-Order Functions.
NEW QUESTION # 182
......
If people buy and use the Databricks-Certified-Data-Engineer-Associate study tool with bad quality to prepare for their exams, it must do more harm than good for their exams, thus it can be seen that the good and suitable Databricks-Certified-Data-Engineer-Associateguide question is so important for people’ exam that people have to pay more attention to the study materials. In order to help people pass the exam and gain the certification, we are glad to the Databricks-Certified-Data-Engineer-Associate Study Tool from our company for you. We can promise that our study materials will be very useful and helpful for you to prepare for your exam.
Databricks-Certified-Data-Engineer-Associate Valid Dumps Ppt: https://www.braindumpspass.com/Databricks/Databricks-Certified-Data-Engineer-Associate-practice-exam-dumps.html