Certified-Data-Engineer-Professional題庫資料 & Certified-Data-Engineer-Professional考試指南

Databricks Certified-Data-Engineer-Professional 認證考試在IT行業裏有著舉足輕重的地位,相信這是很多專業的IT人士都認同的。通過Databricks Certified-Data-Engineer-Professional 認證考試是有一定的難度的,需要過硬的IT知識和經驗,因為畢竟Databricks Certified-Data-Engineer-Professional 認證考試是權威的檢驗IT專業知識的考試。如果你拿到了Databricks Certified-Data-Engineer-Professional 認證證書,你的IT職業能力是會被很多公司認可的。NewDumps在IT培訓行業中也是一個駐足輕重的網站,很多已經通過Databricks Certified-Data-Engineer-Professional 認證考試的IT人員都是使用了NewDumps的幫助才通過考試的。這就說明NewDumps提供的針對性培訓資料是很有效的。如果你使用了我們提供的培訓資料,您可以100%通過考試。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 2: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 3: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 4: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 5: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 6: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 7: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 8: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 10: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
>> Certified-Data-Engineer-Professional題庫資料 <<
Certified-Data-Engineer-Professional考試指南 & Certified-Data-Engineer-Professional考證
很多考生都是因為 Databricks Certified-Data-Engineer-Professional 考試失敗了,對任何考試都提不起任何興趣,專業從事最新 Databricks Certified-Data-Engineer-Professional 認證考題編定的 Certified-Data-Engineer-Professional 考題幫助很多考生擺脫 Certified-Data-Engineer-Professional 考試不能順利過關的挫敗心理。Certified-Data-Engineer-Professional擬真試題已經被很多考生使用,並且得到了眾多的好評。因為該考題具備了覆蓋率很高,能夠消除考生對考試的疑慮;貼心服務,讓考生安心輕鬆通過考試,責任心強,把考生通過考試當作自己的事情來對待!
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q16-Q21):
問題 #16
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of
1:2. What are the two steps the data engineer should take to minimize spillage? (Choose two.)
- A. Choose a compute instance with more disk space.
- B. Choose a compute instance with more network bandwidth.
- C. Choose a compute instance with a higher core-to-memory ratio.
- D. Reduce spark.sql.files.maxPartitionBytes.
- E. Increase spark.sql.files.maxPartitionBytes.
答案:C,D
解題說明:
Databricks recommends addressing disk spilling--which occurs when Spark tasks run out of memory--by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory.
Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
問題 #17
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
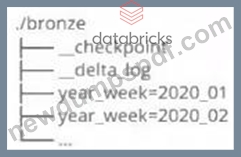
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. Yes; both of the streams can share a single checkpoint directory.
- B. No; Delta Lake manages streaming checkpoints in the transaction log.
- C. Yes; Delta Lake supports infinite concurrent writers.
- D. No; only one stream can write to a Delta Lake table.
- E. No; each of the streams needs to have its own checkpoint directory.
答案:E
解題說明:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
問題 #18
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- B. It ignores deletions if they arrive after updates for the same key.
- C. It runs VACUUM on the target table to purge conflicting records.
- D. It manually sorts incoming events by timestamp before applying changes.
答案:A
解題說明:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
問題 #19
Which of the following is true of Delta Lake and the Lakehouse?
- A. Z-order can only be applied to numeric values stored in Delta Lake tables
- B. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- C. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- D. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- E. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
答案:B
解題說明:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
問題 #20
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
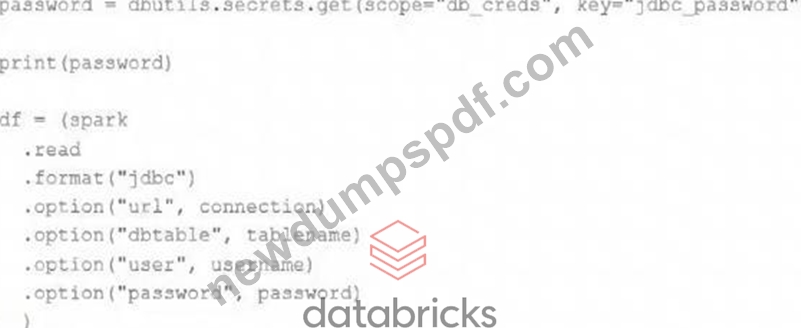
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will fail; the string "redacted" will be printed.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- C. The connection to the external table will succeed; the string "redacted" will be printed.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- E. The connection to the external table will succeed; the string value of password will be printed in plain text.
答案:C
解題說明:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
問題 #21
......
NewDumps的資深專家團隊研究出了針對Databricks Certified-Data-Engineer-Professional考試的培訓教材。通過NewDumps提供的教材培訓和學習,通過Databricks Certified-Data-Engineer-Professional 認證考試將會很簡單。NewDumps能100%保證你首次參加Databricks Certified-Data-Engineer-Professional 認證考試就可以成功通過。我們給你提供的考試練習題和答案將在你考試的時候會出現。當你選擇了我們的幫助,NewDumps承諾給你一份準確而全面的考試資料,而且會給你提供一年的免費更新服務。
Certified-Data-Engineer-Professional考試指南: https://www.newdumpspdf.com/Certified-Data-Engineer-Professional-exam-new-dumps.html
- 最新Certified-Data-Engineer-Professional題庫資訊 💖 Certified-Data-Engineer-Professional考古题推薦 💜 Certified-Data-Engineer-Professional題庫最新資訊 😤 在➥ www.vcesoft.com 🡄網站上查找▶ Certified-Data-Engineer-Professional ◀的最新題庫Certified-Data-Engineer-Professional软件版
- Newdumpspdf Certified-Data-Engineer-Professional題庫資料 /立即下載 🏡 透過➠ www.newdumpspdf.com 🠰搜索{ Certified-Data-Engineer-Professional }免費下載考試資料Certified-Data-Engineer-Professional題庫最新資訊
- 最新Certified-Data-Engineer-Professional題庫 🧬 Certified-Data-Engineer-Professional软件版 📊 Certified-Data-Engineer-Professional證照考試 ✋ 在⏩ www.vcesoft.com ⏪網站上查找▛ Certified-Data-Engineer-Professional ▟的最新題庫Certified-Data-Engineer-Professional考古题推薦
- Certified-Data-Engineer-Professional考試題庫 🎧 Certified-Data-Engineer-Professional測試 🗳 最新Certified-Data-Engineer-Professional試題 🏧 在☀ www.newdumpspdf.com ️☀️搜索最新的➠ Certified-Data-Engineer-Professional 🠰題庫最新Certified-Data-Engineer-Professional題庫資訊
- www.pdfexamdumps.com Certified-Data-Engineer-Professional題庫資料 /立即下載 🕑 在“ www.pdfexamdumps.com ”網站下載免費{ Certified-Data-Engineer-Professional }題庫收集Certified-Data-Engineer-Professional題庫更新
- 最受歡迎的Certified-Data-Engineer-Professional題庫資料,免費下載Certified-Data-Engineer-Professional考試資料幫助妳通過Certified-Data-Engineer-Professional考試 🚅 透過⮆ www.newdumpspdf.com ⮄輕鬆獲取➠ Certified-Data-Engineer-Professional 🠰免費下載Certified-Data-Engineer-Professional測試引擎
- 高質量的Certified-Data-Engineer-Professional題庫資料,全面覆蓋Certified-Data-Engineer-Professional考試知識點 ☸ 透過▶ tw.fast2test.com ◀搜索➥ Certified-Data-Engineer-Professional 🡄免費下載考試資料Certified-Data-Engineer-Professional考試心得
- Certified-Data-Engineer-Professional題庫資訊 ↩ Certified-Data-Engineer-Professional考試題庫 🧬 Certified-Data-Engineer-Professional最新題庫資源 👧 ⏩ www.newdumpspdf.com ⏪最新➽ Certified-Data-Engineer-Professional 🢪問題集合Certified-Data-Engineer-Professional考題免費下載
- Certified-Data-Engineer-Professional考題資訊 🚴 最新Certified-Data-Engineer-Professional試題 🥴 Certified-Data-Engineer-Professional考古题推薦 😚 在“ www.vcesoft.com ”網站上查找[ Certified-Data-Engineer-Professional ]的最新題庫Certified-Data-Engineer-Professional软件版
- Certified-Data-Engineer-Professional考試心得 😥 Certified-Data-Engineer-Professional題庫更新 🧟 Certified-Data-Engineer-Professional證照考試 👈 ( www.newdumpspdf.com )最新( Certified-Data-Engineer-Professional )問題集合Certified-Data-Engineer-Professional考試心得
- 最新Certified-Data-Engineer-Professional考題 🥥 Certified-Data-Engineer-Professional測試 🔒 最新Certified-Data-Engineer-Professional考題 💒 在⇛ www.newdumpspdf.com ⇚網站上查找{ Certified-Data-Engineer-Professional }的最新題庫Certified-Data-Engineer-Professional考試題庫
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, writeablog.net, www.stes.tyc.edu.tw, Disposable vapes