P.S. Free & New ACD-301 dumps are available on Google Drive shared by ITCertMagic: https://drive.google.com/open?id=1zX9suaY8gmA0CtzhMTYfkv2F8ndeFMLV
Up to now, we have more than tens of thousands of customers around the world supporting our ACD-301 training prep. So our ACD-301 study materials are elemental materials you cannot miss. In your review duration, you can contact with our after-sales section if there are any problems with our ACD-301 Practice Braindumps. They will help you 24/7 all the time. These services assure your avoid any loss.
| Section | Objectives |
|---|---|
| Data Management | - Data types and CDT structures - Record types and data stores |
| Application Design and Architecture | - Solution structuring and application layering - Reusable components and design patterns |
| Expression Language and Logic | - Advanced Appian expression functions - Rule design and optimization |
| Process Modeling | - Advanced process model design - Exception handling and optimization |
| Security and Deployment | - Deployment pipelines and environment management - Security roles and group management |
| User Interface Design | - Interface design and dynamic layouts - User experience best practices |
>> ACD-301 Reliable Dumps Questions <<
With our customizable learning experience and self-assessment features of practice exam software for ACD-301 exam, you will be able to know your strengths and areas of improvement. We provide authentic braindumps for ACD-301 certification exam. In fact, we guarantee that you will pass the ACD-301 Certification Exam on your very first try. If we fail to deliver this promise, we will give your money back! Aside from providing you with the most reliable dumps for ACD-301, we also offer our friendly customer support staff. They will be with you every step of the way.
NEW QUESTION # 24
For each requirement, match the most appropriate approach to creating or utilizing plug-ins Each approach will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.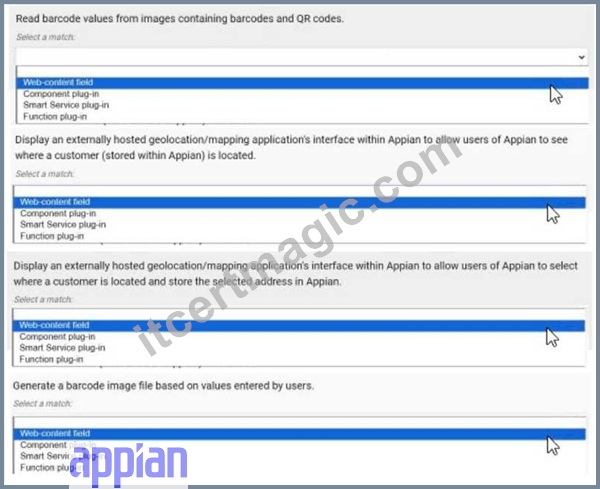
Answer:
Explanation: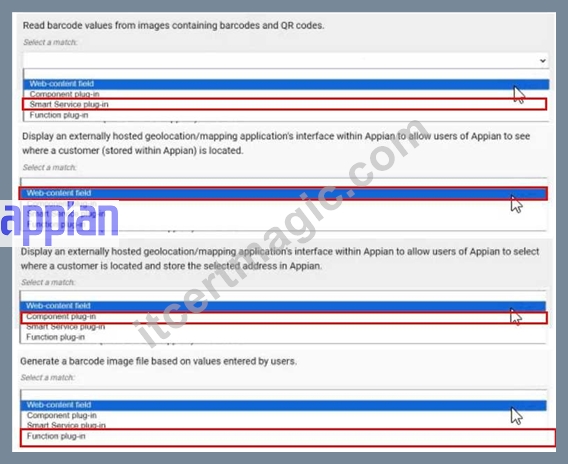
NEW QUESTION # 25
You are the lead developer for an Appian project, in a backlog refinement meeting. You are presented with the following user story:
"As a restaurant customer, I need to be able to place my food order online to avoid waiting in line for takeout." Which two functional acceptance criteria would you consider 'good'?
Answer: B,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, defining "good" functional acceptance criteria for a user story requires ensuring they are specific, testable, and directly tied to the user's need (placing an online food order to avoid waiting in line). Good criteria focus on functionality, usability, and reliability, aligning with Appian's Agile and design best practices. Let's evaluate each option:
A . The user will click Save, and the order information will be saved in the ORDER table and have audit history:
This is a "good" criterion. It directly validates the core functionality of the user story-placing an order online. Saving order data in the ORDER table (likely via a process model or Data Store Entity) ensures persistence, and audit history (e.g., using Appian's audit logs or database triggers) tracks changes, supporting traceability and compliance. This is specific, testable (e.g., verify data in the table and logs), and essential for the user's goal, aligning with Appian's data management and user experience guidelines.
B . The user will receive an email notification when their order is completed:
While useful, this is a "nice-to-have" enhancement, not a core requirement of the user story. The story focuses on placing an order online to avoid waiting, not on completion notifications. Email notifications add value but aren't essential for validating the primary functionality. Appian's user story best practices prioritize criteria tied to the main user need, making this secondary and not "good" in this context.
C . The system must handle up to 500 unique orders per day:
This is a non-functional requirement (performance/scalability), not a functional acceptance criterion. It describes system capacity, not specific user behavior or functionality. While important for design, it's not directly testable for the user story's outcome (placing an order) and isn't tied to the user's experience. Appian's Agile methodologies separate functional and non-functional requirements, making this less relevant as a "good" criterion here.
D . The user cannot submit the form without filling out all required fields:
This is a "good" criterion. It ensures data integrity and usability by preventing incomplete orders, directly supporting the user's ability to place a valid online order. In Appian, this can be implemented using form validation (e.g., required attributes in SAIL interfaces or process model validations), making it specific, testable (e.g., verify form submission fails with missing fields), and critical for a reliable user experience. This aligns with Appian's UI design and user story validation standards.
Conclusion: The two "good" functional acceptance criteria are A (order saved with audit history) and D (required fields enforced). These directly validate the user story's functionality (placing a valid order online), are testable, and ensure a reliable, user-friendly experience-aligning with Appian's Agile and design best practices for user stories.
Appian Documentation: "Writing Effective User Stories and Acceptance Criteria" (Functional Requirements).
Appian Lead Developer Certification: Agile Development Module (Acceptance Criteria Best Practices).
Appian Best Practices: "Designing User Interfaces in Appian" (Form Validation and Data Persistence).
NEW QUESTION # 26
An Appian application contains an integration used to send a JSON, called at the end of a form submission, returning the created code of the user request as the response. To be able to efficiently follow their case, the user needs to be informed of that code at the end of the process. The JSON contains case fields (such as text, dates, and numeric fields) to a customer's API. What should be your two primary considerations when building this integration?
Answer: A,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, building an integration to send JSON to a customer's API and return a code to the user involves balancing usability, performance, and reliability. The integration is triggered at form submission, and the user must see the response (case code) efficiently. The JSON includes standard fields (text, dates, numbers), and the focus is on primary considerations for the integration itself. Let's evaluate each option based on Appian's official documentation and best practices:
A . A process must be built to retrieve the API response afterwards so that the user experience is not impacted:
This suggests making the integration asynchronous by calling it in a process model (e.g., via a Start Process smart service) and retrieving the response later, avoiding delays in the UI. While this improves user experience for slow APIs (e.g., by showing a "Processing" message), it contradicts the requirement that the user is "informed of that code at the end of the process." Asynchronous processing would delay the code display, requiring additional steps (e.g., a follow-up task), which isn't efficient for this use case. Appian's default integration pattern (synchronous call in an Integration object) is suitable unless latency is a known issue, making this a secondary-not primary-consideration.
B . The request must be a multi-part POST:
A multi-part POST (e.g., multipart/form-data) is used for sending mixed content, like files and text, in a single request. Here, the payload is a JSON containing case fields (text, dates, numbers)-no files are mentioned. Appian's HTTP Connected System and Integration objects default to application/json for JSON payloads via a standard POST, which aligns with REST API norms. Forcing a multi-part POST adds unnecessary complexity and is incompatible with most APIs expecting JSON. Appian documentation confirms this isn't required for JSON-only data, ruling it out as a primary consideration.
C . The size limit of the body needs to be carefully followed to avoid an error:
This is a primary consideration. Appian's Integration object has a payload size limit (approximately 10 MB, though exact limits depend on the environment and API), and exceeding it causes errors (e.g., 413 Payload Too Large). The JSON includes multiple case fields, and while "hundreds of thousands" isn't specified, large datasets could approach this limit. Additionally, the customer's API may impose its own size restrictions (common in REST APIs). Appian Lead Developer training emphasizes validating payload size during design-e.g., testing with maximum expected data-to prevent runtime failures. This ensures reliability and is critical for production success.
D . A dictionary that matches the expected request body must be manually constructed:
This is also a primary consideration. The integration sends a JSON payload to the customer's API, which expects a specific structure (e.g., { "field1": "text", "field2": "date" }). In Appian, the Integration object requires a dictionary (key-value pairs) to construct the JSON body, manually built to match the API's schema. Mismatches (e.g., wrong field names, types) cause errors (e.g., 400 Bad Request) or silent failures. Appian's documentation stresses defining the request body accurately-e.g., mapping form data to a CDT or dictionary-ensuring the API accepts the payload and returns the case code correctly. This is foundational to the integration's functionality.
Conclusion: The two primary considerations are C (size limit of the body) and D (constructing a matching dictionary). These ensure the integration works reliably (C) and meets the API's expectations (D), directly enabling the user to receive the case code at submission end. Size limits prevent technical failures, while the dictionary ensures data integrity-both are critical for a synchronous JSON POST in Appian. Option A could be relevant for performance but isn't primary given the requirement, and B is irrelevant to the scenario.
Appian Documentation: "Integration Object" (Request Body Configuration and Size Limits).
Appian Lead Developer Certification: Integration Module (Building REST API Integrations).
Appian Best Practices: "Designing Reliable Integrations" (Payload Validation and Error Handling).
NEW QUESTION # 27
Your client's customer management application is finally released to Production. After a few weeks of small enhancements and patches, the client is ready to build their next application. The new application will leverage customer information from the first application to allow the client to launch targeted campaigns for select customers in order to increase sales. As part of the first application, your team had built a section to display key customer information such as their name, address, phone number, how long they have been a customer, etc. A similar section will be needed on the campaign record you are building. One of your developers shows you the new object they are working on for the new application and asks you to review it as they are running into a few issues. What feedback should you give?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The scenario involves reusing a customer information section from an existing application in a new application for campaign management, with the developer encountering issues. Appian's best practices emphasize reusability, efficiency, and maintainability, especially when leveraging existing components across applications.
Option B (Ask the developer to convert the original customer section into a shared object so it can be used by the new application):
This is the recommended approach. Converting the original section into a shared object (e.g., a reusable interface component) allows it to be accessed across applications without duplication. Appian's Design Guide highlights the use of shared components to promote consistency, reduce redundancy, and simplify maintenance. Since the new application requires similar customer data (name, address, etc.), reusing the existing section-after ensuring it is modular and adaptable-addresses the developer's issues while aligning with the client's goal of leveraging prior work. The developer can then adjust the shared object (e.g., via parameters) to fit the campaign context, resolving their issues collaboratively.
Option A (Provide guidance to the developer on how to address the issues so that they can proceed with their work):
While providing guidance is valuable, it doesn't address the root opportunity to reuse existing code. This option focuses on fixing the new object in isolation, potentially leading to duplicated effort if the original section could be reused instead.
Option C (Point the developer to the relevant areas in the documentation or Appian Community where they can find more information on the issues they are running into):
This is a passive approach and delays resolution. As a Lead Developer, offering direct support or a strategic solution (like reusing components) is more effective than redirecting the developer to external resources without context.
Option D (Create a duplicate version of that section designed for the campaign record):
Duplication violates Appian's principle of DRY (Don't Repeat Yourself) and increases maintenance overhead. Any future updates to customer data display logic would need to be applied to multiple objects, risking inconsistencies.
Given the need to leverage existing customer information and the developer's issues, converting the section to a shared object is the most efficient and scalable solution.
NEW QUESTION # 28
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).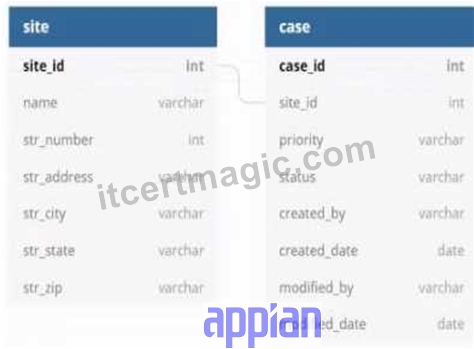
Which three column should be indexed?
Answer: A,B,D
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 29
......
The ACD-301 exam prep is produced by our expert, is very useful to help customers pass their exams and get the certificates in a short time. We are going to show our ACD-301 guide braindumps to you. We can sure that our product will help you get the certificate easily. If you are wailing to believe us and try to learn our ACD-301 Exam Torrent, you will get an unexpected result.
Test ACD-301 Centres: https://www.itcertmagic.com/Appian/real-ACD-301-exam-prep-dumps.html
What's more, part of that ITCertMagic ACD-301 dumps now are free: https://drive.google.com/open?id=1zX9suaY8gmA0CtzhMTYfkv2F8ndeFMLV