Reliable Databricks-Certified-Data-Engineer-Professional Test Questions, New Databricks-Certified-Data-Engineer-Professional Test Topics

You have to upgrade your skills and knowledge then you will be in a position to compete in the modern world. The Databricks Databricks-Certified-Data-Engineer-Professional certification offers a great way to learn new in-demand skills and upgrade your knowledge level. To do this you just need to enroll in the Databricks-Certified-Data-Engineer-Professional Exam and put in your efforts to pass this career booster Databricks-Certified-Data-Engineer-Professional certification exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Processing | 28% | - Structured Streaming
- ETL Pipelines
- Data Transformation
- Spark SQL
|
| Topic 2: Monitoring and Troubleshooting | 16% | - Monitoring
- Troubleshooting
- Performance Optimization
|
| Topic 3: Databricks Lakehouse Platform | 24% | - Unity Catalog
- Lakehouse Architecture
- Delta Lake
- Data Management
|
| Topic 4: Data Modeling and Storage | 20% | - Data Modeling
- Storage Optimization
- File Formats
|
| Topic 5: Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
>> Reliable Databricks-Certified-Data-Engineer-Professional Test Questions <<
New Databricks-Certified-Data-Engineer-Professional Test Topics | Databricks-Certified-Data-Engineer-Professional Free Updates
TestBraindump Databricks Databricks-Certified-Data-Engineer-Professional practice test software is the answer if you want to score higher in the Databricks Databricks-Certified-Data-Engineer-Professional exam and achieve your academic goals. Don't let the Databricks-Certified-Data-Engineer-Professional certification exam stress you out! Prepare with our Databricks-Certified-Data-Engineer-Professional exam dumps and boost your confidence in the Databricks Certified Data Engineer Professional Exam exam. We guarantee your road toward success by helping you prepare for the Databricks-Certified-Data-Engineer-Professional Certification Exam. Use the best TestBraindump Databricks Databricks-Certified-Data-Engineer-Professional practice questions to pass your Databricks-Certified-Data-Engineer-Professional exam with flying colors!
Databricks Certified Data Engineer Professional Exam Sample Questions (Q198-Q203):
NEW QUESTION # 198
A facilities-monitoring team is building a near-real-time PowerBI dashboard off the Delta table device_readings:
Columns:
device_id (STRING, unique sensor ID)
event_ts (TIMESTAMP, ingestion timestamp UTC)
temperature_c (DOUBLE, temperature in °C)
Requirement:
For each sensor, generate one row per non-overlapping 5-minute
interval, offset by 2 minutes (e.g., 00:02-00:07, 00:07-00:12, ...).
Each row must include interval start, interval end, and average
temperature in that slice.
Downstream BI tools (e.g., Power BI) must use the interval timestamps
to plot time-series bars.
- A. SELECT device_id,
window.start AS bucket_start,
window.end AS bucket_end,
AVG(temperature_c) AS avg_temp_5m
FROM device_readings
GROUP BY device_id, window(event_ts, '5 minutes', '5 minutes', '2 minutes') ORDER BY device_id, bucket_start; - B. WITH buckets AS (
SELECT device_id,
window(event_ts, '5 minutes', '2 minutes', '5 minutes') AS win,
temperature_c
FROM device_readings
)
SELECT device_id,
win.start AS bucket_start,
win.end AS bucket_end,
AVG(temperature_c) AS avg_temp_5m
FROM buckets
GROUP BY device_id, win
ORDER BY device_id, bucket_start; - C. SELECT device_id,
event_ts,
AVG(temperature_c) OVER (
PARTITION BY device_id
ORDER BY event_ts
RANGE BETWEEN INTERVAL 5 MINUTES PRECEDING AND CURRENT ROW
) AS avg_temp_5m
FROM device_readings
WINDOW w AS (window(event_ts, '5 minutes', '2 minutes')); - D. SELECT device_id,
date_trunc('minute', event_ts - INTERVAL 2 MINUTES) + INTERVAL 2 MINUTES AS bucket_start, date_trunc('minute', event_ts - INTERVAL 2 MINUTES) + INTERVAL 7 MINUTES AS bucket_end, AVG(temperature_c) AS avg_temp_5m FROM device_readings GROUP BY device_id, date_trunc('minute', event_ts - INTERVAL 2 MINUTES) ORDER BY device_id, bucket_start;
Answer: B
Explanation:
The correct way to satisfy non-overlapping windows with an offset in Databricks SQL is to use the window function with three parameters: window duration, slide duration, and start offset.
In option A, the function call:
window(event_ts, '5 minutes', '2 minutes', '5 minutes')
creates 5-minute windows that slide every 5 minutes, with a 2-minute offset, which exactly matches the requirement (intervals like 00:02?0:07, 00:07?0:12, ...).
NEW QUESTION # 199
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table")
\
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
- A. The filter condition involves a data type excluded from data skipping support.
- B. The Delta table lacks optimization that enables dynamic file pruning.
- C. The filter is executed only after the full data scan, preventing data skipping.
- D. The event_date column is outside the table's partitioning and Z-ordering scheme.
Answer: D
Explanation:
Delta Lake's data skipping relies on partitioning and clustering (such as Z-ordering) on the filtered columns. If event_date is neither a partition column nor included in the table's clustering strategy, Spark must scan most files because file-level statistics cannot be effectively used to prune irrelevant data.
NEW QUESTION # 200
Which method can be used to determine the total wall-clock time it took to execute a query?
- A. Open the Query Profiler associated with that query and use the Total wall-clock duration metric.
- B. Open the Query Profiler associated with that query and use the Aggregated task time metric.
- C. In the Spark UI, take the sum of all task durations that ran across all stages for all jobs associated with that query.
- D. In the Spark UI, take the job duration of the longest-running job associated with that query.
Answer: A
Explanation:
The Query Profiler in Databricks SQL and notebooks provides a detailed breakdown of query performance metrics. The "Total wall-clock duration" metric directly represents the total elapsed time from query start to completion, including all execution, planning, and waiting stages. In contrast, "Aggregated task time" reflects the cumulative duration across all parallel tasks, which does not equal the total elapsed wall time since tasks often run concurrently. Using job duration from Spark UI can underestimate or overestimate runtime when queries span multiple jobs.
Therefore, the Query Profiler's total wall-clock duration is the officially documented method to determine actual query execution time.
NEW QUESTION # 201
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
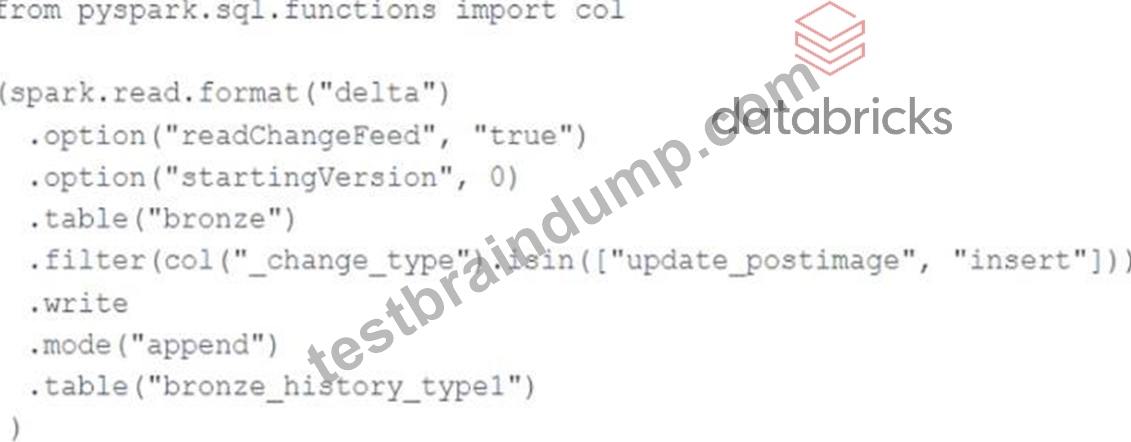
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- B. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- C. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- D. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- E. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
Answer: C
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 202
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- B. Use apply_changes without CDF and filter rows where _soft_deleted is true.
- C. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- D. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
Answer: D
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 203
......
TestBraindump provides an opportunity for fulfilling your career goals and significantly ease your way to become Databricks-Certified-Data-Engineer-Professional Certified professional. While you are going attend your Databricks-Certified-Data-Engineer-Professional exam, in advance knowledge assessment skips your worries regarding actual exam format. Groom up your technical skills with TestBraindump practice test training that has no substitute at all. Get the best possible training through TestBraindump; our practice tests particularly focus the key contents of Databricks-Certified-Data-Engineer-Professional Certification exams. TestBraindump leads the Databricks-Certified-Data-Engineer-Professional exam candidates towards perfection while enabling them to earn the Databricks-Certified-Data-Engineer-Professional credentials at the very first attempt. The way our products induce practical learning approach, there is no close alternative.
New Databricks-Certified-Data-Engineer-Professional Test Topics: https://www.testbraindump.com/Databricks-Certified-Data-Engineer-Professional-exam-prep.html
- Databricks Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Marvelous Reliable Test Questions 🔭 Open ➤ www.easy4engine.com ⮘ enter ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and obtain a free download 🚢Databricks-Certified-Data-Engineer-Professional Study Demo
- Marvelous Reliable Databricks-Certified-Data-Engineer-Professional Test Questions - Pass Databricks-Certified-Data-Engineer-Professional Exam 🚤 The page for free download of 《 Databricks-Certified-Data-Engineer-Professional 》 on ➽ www.pdfvce.com 🢪 will open immediately 🚎Reliable Databricks-Certified-Data-Engineer-Professional Exam Practice
- Databricks-Certified-Data-Engineer-Professional Valid Vce Dumps 🐼 Test Databricks-Certified-Data-Engineer-Professional Pdf 🎠 New Databricks-Certified-Data-Engineer-Professional Test Practice 🌻 Go to website ⇛ www.practicevce.com ⇚ open and search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ to download for free 🩸Simulated Databricks-Certified-Data-Engineer-Professional Test
- Web-based Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam Software - Solution for Online Self-Assessment 🍏 The page for free download of ▛ Databricks-Certified-Data-Engineer-Professional ▟ on ▷ www.pdfvce.com ◁ will open immediately 🥵Test Databricks-Certified-Data-Engineer-Professional Pdf
- Free Databricks-Certified-Data-Engineer-Professional Download Pdf - Databricks-Certified-Data-Engineer-Professional Lab Questions - Databricks-Certified-Data-Engineer-Professional Exam Practice 🆔 Go to website 【 www.torrentvce.com 】 open and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to download for free ⛽Questions Databricks-Certified-Data-Engineer-Professional Exam
- Free Databricks-Certified-Data-Engineer-Professional Download Pdf - Databricks-Certified-Data-Engineer-Professional Lab Questions - Databricks-Certified-Data-Engineer-Professional Exam Practice 🔴 Simply search for “ Databricks-Certified-Data-Engineer-Professional ” for free download on ▷ www.pdfvce.com ◁ 🏁Databricks-Certified-Data-Engineer-Professional Valid Exam Practice
- Databricks-Certified-Data-Engineer-Professional Valid Exam Practice 🐀 Databricks-Certified-Data-Engineer-Professional Valid Test Book ➕ Databricks-Certified-Data-Engineer-Professional Exam Discount 🥨 Search for “ Databricks-Certified-Data-Engineer-Professional ” and download exam materials for free through ➡ www.torrentvce.com ️⬅️ 🧥Databricks-Certified-Data-Engineer-Professional Latest Braindumps Ppt
- Databricks-Certified-Data-Engineer-Professional Latest Braindumps Ppt ‼ Databricks-Certified-Data-Engineer-Professional Latest Learning Material 💔 Databricks-Certified-Data-Engineer-Professional Valid Exam Practice 🤧 The page for free download of ➥ Databricks-Certified-Data-Engineer-Professional 🡄 on ✔ www.pdfvce.com ️✔️ will open immediately 🕟Databricks-Certified-Data-Engineer-Professional Valid Test Book
- Databricks-Certified-Data-Engineer-Professional Reliable Dumps Ppt 🐮 Databricks-Certified-Data-Engineer-Professional Exam Paper Pdf ↖ Simulated Databricks-Certified-Data-Engineer-Professional Test 🐴 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and obtain a free download on ➽ www.pass4test.com 🢪 👊Databricks-Certified-Data-Engineer-Professional Reliable Practice Materials
- Databricks Databricks-Certified-Data-Engineer-Professional Exam | Reliable Databricks-Certified-Data-Engineer-Professional Test Questions - Money Back Guaranteed of New Databricks-Certified-Data-Engineer-Professional Test Topics 🛃 Search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ and obtain a free download on ▛ www.pdfvce.com ▟ 🐺Databricks-Certified-Data-Engineer-Professional Latest Learning Material
- Web-based Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam Software - Solution for Online Self-Assessment 🌟 Open website ▷ www.verifieddumps.com ◁ and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download 🕞New Databricks-Certified-Data-Engineer-Professional Test Practice
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes