2026 Latest ExamsLabs AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1OgMxKD81fEXw94s5XQzzgjM8_Z-vUABD
Having more competitive advantage means that you will have more opportunities and have a job that will satisfy you. This is why more and more people have long been eager for the certification of AI-300. Our AI-300 test material can help you focus and learn effectively. You don't have to worry about not having a dedicated time to learn every day. You can learn our AI-300 exam torrent in a piecemeal time, and you don't have to worry about the tedious and cumbersome learning content. We will simplify the complex concepts by adding diagrams and examples during your study. By choosing our AI-300 test material, you will be able to use time more effectively than others and have the content of important information in the shortest time.
| Section | Objectives |
|---|---|
| Topic 1: Operationalizing machine learning solutions | - Deployment and monitoring
|
| Topic 2: Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Topic 3: Design and implement generative AI solutions | - Large language model integration
|
| Topic 4: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
In order to facilitate the user's offline reading, the AI-300 study braindumps can better use the time of debris to learn, especially to develop PDF mode for users. In this mode, users can know the AI-300 prep guide inside the learning materials to download and print, easy to take notes on the paper, and weak link of their memory, and every user can be downloaded unlimited number of learning, greatly improve the efficiency of the users with our AI-300 Exam Questions. Our AI-300 prep guide can be very good to meet user demand in this respect, allow the user to read and write in a good environment continuously consolidate what they learned.
NEW QUESTION # 96
A data science team trains a model that depends on features that are stored in a managed feature store.
The model is registered in Azure Machine Learning and will be deployed to a real-time endpoint.
After deployment, the model must:
* Retrieve feature values dynamically at inference time.
* Use the same feature definitions that were used during training.
* Run without manual configuration changes across environments.
You need to define feature store entities so that feature retrieval behaves as expected when the model is deployed.
Which feature store entity should you select for each requirement? To answer, move the appropriate feature store entities to the correct requirements. You may use each feature store entity once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.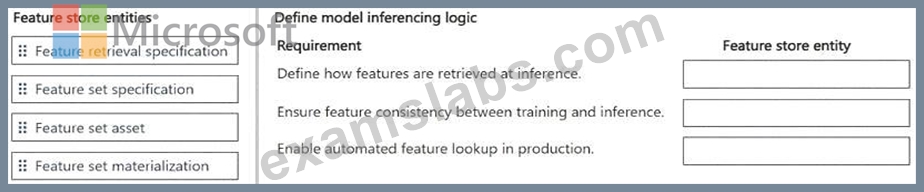
Answer:
Explanation: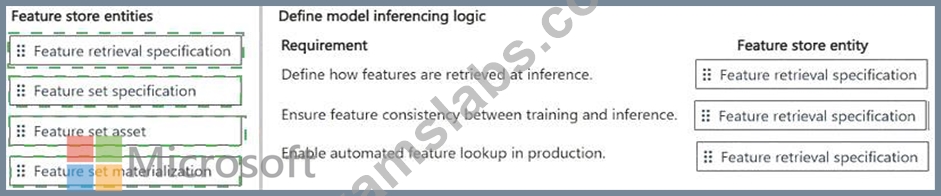
Explanation:
Define how features are retrieved at inference: Feature retrieval specification Ensure feature consistency between training and inference: Feature retrieval specification Enable automated feature lookup in production: Feature retrieval specification The feature retrieval specification is the key model-level contract for all three requirements. Microsoft defines it as a portable specification containing the exact list of features associated with a model, including the relevant feature store, feature set, and feature-set version . The same specification participates in both training and inference, making it the connective artifact across the model lifecycle.
During training, the feature retrieval specification is used to obtain the required feature values and generate training data. Microsoft requires the specification to be packaged with the model artifact when the model depends on feature-store features. At online inference time, the scoring script loads this packaged specification, resolves the feature list, and initializes online feature lookup before calling the feature store to retrieve current values.
This also prevents training-serving inconsistencies because the deployed model carries the feature dependencies and specific feature-set versions established during training, rather than relying on manually reconstructed production configuration. Microsoft explicitly states that packaging the retrieval specification with the model minimizes changes between training and inference workflows.
A feature set specification defines feature sources and transformations, a feature set asset provides managed versioning, and materialization precomputes feature values. None of those alone defines the model ' s complete retrieval contract at inference.
Study Guide Reference: Implement machine learning model lifecycle and operations - package a feature retrieval specification with the model artifact and operationalize feature-store-backed models.
NEW QUESTION # 97
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: B,C
Explanation:
Microsoft ' s RAG optimization guidance identifies two high-impact, low-cost improvements for retrieval quality that do not require changing the embedding model. First, tuning chunk size and overlap (option A):
chunk size determines how much context each retrieved piece contains - too large and irrelevant content dilutes the signal; too small and answers may be split across chunks. Adjusting these parameters requires only re-indexing the documents with zero additional compute cost. Second, implementing a re-ranker (option B): a re-ranker is a cross-encoder model that takes the top-N retrieved chunks and re-scores them based on their specific relevance to the query, significantly improving precision by filtering out contextually irrelevant chunks. Re-rankers add modest compute cost but are far cheaper than changing the embedding model, which would require re-embedding the entire knowledge base. Increasing token limits (option C) and optimizing embedding vector length (option D) do not address retrieval accuracy without an embedding model change.
Microsoft Learn Reference Topic: Optimize RAG pipelines - Chunk size tuning and re-ranking in Azure AI Search and Azure Machine Learning
NEW QUESTION # 98
You manage an Azure Machine Learning workspace by using the Azure CLI ml extension v2. You need to define a YAML schema to create a compute cluster. Which schema should you use?
Answer: D
NEW QUESTION # 99
You create a binary classification model. You use the Fairlearn package to assess model fairness.
You must eliminate the need to retrain the model.
You need to implement the Fairlearn package.
Which algorithm should you use?
Answer: A
NEW QUESTION # 100
Drag and Drop Question
A company plans to deploy a foundation model in Microsoft Foundry.
The mode must support the following workloads:
- A customer support workload used across multiple regions
- A marketing workload that must remain within a specific region due to data residency requirements You need to select the deployment type.
Which deployment type should you use for each workload? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.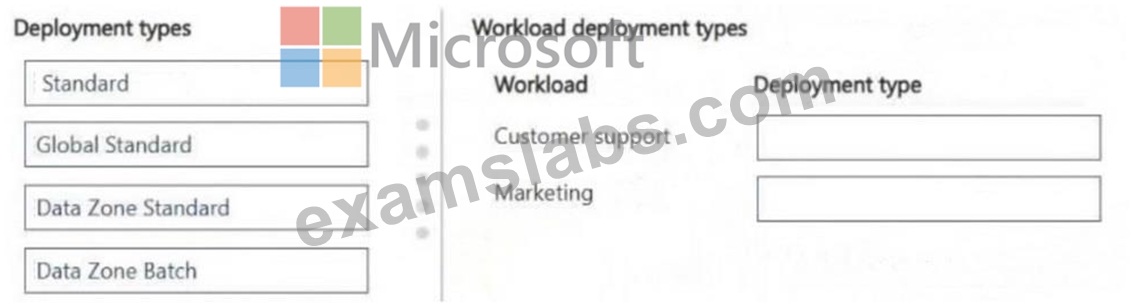
Answer:
Explanation: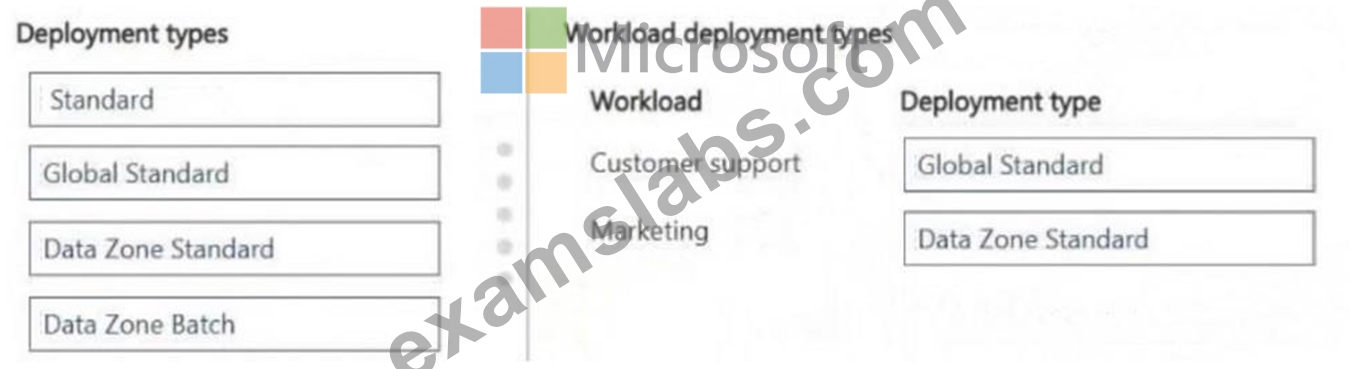
NEW QUESTION # 101
......
There are many merits of our product on many aspects and we can guarantee the quality of our AI-300 practice engine. Firstly, our experienced expert team compile them elaborately based on the real exam and our AI-300 study materials can reflect the popular trend in the industry and the latest change in the theory and the practice. Secondly, both the language and the content of our AI-300 Study Materials are simple,easy to be understood and suitable for any learners.
AI-300 Exam Prep: https://www.examslabs.com/Microsoft/Microsoft-Certified/best-AI-300-exam-dumps.html
BTW, DOWNLOAD part of ExamsLabs AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1OgMxKD81fEXw94s5XQzzgjM8_Z-vUABD