We stand behind all of our customers, so we provide you with the best valid and useful Databricks Databricks-Certified-Professional-Data-Engineer exam training. Regular and frequent updates for Databricks-Certified-Professional-Data-Engineer dumps are necessary, so you can get hold of the Databricks-Certified-Professional-Data-Engineer updated exam material every time. Besides, we offer the exact questions with correct answers, which can ensure you 100% pass in your Databricks Databricks-Certified-Professional-Data-Engineer Actual Test. We have 100% money back guarantee, in case of failure, we will give you full refund.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
>> Current Databricks-Certified-Professional-Data-Engineer Exam Content <<
Our web backend is strong for our Databricks-Certified-Professional-Data-Engineer study braindumps. No matter how many people are browsing our websites at the same time, you still can quickly choose your favorite Databricks-Certified-Professional-Data-Engineer exam questions and quickly pay for it. There has no delay reaction of our website. So you can begin your pleasant selecting journey on our websites. And you will find our Databricks-Certified-Professional-Data-Engineer practice materials are easy to download.
NEW QUESTION # 105
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in thegeo_lookuptable.
Before executing the code, runningSHOWTABLESon the current database indicates the database contains only two tables:geo_lookupandsales.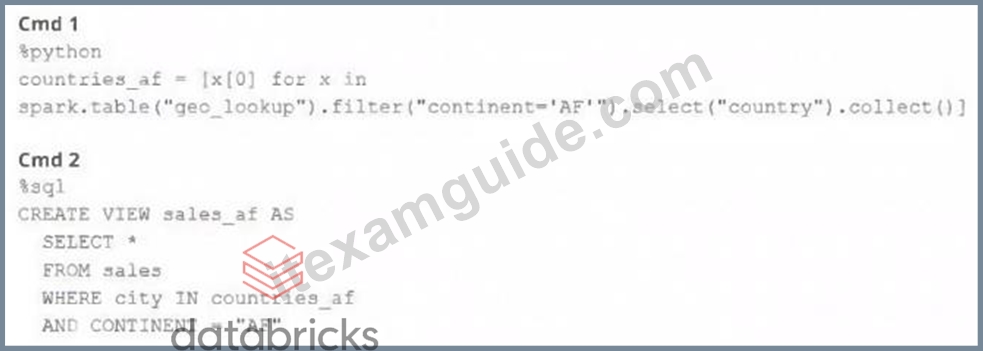
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Answer: D
Explanation:
Explanation
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variableas a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
NEW QUESTION # 106
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors' group can view the job but not modify/run it.
* Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
Answer: B
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
NEW QUESTION # 107
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.
address THEN
UPDATE SET current = false, end_date = staged_updates.effective_date
WHEN NOT MATCHED THEN
INSERT (customer_id, address, current, effective_date, end_date)
VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
* The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
Answer: A
Explanation:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context.
In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.
Databricks documentation on implementing SCDs using Delta Lake and the MERGE statement (https://docs.databricks.com/delta/delta-update.html#upsert-into-a-table-using-merge).
NEW QUESTION # 108
Which statement describes Delta Lake optimized writes?
Answer: B
Explanation:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table. The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
References:
* Databricks documentation on Delta Lake performance tuning:
https://docs.databricks.com/delta/optimizations/auto-optimize.html
NEW QUESTION # 109
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.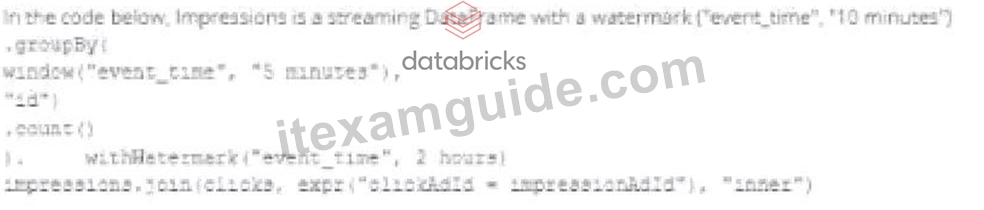
Which solution would improve the performance?




Answer: B
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 110
......
Our most wanted version of the DatabricksExam Questions is our PDF eBook, and it is convenient even students can easily use it. Databricks Databricks-Certified-Professional-Data-Engineer pdf questions are printable and portable features make it more convenient the use. You can prepare with Databricks-Certified-Professional-Data-Engineer pdf questions and answers anywhere and anytime. This is the most reliable source of preparation. Our Databricks Databricks-Certified-Professional-Data-Engineer desktop-based practice software is the most helpful version to prepare for Databricks Certified Professional Data Engineer Exam exam as it simulates the real DatabricksCertified Network Professional Data Center certification exam according to the Databricksrules.
Reliable Databricks-Certified-Professional-Data-Engineer Exam Price: https://www.itexamguide.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html