BTW, DOWNLOAD part of PDFTorrent Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1WSxWXWzCC--jWEiiNYAetdBsqiNez7qp
Databricks Databricks-Generative-AI-Engineer-Associate practice questions are based on recently released Databricks Databricks-Generative-AI-Engineer-Associate exam objectives. Includes a user-friendly interface allowing you to take the Databricks Databricks-Generative-AI-Engineer-Associate Practice Exam on your computers, like downloading the PDF, Web-Based Databricks Databricks-Generative-AI-Engineer-Associate practice test software, and Desktop Databricks Databricks-Generative-AI-Engineer-Associate practice exam software.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Questions <<
We have hired professional staff to maintain Databricks-Generative-AI-Engineer-Associate practice engine and our team of experts also constantly updates and renew the question bank according to changes in the syllabus. With Databricks-Generative-AI-Engineer-Associate learning materials, you can study at ease, and we will help you solve all the problems that you may encounter in the learning process. If you have any confusion about our Databricks-Generative-AI-Engineer-Associate Exam Questions, just contact us and we will help you out.
NEW QUESTION # 33
A Generative Al Engineer is building a production-ready LLM system which replies directly to customers. The solution makes use of the Foundation Model API via provisioned throughput. They are concerned that the LLM could potentially respond in a toxic or otherwise unsafe way. They also wish to perform this with the least amount of effort.
Which approach will do this?
Answer: A
Explanation:
The task is to prevent toxic or unsafe responses in an LLM system using the Foundation Model API with minimal effort. Let's assess the options.
Option A: Host Llama Guard on Foundation Model API and use it to detect unsafe responses Llama Guard is a safety-focused model designed to detect toxic or unsafe content. Hosting it via the Foundation Model API (a Databricks service) integrates seamlessly with the existing system, requiring minimal setup (just deployment and a check step), and leverages provisioned throughput for performance.
Databricks Reference: "Foundation Model API supports hosting safety models like Llama Guard to filter outputs efficiently" ("Foundation Model API Documentation," 2023).
Option B: Add some LLM calls to their chain to detect unsafe content before returning text Using additional LLM calls (e.g., prompting an LLM to classify toxicity) increases latency, complexity, and effort (crafting prompts, chaining logic), and lacks the specificity of a dedicated safety model.
Databricks Reference: "Ad-hoc LLM checks are less efficient than purpose-built safety solutions" ("Building LLM Applications with Databricks").
Option C: Add a regex expression on inputs and outputs to detect unsafe responses Regex can catch simple patterns (e.g., profanity) but fails for nuanced toxicity (e.g., sarcasm, context-dependent harm), requiring significant manual effort to maintain and update rules.
Databricks Reference: "Regex-based filtering is limited for complex safety needs" ("Generative AI Cookbook").
Option D: Ask users to report unsafe responses
User reporting is reactive, not preventive, and places burden on users rather than the system. It doesn't limit unsafe outputs proactively and requires additional effort for feedback handling.
Databricks Reference: "Proactive guardrails are preferred over user-driven monitoring" ("Databricks Generative AI Engineer Guide").
Conclusion: Option A (Llama Guard on Foundation Model API) is the least-effort, most effective approach, leveraging Databricks' infrastructure for seamless safety integration.
NEW QUESTION # 34
A Generative Al Engineer needs to design an LLM pipeline to conduct multi-stage reasoning that leverages external tools. To be effective at this, the LLM will need to plan and adapt actions while performing complex reasoning tasks.
Which approach will do this?
Answer: D
Explanation:
The task requires an LLM pipeline for multi-stage reasoning with external tools, necessitating planning, adaptability, and complex reasoning. Let's evaluate the options based on Databricks' recommendations for advanced LLM workflows.
Option A: Train the LLM to generate a single, comprehensive response without interacting with any external tools, relying solely on its pre-trained knowledge This approach limits the LLM to its static knowledge base, excluding external tools and multi-stage reasoning. It can't adapt or plan actions dynamically, failing the requirements.
Databricks Reference: "External tools enhance LLM capabilities beyond pre-trained knowledge" ("Building LLM Applications with Databricks," 2023).
Option B: Implement a framework like ReAct which allows the LLM to generate reasoning traces and perform task-specific actions that leverage external tools if necessary ReAct (Reasoning + Acting) combines reasoning traces (step-by-step logic) with actions (e.g., tool calls), enabling the LLM to plan, adapt, and execute complex tasks iteratively. This meets all requirements: multi-stage reasoning, tool use, and adaptability.
Databricks Reference: "Frameworks like ReAct enable LLMs to interleave reasoning and external tool interactions for complex problem-solving" ("Generative AI Cookbook," 2023).
Option C: Encourage the LLM to make multiple API calls in sequence without planning or structuring the calls, allowing the LLM to decide when and how to use external tools spontaneously Unstructured, spontaneous API calls lack planning and may lead to inefficient or incorrect tool usage. This doesn't ensure effective multi-stage reasoning or adaptability.
Databricks Reference: Structured frameworks are preferred: "Ad-hoc tool calls can reduce reliability in complex tasks" ("Building LLM-Powered Applications").
Option D: Use a Chain-of-Thought (CoT) prompting technique to guide the LLM through a series of reasoning steps, then manually input the results from external tools for the final answer CoT improves reasoning but relies on manual tool interaction, breaking automation and adaptability. It's not a scalable pipeline solution.
Databricks Reference: "Manual intervention is impractical for production LLM pipelines" ("Databricks Generative AI Engineer Guide").
Conclusion: Option B (ReAct) is the best approach, as it integrates reasoning and tool use in a structured, adaptive framework, aligning with Databricks' guidance for complex LLM workflows.
NEW QUESTION # 35
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: A
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval-Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
Ingest documents from a source: This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
Index the documents and save to Vector Search: Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
User submits queries against an LLM: Users interact with the application by submitting their queries. These queries will be passed to the LLM.
LLM retrieves relevant documents: The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
LLM generates a response: Using the retrieved documents, the LLM generates a response that is tailored to the user's question.
Evaluate model: After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
Deploy it using Model Serving: Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 36
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: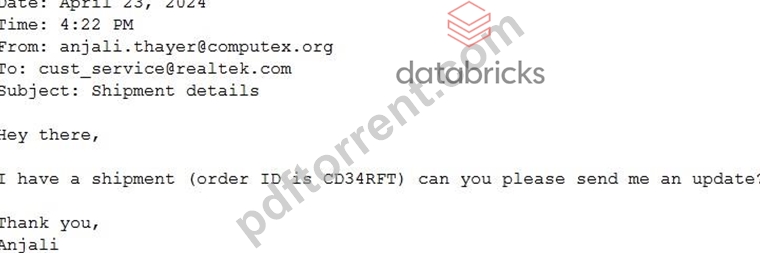
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: C
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 37
A Generative AI Engineer has created a RAG application which can help employees retrieve answers from an internal knowledge base, such as Confluence pages or Google Drive. The prototype application is now working with some positive feedback from internal company testers. Now the Generative Al Engineer wants to formally evaluate the system's performance and understand where to focus their efforts to further improve the system.
How should the Generative AI Engineer evaluate the system?
Answer: C
Explanation:
* Problem Context: After receiving positive feedback for the RAG application prototype, the next step is to formally evaluate the system to pinpoint areas for improvement.
* Explanation of Options:
* Option A: While cosine similarity scores are useful, they primarily measure similarity rather than the overall performance of an RAG system.
* Option B: This option provides a systematic approach to evaluation by testing both retrieval and generation components separately. This allows for targeted improvements and a clear understanding of each component's performance, using MLflow's metrics for a structured and standardized assessment.
* Option C: Benchmarking multiple LLMs does not focus on evaluating the existing system's components but rather on comparing different models.
* Option D: Using an LLM as a judge is subjective and less reliable for systematic performance evaluation.
OptionBis the most comprehensive and structured approach, facilitating precise evaluations and improvements on specific components of the RAG system.
NEW QUESTION # 38
......
The language in our Databricks Databricks-Generative-AI-Engineer-Associate test guide is easy to understand that will make any learner without any learning disabilities, whether you are a student or a in-service staff, whether you are a novice or an experienced staff who has abundant experience for many years. It should be a great wonderful idea to choose our Databricks-Generative-AI-Engineer-Associate Guide Torrent for sailing through the difficult test.
Databricks-Generative-AI-Engineer-Associate Latest Mock Test: https://www.pdftorrent.com/Databricks-Generative-AI-Engineer-Associate-exam-prep-dumps.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PDFTorrent: https://drive.google.com/open?id=1WSxWXWzCC--jWEiiNYAetdBsqiNez7qp