P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1C9EO9roP6oCFMIuoehTiPrOem5HaIb4_
It is because of our high quality DP-750 preparation software, PDF files and other relevant products, we have gathered more than 50,000 customers who have successfully passed the Microsoft DP-750 in one go. You can also attain the same success rate by using our high standard DP-750 Preparation products. Thousands of satisfied customers can't be wrong. You must try our products to believe this fact.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
>> DP-750 Latest Braindumps Book <<
Being different from the other DP-750 Exam Questions in the market, our DP-750 practice materials have reasonable ruling price and satisfactory results of passing rate up to 98 to 100 percent. So our DP-750 guide prep is perfect paragon in this industry full of elucidating content for exam candidates of various degrees to use for reference. It contains not only the newest questions appeared in real exams in these years, but the most classic knowledge to master.
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: D
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 42
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.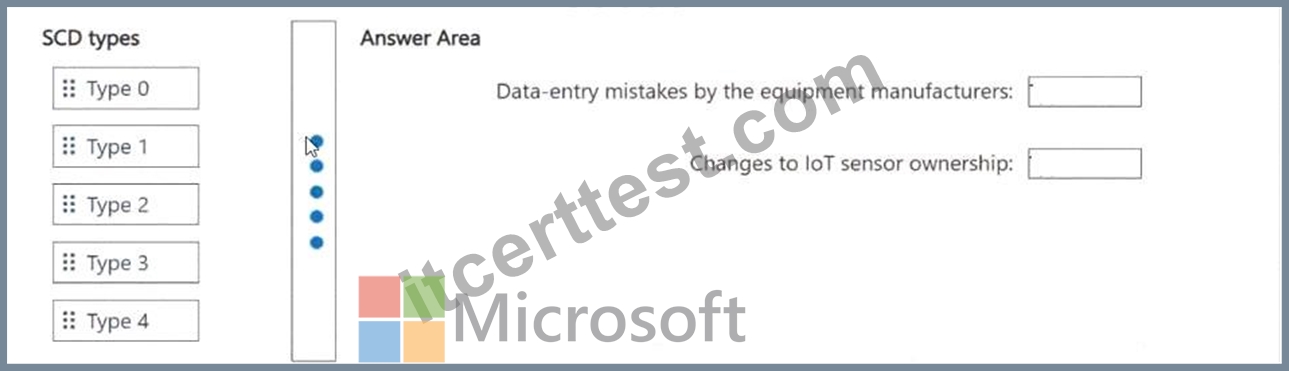
Answer:
Explanation: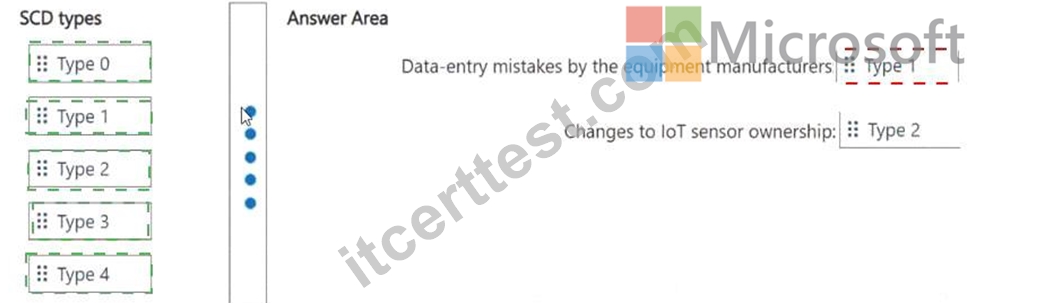
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
NEW QUESTION # 43
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
Answer: C
Explanation:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
NEW QUESTION # 44
Which layer contains cleaned and conformed data in Databricks Lakehouse architecture?
Answer: D
Explanation:
Silver layer contains cleaned, validated, and enriched data ready for analytics. Bronze stores raw ingested data. Gold contains aggregated business-level data. Raw is not part of formal medallion architecture naming.
NEW QUESTION # 45
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: A
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 46
......
our company is determined to help provide the most accurate DP-750 Exam Questions and help more people get the DP-750 certificate successfully. Our company has a long history of 10 years in designing DP-750 study materials and enjoys a good reputation across the globe. Now we can be the leader in this exam field and have a large number of regular customers from different countries. We are looking forward to your joining in us.
Study DP-750 Demo: https://www.itcerttest.com/DP-750_braindumps.html
What's more, part of that Itcerttest DP-750 dumps now are free: https://drive.google.com/open?id=1C9EO9roP6oCFMIuoehTiPrOem5HaIb4_