SPS-C01 Latest Exam Discount & SPS-C01 Latest Test Fee

P.S. Free & New SPS-C01 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1SRSoRAqlp040bRPTmGzgD2j9-ev0x1df
ITdumpsfree is admired by all our customers for our experts' familiarity and dedication with the industry all these years. By their help, you can qualify yourself with high-quality SPS-C01 exam materials. Our experts pass onto the exam candidate their know-how of coping with the SPS-C01 Exam by our SPS-C01 practice questions. Exam candidates are susceptible to the influence of ads, so our experts' know-how is impressive to pass the SPS-C01 exam instead of making financial reward solely.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
- Python API fundamentals
- 1. Data persistence and writing results
- 2. Column operations and functions
- 3. DataFrame creation from tables, views, SQL
|
| Topic 2: Data Transformations and Operations | 35% | - Advanced operations
- 1. Semi-structured data processing
- 2. Window functions and analytics
- 3. Pivot and unpivot transformations
- DataFrame manipulation
- 1. Joins, unions, set operations
- 2. Selection, projection, renaming, casting
- 3. Filtering, sorting, grouping, aggregation
- User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
- Optimization techniques
- 1. Query pushdown and execution plans
- 2. Caching and warehouse sizing
- 3. Minimizing data movement
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Transformations vs actions
- 2. Lazy evaluation and DAG execution
- 3. Client-side vs server-side processing
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
>> SPS-C01 Latest Exam Discount <<
Quiz 2026 SPS-C01: Perfect Snowflake Certified SnowPro Specialty - Snowpark Latest Exam Discount
Do you want to pass your exam just one time? Then choose us, we can do that for you. SPS-C01 exam cram contains both questions and answers, and you can have a quick check after practicing. SPS-C01 exam materials are high-quality, because we have professional team to compile and verify them. In order to build up your confidence for SPS-C01 Training Materials, we are pass guarantee and money back guarantee, and if you fail to pass the exam, we will give you fell refund. We provide you with free update for 365 days, so that you can know the latest information for the exam, and the update version for SPS-C01 exam dumps will be sent to your email automatically.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q271-Q276):
NEW QUESTION # 271
You are setting up a development environment for Snowpark using Anaconda and encounter the following error: 'ModuleNotFoundError: No module named 'snowflake.snowpark". You have already installed the package using pip. What is the MOST likely cause of this error and how do you resolve it?
- A. The 'snowflake-snowpark-python' package was installed in a different Anaconda environment than the one you are currently using. Ensure you are in the correct environment when running your Snowpark code.
- B. The 'snowflake-snowpark-python' package is not compatible with the version of Python installed in your Anaconda environment. Upgrade Python to the latest version.
- C. The Snowflake account identifier is not properly configured in your environment variables. Verify that 'SNOWFLAKE ACCOUNT is correctly set.
- D. The Snowflake driver is not installed. Install the Snowflake driver using 'pip install snowflake-connector-python'
- E. The Anaconda environment is not activated. Activate the environment using 'conda activate
Answer: A,E
Explanation:
The most common reasons for 'ModuleNotFoundErroff are that the Anaconda environment is not activated (B), meaning the Python interpreter doesn't know where to find the installed packages, or the package was installed in a different environment (D) than the one being used. While Python version compatibility (A) and Snowflake driver (C) can cause issues, they usually manifest as different errors. A misconfigured account identifier (E) would prevent a connection to Snowflake, but wouldn't directly cause a 'ModuleNotFoundError' for the Snowpark library itself.
NEW QUESTION # 272
You have a Snowflake table named 'RAW EVENTS with a large number of events data, containing columns like 'EVENT ID', 'TIMESTAMP, 'USER ID, and 'EVENT_TYPE. The 'EVENT TYPE column contains string values representing different event categories. You want to create a Snowpark DataFrame, but due to the table's size, you only want to sample a small portion of the data for initial exploration and testing. Which of the following code snippets MOST accurately and efficiently creates a sampled Snowpark DataFrame named 'sampled_df containing approximately 1% of the rows from the 'RAW EVENTS table?
Answer: E
Explanation:
Explanation:Option A provides the MOST accurate and efficient way to sample 1% of the data using , seed-42)'. The 'frae parameter directly specifies the fraction of rows to sample. 'seed' ensures consistent sampling across multiple runs. Option B is inefficient because it calculates the total count of rows before limiting, which scans the entire table. Option C, uses 'randomSplit' , but it splits the data into two new dataframes. Option D, utilizes Snowflake's SQL sampling feature via 'session.sqr , is a valid alternative, but less idiomatic when using Snowpark API directly. Option E, the parameter 'n' is deprecated and has been removed. 'sample' requires 'frae parameter.
NEW QUESTION # 273
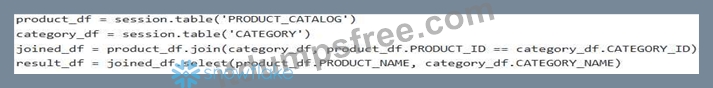
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: E
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 274
You've developed a Snowpark Python UDTF that performs complex data transformation. This UDTF needs to be operationalized within a data pipeline. You want to ensure high performance and scalability. Which of the following strategies will be MOST effective in operationalizing this UDTF?
- A. Register the UDTF as a permanent function without any resource allocation and depend on snowflake auto scaling.
- B. Run the UDTF sequentially on a small dataset to minimize resource consumption.
- C. Deploy the UDTF as an external function hosted on a cloud provider without any resource constraints.
- D. Register the UDTF as a temporary function within a single Snowpark session for ad-hoc analysis.
- E. Register the UDTF as a permanent function with appropriate resource allocation (warehouse size) and utilize vectorization techniques within the UDTF's implementation.
Answer: E
Explanation:
Registering the UDTF as a permanent function allows it to be reused across multiple sessions and data pipelines. Appropriate resource allocation, such as selecting an appropriate warehouse size, ensures sufficient compute resources for the UDTF's execution. Vectorization within the UDTF implementation can significantly improve performance by processing data in batches. External functions introduce additional complexity and potential latency. Temporary functions are not suitable for operationalization. Option D is incorrect because it negates the benefits of Snowpark's scalability. Option E is incorrect because proper resource sizing is necessary.
NEW QUESTION # 275
You are working with Snowpark DataFrames representing sales transactions. The 'transactions df DataFrame contains recent transactions, while the 'sales_table' in Snowflake holds the historical sales data'. You need to merge the new transactions into the 'sales table', but you want to track which rows were inserted, updated, or left unchanged by the 'merge' operation. How can you capture this information using Snowpark and persist it to a separate table?
- A. The merge operation automatically creates a system table or view that logs the details of each row that was inserted, updated, or left unchanged.
- B. After the merge, query the 'sales_table' and compare it to a copy of the 'sales_table' taken before the merge. Identify inserted rows as those present in the new version but not in the old, and updated rows as those with different values in specific columns between the two versions. This strategy should be implemented with the help of external functions and UDFs, as it is an expensive operation and should not be computed with normal SQL.
- C. You can use the 'returning' clause within the merge statement to retrieve the impacted rows and their change status (INSERTED, UPDATED) and then write this data to a tracking table using 'write.saveAsTable' .
- D. It's not possible to capture the merge operation details (inserted/updated/unchanged rows) directly using Snowpark alone. You would need to implement custom logic outside of Snowpark to compare the data before and after the merge.
- E. You can combine the 'returning' clause along with a stored procedure to retrieve the inserted/updated rows with their status and then use the stored procedure to write to a different tracking table using insert statement.
Answer: C
Explanation:
The 'returning' clause is a powerful feature of the 'merge' statement in Snowflake SQL. It allows you to capture the rows that were affected by the merge operation, along with details about the type of change (INSERTED, UPDATED, DELETED). In Snowpark, you can leverage this by including a 'returning' clause in your 'merge' statement and then use the returned DataFrame to write the data to a tracking table. This provides a direct and efficient way to monitor the impact of your merge operations. Therefore the correct answer is B.
NEW QUESTION # 276
......
We will provide high quality assurance of SPS-C01 exam questions for our customers with dedication to ensure that we can develop a friendly and sustainable relationship. First of all, we have security and safety guarantee, which mean that you cannot be afraid of virus intrusion and information leakage since we have data protection acts, even though you end up studying SPS-C01 test guide of our company, we will absolutely delete your personal information and never against ethic code to sell your message to the third parties. Secondly, our SPS-C01 Exam Questions will spare no effort to perfect after-sales services. Thirdly countless demonstration and customer feedback suggest that our Snowflake Certified SnowPro Specialty - Snowpark study question can help them get the certification as soon as possible, thus becoming the elite, getting a promotion and a raise and so forth.
SPS-C01 Latest Test Fee: https://www.itdumpsfree.com/SPS-C01-exam-passed.html
- SPS-C01 Latest Exam Discount Exam 100% Pass | Snowflake SPS-C01: Snowflake Certified SnowPro Specialty - Snowpark 🔳 Search for ⇛ SPS-C01 ⇚ and download exam materials for free through 「 www.troytecdumps.com 」 🅿SPS-C01 Related Exams
- Excellent Snowflake SPS-C01 Practice Material's 3 formats 🏉 Search for { SPS-C01 } and obtain a free download on ⏩ www.pdfvce.com ⏪ 🦋Reliable SPS-C01 Test Experience
- 2026 100% Free SPS-C01 –Newest 100% Free Latest Exam Discount | Snowflake Certified SnowPro Specialty - Snowpark Latest Test Fee 🌙 Open ➡ www.pdfdumps.com ️⬅️ enter 【 SPS-C01 】 and obtain a free download 🏋SPS-C01 Trustworthy Exam Torrent
- Snowflake Certified SnowPro Specialty - Snowpark practice vce dumps - SPS-C01 latest exam guide - Snowflake Certified SnowPro Specialty - Snowpark test training torrent 🦳 Search for ⏩ SPS-C01 ⏪ and easily obtain a free download on ➥ www.pdfvce.com 🡄 🙆Exam Dumps SPS-C01 Pdf
- New SPS-C01 Exam Price 😩 Passing SPS-C01 Score 🐩 New SPS-C01 Braindumps Ebook 🏌 Search for ➡ SPS-C01 ️⬅️ and obtain a free download on ➠ www.vce4dumps.com 🠰 👆New SPS-C01 Exam Price
- SPS-C01 Online Exam 🔛 Clearer SPS-C01 Explanation 🐡 New SPS-C01 Test Vce 🅰 Open ➤ www.pdfvce.com ⮘ enter 《 SPS-C01 》 and obtain a free download 🦆Test SPS-C01 King
- 2026 Snowflake SPS-C01: High Hit-Rate Snowflake Certified SnowPro Specialty - Snowpark Latest Exam Discount 🚉 Open ➡ www.exam4labs.com ️⬅️ and search for ➡ SPS-C01 ️⬅️ to download exam materials for free 🥓Test SPS-C01 King
- 2026 Snowflake SPS-C01: High Hit-Rate Snowflake Certified SnowPro Specialty - Snowpark Latest Exam Discount 💇 Search for 「 SPS-C01 」 and easily obtain a free download on ➤ www.pdfvce.com ⮘ 👞Latest SPS-C01 Exam Topics
- Reliable SPS-C01 Test Experience 🦘 SPS-C01 Interactive Course ⚠ SPS-C01 Related Exams 🔩 Search for [ SPS-C01 ] on ⏩ www.prepawaypdf.com ⏪ immediately to obtain a free download 🏍Clearer SPS-C01 Explanation
- SPS-C01 Related Exams 📜 SPS-C01 Trustworthy Practice 🦆 Latest SPS-C01 Exam Topics 🍛 Search for ▶ SPS-C01 ◀ and download it for free immediately on 【 www.pdfvce.com 】 🦅SPS-C01 Trustworthy Practice
- SPS-C01 Exam Questions Preparation Material By www.prepawaypdf.com 👜 Download { SPS-C01 } for free by simply searching on ▶ www.prepawaypdf.com ◀ 🦽Reliable SPS-C01 Braindumps Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of ITdumpsfree SPS-C01 dumps for free: https://drive.google.com/open?id=1SRSoRAqlp040bRPTmGzgD2j9-ev0x1df