Research indicates that the success of our highly-praised DP-750 test questions owes to our endless efforts for the easily operated practice system. Most feedback received from our candidates tell the truth that our DP-750 guide torrent implement good practices, systems as well as strengthen our ability to launch newer and more competitive products. Accompanying with our DP-750 exam dumps, we educate our candidates with less complicated Q&A but more essential information, which in a way makes you acquire more knowledge and enhance your self-cultivation. And our DP-750 Exam Dumps also add vivid examples and accurate charts to stimulate those exceptional cases you may be confronted with. You can rely on our DP-750 test questions, and we’ll do the utmost to help you succeed.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
>> Detailed DP-750 Study Dumps <<
By unremitting effort to improve the accuracy and being studious of the DP-750 real questions all these years, our experts remain unpretentious attitude towards our DP-750 practice materials all the time. They are unsuspecting experts who you can count on. Without unintelligible content within our DP-750 study tool, all questions of the exam are based on their professional experience in this industry. Besides, they made three versions for your reference, the PDF, APP and Online software version. They do not let go even the tenuous points about the DP-750 Exam as long as they are helpful and related to the exam. And let go those opaque technicalities which are useless and hard to understand, which means whether you are newbie or experienced exam candidate of this area, you can use our DP-750 real questions with ease.
NEW QUESTION # 87
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: C
Explanation:
The correct answer is C - Enable schema evolution.
When new columns are added to the source data, a pipeline without schema evolution treats the unexpected columns as a schema mismatch and fails the write. Schema evolution, when enabled in an SDP pipeline, automatically adds those new columns to the target Delta table on the next pipeline run. The pipeline continues without intervention, and no historical data is lost.
Option A (disable schema enforcement) is the wrong lever - it removes all schema validation, which could allow corrupt or mistyped data into Table1. Schema evolution is a targeted, safer response.
Option B (row filters to exclude records with new columns) would silently discard valid records just because they carry extra fields - that's data loss. Option D (separate table per schema version) creates an explosion of tables as schemas evolve and makes downstream analytics significantly more complex. Schema evolution is the clean, built-in solution.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/schema-evolution
NEW QUESTION # 88
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: A
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 89
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook 1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.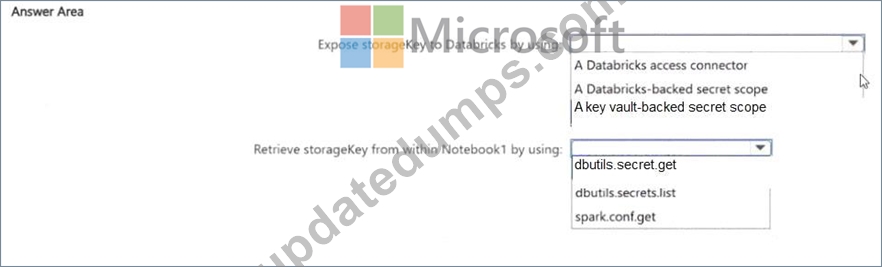
Answer:
Explanation: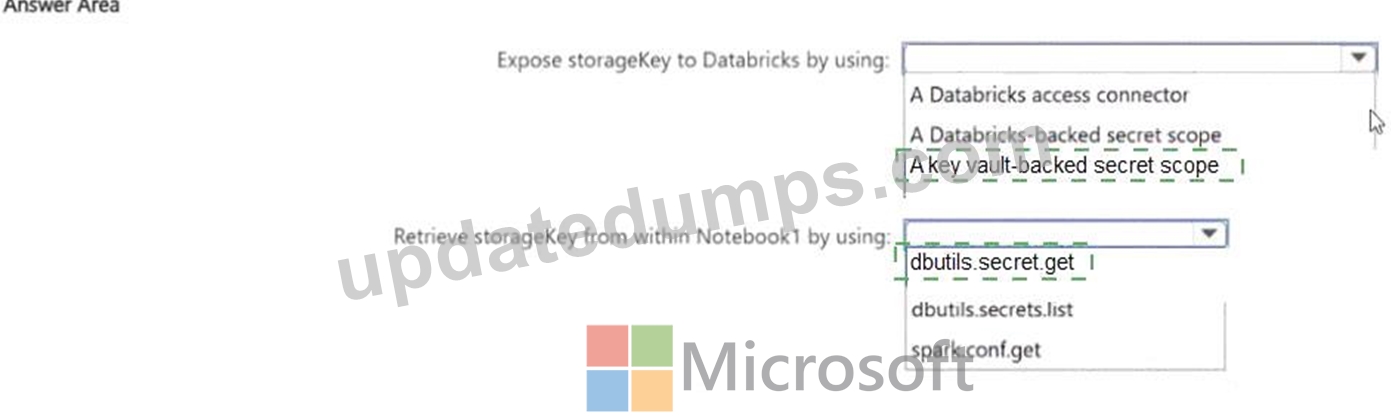
Explanation:
The solution is a Key Vault-backed secret scope combined with dbutils.secrets.get() in the notebook.
An Azure Key Vault-backed secret scope does not copy the secret value into Databricks. Every call to dbutils.
secrets.get() fetches the live current value directly from Key Vault at runtime. This means when the cloud security team rotates storageKey in Key Vault, the notebook automatically picks up the new value on its next run - no Databricks configuration changes needed. That satisfies 'always retrieve the latest value.' The principle of least privilege is upheld because only the secret scope has read access to Key Vault through a service principal or managed identity, and individual users never see the raw secret value - Databricks redacts it in logs automatically.
A Databricks-backed scope stores a copy of the secret inside Databricks, so it wouldn't automatically reflect Key Vault updates. Hardcoding or using environment variables would expose the secret in plain text.
Reference: https://learn.microsoft.com/en-us/azure/databricks/security/secrets/secret-scopes
NEW QUESTION # 90
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
Answer: B
Explanation:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
NEW QUESTION # 91
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: C
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 92
......
Maybe you severely need a proper guide for your DP-750 exam test. Do not seek with aimless any more. Our Microsoft DP-750 exam guide will clear your confusion and help you out the difficulties. We offer the DP-750 original questions with verified answers. Our DP-750 PC test engine benefits you in your actual test. It has been tested and verified malware-free software, which ensure the safety installation. Besides, DP-750 PC test engine possess the characteristic of score comparison and improvement check. The customizable and intelligent DP-750 study material can help you pass your exam at your first attempt.
Reliable DP-750 Exam Questions: https://www.updatedumps.com/Microsoft/DP-750-updated-exam-dumps.html