P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1Jl-2taefbGpdYLDgezBoclm9tDlMLLmC
We believe in most cases our Databricks-Generative-AI-Engineer-Associate exam study materials are truly your best friend. On one hand, our Databricks-Generative-AI-Engineer-Associate learning guide is the combination of the latest knowledge and the newest technology, which could constantly inspire your interest of study. On the other hand, our Databricks-Generative-AI-Engineer-Associate test answers can predicate the exam correctly. Through highly effective learning method and easily understanding explanation, you will pass the Databricks-Generative-AI-Engineer-Associate Exam with no difficulty. Our slogans are genuinely engraving on our mind that is to help you pass the Databricks-Generative-AI-Engineer-Associate exam, and ride on the crest of success!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Databricks-Generative-AI-Engineer-Associate Latest Test Labs <<
In this version, you don't need an active internet connection to use the Databricks-Generative-AI-Engineer-Associate practice test software. This software mimics the style of real test so that users find out pattern of the real test and kill the exam anxiety. DumpExam offline practice exam is customizable and users can change questions and duration of Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) mock tests.
NEW QUESTION # 56
A Generative AI Engineer I using the code below to test setting up a vector store: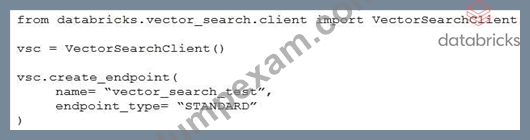
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 57
Which indicator should be considered to evaluate the safety of the LLM outputs when qualitatively assessing LLM responses for a translation use case?
Answer: D
Explanation:
* Problem Context: When assessing the safety and effectiveness of LLM outputs in a translation use case, it is essential to ensure that the translations accurately and relevantly convey the intended message. The evaluation should focus on how well the LLM understands and processes different languages and contexts.
* Explanation of Options:
* Option A: The ability to generate responses in code- This is not relevant to translation quality or safety.
* Option B: The similarity to the previous language- While ensuring that translations preserve the original's intent is important, this doesn't directly address the overall quality or safety of the translation.
* Option C: The latency of the response and the length of text generated- These operational metrics are less critical in assessing the qualitative aspects of translation safety.
* Option D: The accuracy and relevance of the responses- This is crucial in translation to ensure that the translated content is true to the original in meaning and appropriateness. Accuracy and relevance directly impact the effectiveness and safety of translations, especially in sensitive or nuanced contexts.
Thus,Option Dis the most important indicator when evaluating the safety of LLM outputs in translation, focusing on the core aspects that determine the utility and trustworthiness of translated content.
NEW QUESTION # 58
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: C
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval-Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
Ingest documents from a source: This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
Index the documents and save to Vector Search: Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
User submits queries against an LLM: Users interact with the application by submitting their queries. These queries will be passed to the LLM.
LLM retrieves relevant documents: The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
LLM generates a response: Using the retrieved documents, the LLM generates a response that is tailored to the user's question.
Evaluate model: After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
Deploy it using Model Serving: Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 59
A Generative Al Engineer is deciding between using LSH (Locality Sensitive Hashing) and HNSW (Hierarchical Navigable Small World) for indexing their vector database Their top priority is semantic accuracy Which approach should the Generative Al Engineer use to evaluate these two techniques?
Answer: C
Explanation:
The task is to choose between LSH and HNSW for a vector database index, prioritizing semantic accuracy.
The evaluation must assess how well each method retrieves semantically relevant results. Let's evaluate the options.
* Option A: Compare the cosine similarities of the embeddings of returned results against those of a representative sample of test inputs
* Cosine similarity measures semantic closeness between vectors, directly assessing retrieval accuracy in a vector database. Comparing returned results' embeddings to test inputs' embeddings evaluates how well LSH or HNSW preserves semantic relationships, aligning with the priority.
* Databricks Reference:"Cosine similarity is a standard metric for evaluating vector search accuracy"("Databricks Vector Search Documentation," 2023).
* Option B: Compare the Bilingual Evaluation Understudy (BLEU) scores of returned results for a representative sample of test inputs
* BLEU evaluates text generation (e.g., translations), not vector retrieval accuracy. It's irrelevant for indexing performance.
* Databricks Reference:"BLEU applies to generative tasks, not retrieval"("Generative AI Cookbook").
* Option C: Compare the Recall-Oriented-Understudy for Gisting Evaluation (ROUGE) scores of returned results for a representative sample of test inputs
* ROUGE is for summarization evaluation, not vector search. It doesn't measure semantic accuracy in retrieval.
* Databricks Reference:"ROUGE is unsuited for vector database evaluation"("Building LLM Applications with Databricks").
* Option D: Compare the Levenshtein distances of returned results against a representative sample of test inputs
* Levenshtein distance measures string edit distance, not semantic similarity in embeddings. It's inappropriate for vector-based retrieval.
* Databricks Reference: No specific support for Levenshtein in vector search contexts.
Conclusion: Option A (cosine similarity) is the correct approach, directly evaluating semantic accuracy in vector retrieval, as recommended by Databricks for Vector Search assessments.
NEW QUESTION # 60
A Generative AI Engineer is deploying a customer-facing, fine-tuned LLM on their public website. Given the large investment the company put into fine-tuning this model, and the proprietary nature of the tuning data, they are concerned about model inversion attacks. Which of the following Databricks AI Security Framework (DASF) risk mitigation strategies are most relevant to this use case?
Answer: C
Explanation:
Model inversion attacks occur when an attacker uses the model's outputs to reconstruct the sensitive training data used during the fine-tuning process. To mitigate this in a public-facing application, implementing AI Guardrails is the most relevant strategy. Guardrails act as a programmable "filter" between the LLM and the end-user. They can be configured to detect if a model's response contains patterns that look like proprietary training data or PII (Personally Identifiable Information). While ACLs (B) and ABAC (D) protect the model's infrastructure (who can invoke the API), they do not inspect the content of the output, which is where the inversion attack actually manifests. Databricks provides integrated guardrail capabilities (via Mosaic AI Gateway) specifically to enforce compliance and prevent the leakage of sensitive internal knowledge that may have been baked into the model weights during fine-tuning.
NEW QUESTION # 61
......
DumpExam presents Databricks-Generative-AI-Engineer-Associate exam questions in a convenient PDF format for effective preparation for the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam. Databricks Databricks-Generative-AI-Engineer-Associate exam questions PDF file is designed for easy comprehension, allowing you to download it onto various smart devices. Whether you possess a PC, laptop, Mac, tablet, or smartphone, accessing your Databricks-Generative-AI-Engineer-Associate Practice Exam Questions PDF anytime and anywhere is effortless.
Databricks-Generative-AI-Engineer-Associate Free Updates: https://www.dumpexam.com/Databricks-Generative-AI-Engineer-Associate-valid-torrent.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1Jl-2taefbGpdYLDgezBoclm9tDlMLLmC