Trusted NVIDIA NCP-AIO: New NVIDIA AI Operations Test Questions - Newest BraindumpsPrep Dump NCP-AIO Check

BTW, DOWNLOAD part of BraindumpsPrep NCP-AIO dumps from Cloud Storage: https://drive.google.com/open?id=1sPo5ao6i5z3sYykfSjx3iWCxn0w2hXVn
There is no doubt that we all dream of working for top companies around the globe. Some people make it through but some keep on thinking about how to break that glass. If you are among those who belong to the latter category, you should start the preparations for the NVIDIA AI Operations (NCP-AIO) certification exam to improve your knowledge, expertise and crack even the toughest interview easily.
NVIDIA NCP-AIO Exam Overview:
>> New NCP-AIO Test Questions <<
NVIDIA AI Operationslatest test questions & NCP-AIO reliable braindumps & NVIDIA AI Operationsfree practice dumps
There is no another great way to pass the NVIDIA NCP-AIO exam in the first attempt only by doing a selective study with valid NCP-AIO braindumps. If you already have a job and you are searching for the best way to improve your current NCP-AIO test situation, then you should consider the NCP-AIO Exam Dumps. By using our updated NCP-AIO products, you will be able to get reliable and relative NCP-AIO exam prep questions, so you can pass the exam easily. You can get one-year free NCP-AIO exam updates from the date of purchase.
| Topic | Details |
|---|
| Topic 1 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 2 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 3 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 4 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
NVIDIA AI Operations Sample Questions (Q71-Q76):
NEW QUESTION # 71
You are using NVIDIA MPS (Multi-Process Service) to allow multiple CUDA applications to share a single GPU. One of the applications is consistently crashing. How can you isolate the faulty application using MPS?
- A. Disable MPS and run each application in isolation to identify the crashing application.
- B. Analyze the system logs for error messages associated with the application's process ID (PID).
- C. Run each application with a reduced number of threads to minimize potential conflicts.
- D. Restart the entire server to clear the GPU memory.
- E. Use 'nvidia-smi' to monitor the GPU's utilization and identify the application with the highest memory usage.
Answer: A,B
Explanation:
The most direct approach is to disable MPS and run each application independently to pinpoint the source of the crashes. Examining the system logs for error messages linked to specific PIDs helps identify the failing process. Monitoring GPU utilization (B) might provide hints, but it doesn't directly isolate the faulty application. Reducing threads (D) might mask the issue, but it doesn't solve it. Restarting the server (E) is a temporary solution and doesn't address the root cause.
NEW QUESTION # 72
A Fleet Command system administrator wants to create an organization user that will have the following rights:
For locations - read only
For Applications - read/write/admin
For Deployments - read/write/admin
For Dashboards - read only
What role should the system administrator assign to this user?
- A. Fleet Command Viewer
- B. Fleet Command Supporter
- C. Fleet Command Admin
- D. Fleet Command Operator
Answer: D
Explanation:
The Fleet Command Operator role is designed to provide users with read-only access to locations and dashboards while granting full read/write/admin rights for applications and deployments. This matches the described access requirements where the user can manage applications and deployments but only view locations and dashboards without modification rights.
Other roles like Fleet Command Admin have broader permissions, Supporter has more limited access, and Viewer is primarily read-only for all resources.
NEW QUESTION # 73
When installing Kubernetes using BCM on NVIDIA servers, which of the following components are crucial for enabling GPU support within the cluster?
- A. kube-proxy running in IPVS mode
- B. Kubernetes Device Plugin for NVIDIA GPUs
- C. NVIDIA Driver on each worker node
- D. Containerd CRI
- E. NVIDIA Container Runtime (nvidia-container-runtime)
Answer: B,C,E
Explanation:
The Kubernetes Device Plugin allows Kubernetes to discover and manage NVIDIA GPUs. The NVIDIA Container Runtime is a low-level library that provides the necessary hooks to expose the GPUs to containers. The NVIDIA driver is the foundation for all GPU operations. Kube-proxy mode and containerd CRI are important for general kubernetes networking and containerization but do not specifically enable GPU Support. IPVS is not specifically related and Containerd is not NVIDIA specific
NEW QUESTION # 74
Explanation:
You are running a Docker container that utilizes NVIDIA GPUs for deep learning inference. The application inside the container fails to detect the GPUs. You've verified that NVIDIA drivers are installed on the host. What is the MOST likely cause and how do you fix it?
- A. The NVIDIA Container Toolkit is not installed or configured correctly on the host machine. Install and configure the toolkit following NVIDIA's official documentation.
- B. The '"gpus all' flag was not used when running the container. Re-run the container with 'docker run -gpus all ...w.
- C. The host's firewall is blocking communication between the container and the NVIDIA drivers. Disable the firewall or create an exception for the container network.
- D. The Docker daemon is not configured to use the NVIDIA runtime. Modify the '/etc/docker/daemon.json' file to include "'default-runtime": "nvidia"' and restart the Docker daemon.
- E. The CUDA version in the container does not match the driver version on the host. Ensure the container uses a CUDA version compatible with the host driver.
Answer: A,B
Explanation:
You are running a Docker container that utilizes NVIDIA GPUs for deep learning inference. The application inside the container fails to detect the GPUs. You've verified that NVIDIA drivers are installed on the host. What is the MOST likely cause and how do you fix it?
NEW QUESTION # 75
Consider the following Kubernetes pod definition:
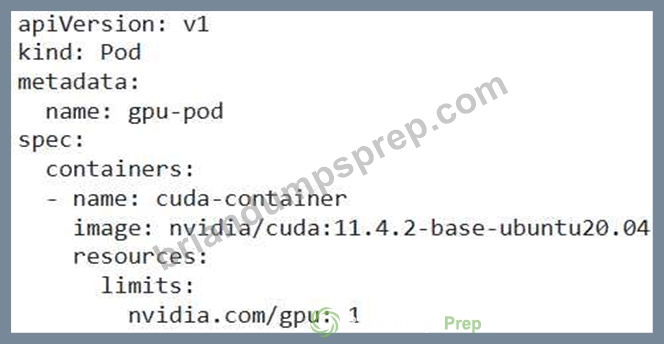
What does the 'nvidia.com/gpu: 1' setting achieve?
- A. It reserves one virtual GPU (vGPU) instance for the container.
- B. It limits the container's GPU memory usage to IGB.
- C. It allows the container to access NVIDIA drivers and libraries.
- D. It allocates one full GPU to the container.
- E. It ensures that the pod is scheduled on a node with at least one NVIDIA GPU.
Answer: C,D,E
Explanation:
The 'nvidia.com/gpu: 1 ' resource request ensures the pod is scheduled on a node with a GPU. It effectively allocates one full GPU to the container (unless using vGPU). It also implicitly provides access to NVIDIA drivers and libraries through the device plugin mechanism. It doesn't directly limit memory usage or reserve vGPU instances; those require additional configurations.
NEW QUESTION # 76
......
Dump NCP-AIO Check: https://www.briandumpsprep.com/NCP-AIO-prep-exam-braindumps.html
- NCP-AIO Exam 🤠 Latest NCP-AIO Exam Papers 🟫 NCP-AIO Exam Dump 🛬 Open website ( www.examcollectionpass.com ) and search for { NCP-AIO } for free download 😣Exam NCP-AIO Cram
- Valid NCP-AIO Exam Objectives 🍝 New NCP-AIO Braindumps Pdf 🕛 NCP-AIO Exam ✏ Search on 「 www.pdfvce.com 」 for ⏩ NCP-AIO ⏪ to obtain exam materials for free download 🩺NCP-AIO Exam
- NCP-AIO Exam Dump 🐺 Valid NCP-AIO Exam Objectives 🎃 Valid NCP-AIO Exam Simulator 🍀 Open ✔ www.torrentvce.com ️✔️ and search for ⮆ NCP-AIO ⮄ to download exam materials for free 🧾NCP-AIO Test Answers
- NCP-AIO Exam Guides - NCP-AIO Test Answers - NCP-AIO Exam Torrent 🤩 Search on 「 www.pdfvce.com 」 for 【 NCP-AIO 】 to obtain exam materials for free download 🥋NCP-AIO Valid Test Experience
- Pass Guaranteed 2026 Marvelous NVIDIA NCP-AIO: New NVIDIA AI Operations Test Questions 📺 Open website ⮆ www.examcollectionpass.com ⮄ and search for ✔ NCP-AIO ️✔️ for free download 🅱NCP-AIO Valid Test Experience
- Exam Dumps NCP-AIO Zip 😑 Latest NCP-AIO Exam Papers 🔈 Valid Braindumps NCP-AIO Free 🪒 Copy URL 《 www.pdfvce.com 》 open and search for ( NCP-AIO ) to download for free 👔NCP-AIO Test Score Report
- New NCP-AIO Braindumps Pdf 🩲 Exam Dumps NCP-AIO Zip 🦏 New NCP-AIO Braindumps Pdf 🤺 Search for ➡ NCP-AIO ️⬅️ and obtain a free download on ➠ www.pdfdumps.com 🠰 🌞NCP-AIO Valid Test Experience
- Valid Braindumps NCP-AIO Free 🍇 NCP-AIO Exam Dump 🔔 NCP-AIO Test Answers 🎎 The page for free download of ▷ NCP-AIO ◁ on ( www.pdfvce.com ) will open immediately 🚃Exam Dumps NCP-AIO Zip
- Valid NCP-AIO Exam Simulator 😞 Exam NCP-AIO Cram 🐨 Test NCP-AIO Study Guide 🌜 Open [ www.prep4away.com ] enter ☀ NCP-AIO ️☀️ and obtain a free download 🐋NCP-AIO Exam Dump
- Top New NCP-AIO Test Questions | Valid NCP-AIO: NVIDIA AI Operations 100% Pass 🚺 Search for ⏩ NCP-AIO ⏪ and easily obtain a free download on ▛ www.pdfvce.com ▟ 😝Test NCP-AIO Study Guide
- www.vceengine.com: The Ultimate Solution for NVIDIA NCP-AIO Certification Exam Preparation 🎾 Search for ➡ NCP-AIO ️⬅️ and easily obtain a free download on 【 www.vceengine.com 】 🟨NCP-AIO Valid Test Experience
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of BraindumpsPrep NCP-AIO dumps for free: https://drive.google.com/open?id=1sPo5ao6i5z3sYykfSjx3iWCxn0w2hXVn