What's more, part of that Getcertkey SPS-C01 dumps now are free: https://drive.google.com/open?id=1nSaHBculLj3JGes6Jpf67M5HrKsB0rl5
Our SPS-C01 study materials are designed by a reliable and reputable company and our company has rich experience in doing research about the study materials. We can make sure that all employees in our company have wide experience and advanced technologies in designing the SPS-C01 Study Materials. So a growing number of the people have used our study materials in the past years, and it has been a generally acknowledged fact that the quality of the SPS-C01 study materials from our company is best in the study materials market.
| Section | Objectives |
|---|---|
| Topic 1: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: Data Engineering with Snowpark | - Pipeline development
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 6: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
>> SPS-C01 Standard Answers <<
If you can own the certification means that you can do the job well in the area so you can get easy and quick promotion. The latest SPS-C01 quiz torrent can directly lead you to the success of your career. Our materials can simulate real operation exam atmosphere and simulate exams. The download and install set no limits for the amount of the computers and the persons who use SPS-C01 Test Prep. So we provide the best service for you as you can choose the most suitable learning methods to master the SPS-C01 exam torrent. Believe us and if you purchase our product it is very worthy.
NEW QUESTION # 173
You are designing a Snowpark application to process streaming data ingested into Snowflake using Snowpipe. The application needs to apply a complex set of transformations and aggregations to the incoming data in real-time. Which of the following approaches would be MOST suitable for this scenario, leveraging the strengths of Snowpark architecture?
Answer: D
Explanation:
Using a Snowpark Stored Procedure triggered by a Snowflake Task provides the best solution for real-time processing of streaming data from Snowpipe. The Task automates the execution of the stored procedure whenever new data is available, and the stored procedure leverages Snowpark's server-side capabilities to perform the transformations and aggregations efficiently within the Snowflake environment. Option A involves client-side processing, Option B isn't compatible with Snowpipe directly and chained UDFs may not optimal for complex transformations and aggregations. Option C involves constant writes and may have performance issues with large datasets. While option E could work, utilizing Snowpark stored procedures provides better flexibility and Python code integration for more complex logic.
NEW QUESTION # 174
You are working with a Snowpark DataFrame containing website traffic data'. The DataFrame has columns like 'date' , 'page_url', and 'visit_count'. You need to calculate the cumulative sum of visit counts for each 'page_url' over time (i.e., ordered by 'date'). However, you only want to consider data from the last 30 days for each calculation. Which of the following Snowpark code snippets will correctly achieve this using window functions with a frame specification?





Answer: E
Explanation:
Option B is correct because it uses 'rangeBetween(-30, 0)' which specifies a frame that includes all rows within a range of 30 days preceding the current row, based on the ordering defined by the "date" column. Since 'date' column is used for ordering, we need to use rangeBetween' and NOT 'rowsBetween' . Also, we need to use 'sf.sum()' for Snowflake functions'. If the column is of Timestamp type, 'rangeBetween' represents days only, and in case it's numeric type represents numeric interval. Option A calculates the cumulative sum from the beginning of time for each page URL. Option C doesn't correctly specify the end of the frame. Option D has incorrect syntax and may not work. Option E uses incorrect sum function as well, as it misses sf prefix.
NEW QUESTION # 175
You are developing a Snowpark application that processes large datasets stored in Snowflake. You need to implement custom User-Defined Functions (UDFs) written in Java. The UDF requires specific third-party libraries that are not available in the default Snowflake Java environment. What steps are necessary to package and deploy these UDFs correctly?
Answer: E
Explanation:
The correct approach involves packaging the Java code and its dependencies into a JAR file, uploading it to a Snowflake stage, and using the 'CREATE FUNCTION' command with the 'IMPORTS clause. This informs Snowflake to include the specified JAR file in the classpath when executing the UDF. Other options are not valid ways to deploy Java UDFs with dependencies in Snowflake.
NEW QUESTION # 176
You are working with a Snowpark DataFrame 'products df' containing product information, including 'product_id', 'price', and 'discount'. You need to update the 'price' column in the 'products' table based on the following logic: If 'discount' is greater than 0.2, reduce the 'price' by 15%. If 'discount' is between 0.1 and 0.2 (inclusive), reduce the 'price' by 5%. Otherwise, keep the 'price' as is. Which of the following Snowpark code snippets efficiently implements this update? Assume 'products' table already exists and is correctly populated.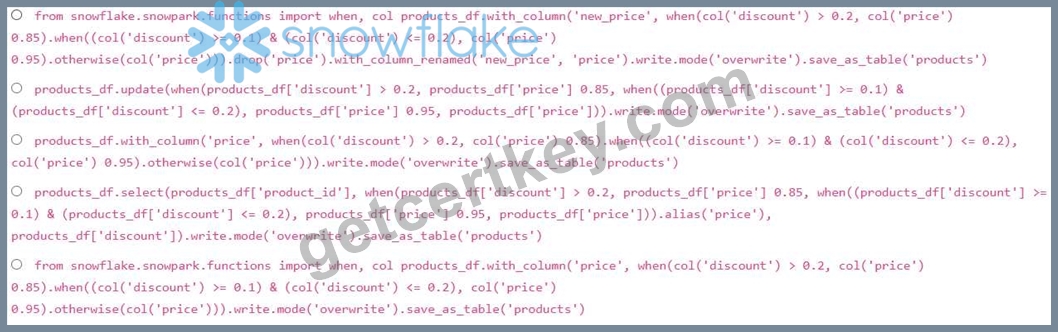
Answer: C
Explanation:
Option E is the most concise and correct solution. It uses 'with_column' to directly update the 'price' column based on the discount conditions, using nested 'when' functions for the logic and persists the change. Option A, while technically correct, is less efficient because it creates a new column ('new_price'), drops the original 'price' column, and then renames the new column. Option B tries to use an 'update' method which doesn't exist directly on Snowpark DataFrames in that way. Option C works correctly. Option D has an issue that it won't keep the original schema of the table being updated as it is selecting each of the columns.
NEW QUESTION # 177
A Snowpark application processes streaming data from Kafka, performing complex windowing aggregations. The application is configured with auto-scaling enabled for the virtual warehouse. During peak hours, the application exhibits high latency despite the warehouse scaling up. Upon investigation, you observe sustained high CPU utilization on the single active warehouse. Which actions, alone or in combination, would MOST effectively improve performance while minimizing cost?
Answer: C,E
Explanation:
Optimizing the Snowpark code (Option B) reduces the overall CPU load, while repartitioning the data (Option C) distributes the work more evenly across multiple clusters, reducing hotspots and enabling parallel processing. Increasing MAX_CLUSTER_COUNT (Option A) only helps if the workload is already evenly distributed. Increasing MIN_CLUSTER COUNT (Option D) may add to cost without addressing the underlying code issues or data skew. Decreasing SCALING_POLICY (Option E) may help with responsiveness but isn't a fundamental solution.
NEW QUESTION # 178
......
The procedures of buying our SPS-C01 study materials are simple and save the clients’ time. We will send our SPS-C01 exam question in 5-10 minutes after their payment. Because the most clients may be busy in their jobs or other significant things, the time they can spare to learn our SPS-C01 learning guide is limited and little. But if the clients buy our SPS-C01 training quiz they can immediately use our product and save their time. And the quality of our exam dumps are very high!
SPS-C01 Excellect Pass Rate: https://www.getcertkey.com/SPS-C01_braindumps.html
2026 Latest Getcertkey SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1nSaHBculLj3JGes6Jpf67M5HrKsB0rl5