DOWNLOAD the newest PrepAwayExam MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1vPDSa6Q1dpshB_wpYdcU3-7Wd5pfdaze
Our MLA-C01 test guide has become more and more popular in the world. Of course, if you decide to buy our MLA-C01 latest question, we can make sure that it will be very easy for you to pass your exam and get the certification in a short time, first, you just need 5-10 minutes can receive MLA-C01 Exam Torrent that you can learn and practice it. Then you just need 20-30 hours to practice our MLA-C01 study materials that you can attend your MLA-C01 exam. It is really spend your little time and energy.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Valid Amazon MLA-C01 Exam Tutorial <<
This updated Amazon MLA-C01 exam study material of PrepAwayExam consists of these 3 formats: Amazon MLA-C01 PDF, desktop practice test software, and web-based practice exam. Each format of PrepAwayExam aids a specific preparation style and offers unique advantages, each of which is beneficial for strong AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam preparation. The features of our three formats are listed below. You can choose any format as per your practice needs.
NEW QUESTION # 25
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: C
Explanation:
Preparing a training dataset that includes both categorical and numerical data is essential for maximizing the accuracy of a machine learning model. Transforming categorical data into numerical format is a critical step, as most ML algorithms require numerical input.
Why Transform Categorical Data into Numerical Data?
* Model Compatibility: Many ML algorithms cannot process categorical data directly and require numerical representations.
* Improved Performance: Proper encoding of categorical variables can enhance model accuracy and convergence speed.
Why Use Amazon SageMaker Data Wrangler?
Amazon SageMaker Data Wrangler offers a visual interface with over 300 built-in data transformations, including tools for encoding categorical variables.
Implementation Steps:
* Import Data:
* Load the dataset into SageMaker Data Wrangler from sources like Amazon S3 or on-premises databases.
* Identify Categorical Features:
* Use Data Wrangler's data type inference to detect categorical columns.
* Apply Categorical Encoding:
* Choose appropriate encoding techniques (e.g., one-hot encoding or ordinal encoding) from Data Wrangler's transformation options.
* Apply the selected transformation to convert categorical features into numerical format.
* Validate Transformations:
* Review the transformed dataset to ensure accuracy and completeness.
Advantages of Using SageMaker Data Wrangler:
* Ease of Use: Provides a user-friendly interface for data transformation without extensive coding.
* Operational Efficiency: Integrates data preparation steps, reducing the need for multiple tools and minimizing operational overhead.
* Flexibility: Supports various data sources and transformation techniques, accommodating diverse datasets.
By utilizing SageMaker Data Wrangler to transform categorical data into numerical format, the ML engineer can efficiently prepare the dataset, thereby enhancing the model's accuracy with minimal operational overhead.
Transform Data - Amazon SageMaker
Prepare ML Data with Amazon SageMaker Data Wrangler
NEW QUESTION # 26
An ML engineer notices class imbalance in an image classification training job.
What should the ML engineer do to resolve this issue?
Answer: B
NEW QUESTION # 27
An ML engineer is tuning an image classification model that shows poor performance on one of two available classes during prediction. Analysis reveals that the images whose class the model performed poorly on represent an extremely small fraction of the whole training dataset.
The ML engineer must improve the model's performance.
Which solution will meet this requirement?
Answer: D
Explanation:
This problem describes severe class imbalance in an image classification task, where the minority class has poor predictive performance. In such cases, accuracy is a misleading metric, because a model can achieve high accuracy by predicting only the majority class. AWS ML best practices recommend using F1 score, which balances precision and recall and is more appropriate for imbalanced classification problems.
To improve performance on the minority image class, image augmentation is the preferred approach.
Augmentation techniques-such as rotation, cropping, flipping, and brightness adjustment-create realistic new training examples while preserving semantic meaning. AWS documentation recommends augmentation for computer vision workloads to improve generalization without collecting new data.
SMOTE (Options C and D) is designed for tabular data, not image data, and generating synthetic pixel-level images using SMOTE is not appropriate or supported in typical computer vision pipelines.
Option A is incorrect because optimizing for accuracy does not address minority-class performance. Option D is incorrect because SMOTE is unsuitable for images.
Therefore, optimizing for F1 score and using image augmentation on the minority class is the correct solution.
NEW QUESTION # 28
A healthcare company wants to detect irregularities in patient vital signs that could indicate early signs of a medical condition. The company has an unlabeled dataset that includes patient health records, medication history, and lifestyle changes.
Which algorithm and hyperparameter should the company use to meet this requirement?
Answer: B
Explanation:
Option D is correct because Amazon SageMaker AI Random Cut Forest (RCF) is documented by AWS as an unsupervised algorithm for detecting anomalous data points within a data set . The question describes a healthcare use case where the company wants to detect irregularities in patient vital signs and only has an unlabeled dataset . That is a direct match for anomaly detection with an unsupervised method rather than a supervised classification or regression algorithm. AWS documentation also notes that anomalies can appear as unexpected spikes, breaks in patterns, or otherwise unusual observations.
RCF is a strong fit because it does not require labeled target outcomes to begin identifying unusual observations. AWS explains that RCF assigns an anomaly score to each data point, where higher scores indicate potentially anomalous records. This is especially suitable for early warning scenarios in healthcare, where the goal is to surface unusual combinations of vitals, medication history, and lifestyle changes for further review.
The hyperparameter in the answer, num_trees , is a valid RCF hyperparameter and controls the number of trees used in the forest. In AWS examples and documentation, this is one of the key parameters used when configuring the algorithm. By contrast, XGBoost is generally used for supervised tasks, k-means is for clustering rather than anomaly scoring, and DeepAR is for forecasting time series rather than general anomaly detection across an unlabeled multidimensional dataset.
Therefore, the fully verified AWS-docs answer is D , because Random Cut Forest is the AWS-native unsupervised anomaly detection algorithm best aligned to this healthcare irregularity-detection requirement.
NEW QUESTION # 29
A company wants to evaluate a new ML model architecture to understand its performance before deploying the model to production. The company wants to use Amazon SageMaker AI shadow testing.
The company needs to analyze the performance metrics of the shadow model and the production model without affecting the existing production endpoint. The analysis must use real-time inference requests.
Select and order the correct steps to implement shadow testing and compare the model variants in SageMaker AI. Select each step one time or not at all (Select and order Three)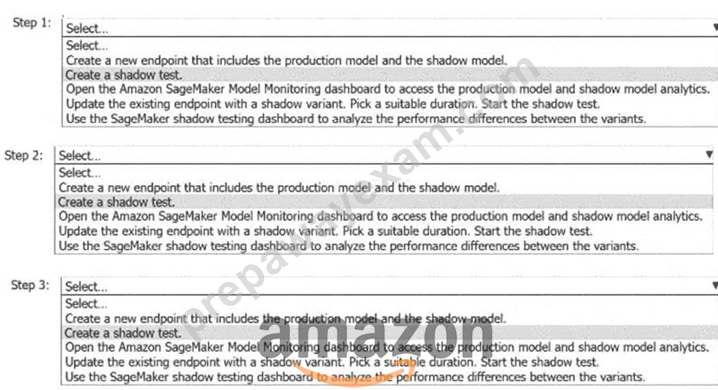
Answer:
Explanation: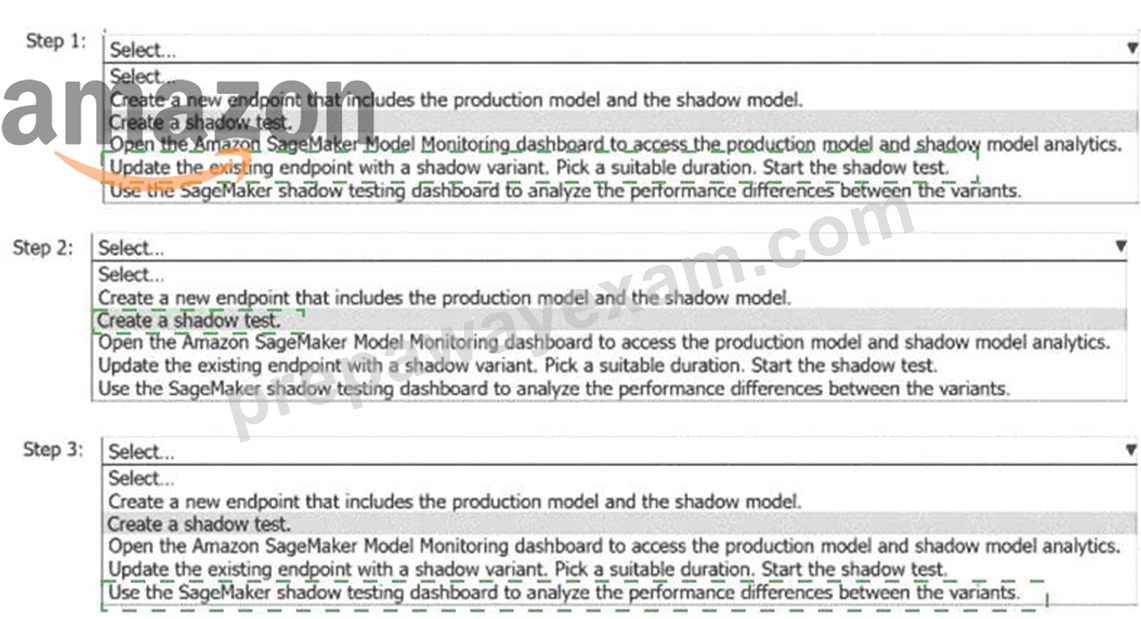
Explanation:
Step 1: Update the existing endpoint with a shadow variant. Pick a suitable duration. Start the shadow test.
Step 2: Create a shadow test.
Step 3: Use the SageMaker shadow testing dashboard to analyze the performance differences between the variants.
This is the correct order because SageMaker shadow testing can run against an existing production endpoint.
The production variant continues to receive and respond to inference requests, while the shadow variant receives replicated real-time requests but does not return responses to users. That satisfies the requirement to analyze the new model with real inference traffic without affecting the production endpoint. AWS also states that the SageMaker shadow testing dashboard provides side-by-side comparison metrics for the production and shadow variants, such as latency and error rate.
Do not choose "Create a new endpoint that includes the production model and the shadow model," because the question explicitly says the analysis must not affect the existing production endpoint. Also, do not use the Amazon SageMaker Model Monitoring dashboard here; the specific feature for comparing variants in this scenario is the SageMaker shadow testing dashboard.
NEW QUESTION # 30
......
The PDF version of our MLA-C01 learning guide is convenient for reading and supports the printing of our study materials. If client uses the PDF version of MLA-C01 exam questions, they can download the demos freely. If clients feel good after trying out our demos they will choose the full version of the test bank to learn our MLA-C01 Study Materials. And the PDF version can be printed into paper documents and convenient for the client to take notes.
MLA-C01 New Dumps Book: https://www.prepawayexam.com/Amazon/braindumps.MLA-C01.ete.file.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by PrepAwayExam: https://drive.google.com/open?id=1vPDSa6Q1dpshB_wpYdcU3-7Wd5pfdaze