BONUS!!! Download part of Itcertmaster Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1YQ9kKXKQYuvGKEt4MQBIoQXmVgicx8qL
If the user does not complete the mock test question in a specified time, the practice of all Databricks-Certified-Data-Engineer-Associate learning materials previously done by the user will automatically uploaded to our database. The system will then generate a report based on the user's completion results, and a report can clearly understand what the user is good at. Finally, the transfer can be based on the Databricks-Certified-Data-Engineer-Associate Learning Materials report to develop a learning plan that meets your requirements. With constant practice, users will find that feedback reports are getting better, because users spend enough time on our Databricks-Certified-Data-Engineer-Associate learning materials.
| Section | Objectives |
|---|---|
| Data Processing and Transformations | - User-defined functions (UDFs) - PySpark DataFrame transformations - Delta Lake fundamentals (tables, transactions, optimization) - Apache Spark SQL operations (joins, aggregations, filtering) |
| Data Governance and Quality | - Unity Catalog basics - Data quality concepts and management - Data access control and governance |
| Databricks Lakehouse Platform Fundamentals | - Clusters, notebooks, and basic Databricks environment usage - Workspace, architecture, and core platform concepts |
| Data Ingestion and ELT Development | - ETL patterns and transformations - Data ingestion using Spark SQL and PySpark - Handling structured and semi-structured data |
| Productionizing Data Pipelines | - Pipeline deployment and operationalization - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration |
>> Certification Databricks-Certified-Data-Engineer-Associate Book Torrent <<
In order to save you a lot of installation troubles, we have carried out the online engine of the Databricks-Certified-Data-Engineer-Associate latest exam guide which does not need to download and install. This kind of learning method is convenient and suitable for quick pace of life. But you must have a browser on your device. Our online workers are going through professional training. Your demands and thought can be clearly understood by them. Even if you have bought our high-pass-rate Databricks-Certified-Data-Engineer-Associate training practice but you do not know how to install it, we can offer remote guidance to assist you finish installation. In the process of using, you still have access to our after sales service. All in all, we will keep helping you until you have passed the Databricks-Certified-Data-Engineer-Associate exam and got the certificate.
NEW QUESTION # 143
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below: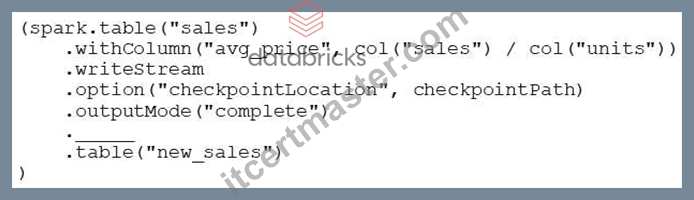
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
Answer: C
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). References: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 144
In which of the following scenarios should a data engineer use the MERGE INTO command instead of the INSERT INTO command?
Answer: E
Explanation:
The MERGE INTO command is used to perform upserts, which are a combination of insertions and updates, based on a source table into a target Delta table1. The MERGE INTO command can handle scenarios where the target table cannot contain duplicate records, such as when there is a primary key or a unique constraint on the target table. The MERGE INTO command can match the source and target rows based on a merge condition and perform different actions depending on whether the rows are matched or not. For example, the MERGE INTO command can update the existing target rows with the new source values, insert the new source rows that do not exist in the target table, or delete the target rows that do not exist in the source table1.
The INSERT INTO command is used to append new rows to an existing table or create a new table from a query result2. The INSERT INTO command does not perform any updates or deletions on the existing target table rows. The INSERT INTO command can handle scenarios where the location of the data needs to be changed, such as when the data needs to be moved from one table to another, or when the data needs to be partitioned by a certain column2. The INSERT INTO command can also handle scenarios where the target table is an external table, such as when the data is stored in an external storage system like Amazon S3 or Azure Blob Storage3. The INSERT INTO command can also handle scenarios where the source table can be deleted, such as when the source table is a temporary table or a view4. The INSERT INTO command can also handle scenarios where the source is not a Delta table, such as when the source is a Parquet, CSV, JSON, or Avro file5.
Reference:
1: MERGE INTO | Databricks on AWS
2: [INSERT INTO | Databricks on AWS]
3: [External tables | Databricks on AWS]
4: [Temporary views | Databricks on AWS]
5: [Data sources | Databricks on AWS]
NEW QUESTION # 145
A company uses Delta Sharing to collaborate with partners across different cloud providers and geographic regions. What will result in additional costs due to cross-region or egress fees?
Answer: C
Explanation:
Databricks documents that Delta Sharing does not require data replication, but cloud providers can still charge data egress fees when data is shared across clouds or across geographic regions. Databricks specifically states that sharing within the same region incurs no egress cost, while cross-cloud or cross-region transfers can create additional charges from the underlying cloud provider. That means option A is correct. Options B and C describe same-cloud or same-region use cases that do not trigger the cross-region/cross-cloud egress pattern Databricks calls out. Option D is unrelated to the main documented billing driver for Delta Sharing costs. The important principle is that Delta Sharing itself is designed to avoid replication overhead, but the physical movement of data between cloud boundaries or regions can still result in vendor networking charges. Therefore, when sharing data with external partners in other regions or clouds, engineers should plan for possible egress costs and monitor them accordingly.
=========
NEW QUESTION # 146
A data engineer is designing a bronze-to-silver pipeline on the Databricks Data Intelligence Platform. The source system sends daily CSV files, and over time, new optional columns are added.
The data engineer wants a storage format and table feature that together ensure the following:
- The table prevents writes that do not conform to the defined schema.
- The table can evolve its schema to include new optional columns
without having to manually recreate the table.
- Previous versions of the table can be queried later for debugging and auditing.
Which solution fulfills the requirements?
Answer: C
Explanation:
Delta Lake provides schema enforcement, supports schema evolution for newly added columns, and retains table history for time travel and auditing.
NEW QUESTION # 147
A data engineering team needs to incrementally ingest customer transactions from a SaaS app into Data Intelligence Platform with:
- Built-in change data capture (including updates and deletes)
- Automatic schema evolution
- Serverless execution with retries and minimal maintenance
- OAuth support and basic monitoring
Which solution meets all of these requirements?
Answer: A
Explanation:
Lakeflow Connect managed connectors provide source-specific OAuth authentication, built-in incremental ingestion and CDC, automatic schema evolution, automated retries, serverless execution, and integrated monitoring with minimal custom maintenance.
NEW QUESTION # 148
......
Our Databricks-Certified-Data-Engineer-Associate practice questions are on the cutting edge of this line with all the newest contents for your reference. Free demos are understandable and part of the Databricks-Certified-Data-Engineer-Associate exam materials as well as the newest information for your practice. And because that our Databricks-Certified-Data-Engineer-Associate Study Guide has three versions: the PDF, Software and APP online. So accordingly, we offer three versions of free demos for you to download.
New Databricks-Certified-Data-Engineer-Associate Test Vce Free: https://www.itcertmaster.com/Databricks-Certified-Data-Engineer-Associate.html
2026 Latest Itcertmaster Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1YQ9kKXKQYuvGKEt4MQBIoQXmVgicx8qL