As far as the prices of Databricks-Certified-Professional-Data-Engineer exam dumps are concerned, we ensure you that our Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions prices are entirely affordable for everyone. The real and updated Databricks-Certified-Professional-Data-Engineer exam dumps are being offered at discounted prices. You can grab this opportunity and download the top-notch and real Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions at discounted prices. Best wishes for the final Databricks Databricks-Certified-Professional-Data-Engineer certification exam!!!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Topic 2: Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Topic 4: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Topic 5: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 6: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Topic 7: Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Topic 8: Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Topic 9: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching - Cluster configuration and scaling |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
>> Databricks-Certified-Professional-Data-Engineer Test Dates <<
If you feel difficult in choosing which version of our Databricks-Certified-Professional-Data-Engineer reliable exam guide, if you want to be simple, PDF version may be suitable for you. PDF version is a normal file. Many candidates are used to printing out and then writing & reading of Databricks-Certified-Professional-Data-Engineer reliable exam guide on paper. Yes, it is silent and clear. Also if you have some unclearly questions, you can ask or talk with others easily. Others may just think that it is normally practice material. Also you can print out many copies of Databricks Databricks-Certified-Professional-Data-Engineer Reliable Exam Guide and share with others.
NEW QUESTION # 36
Which statement describes Delta Lake Auto Compaction?
Answer: E
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones.
Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 37
The data engineering team maintains the following code: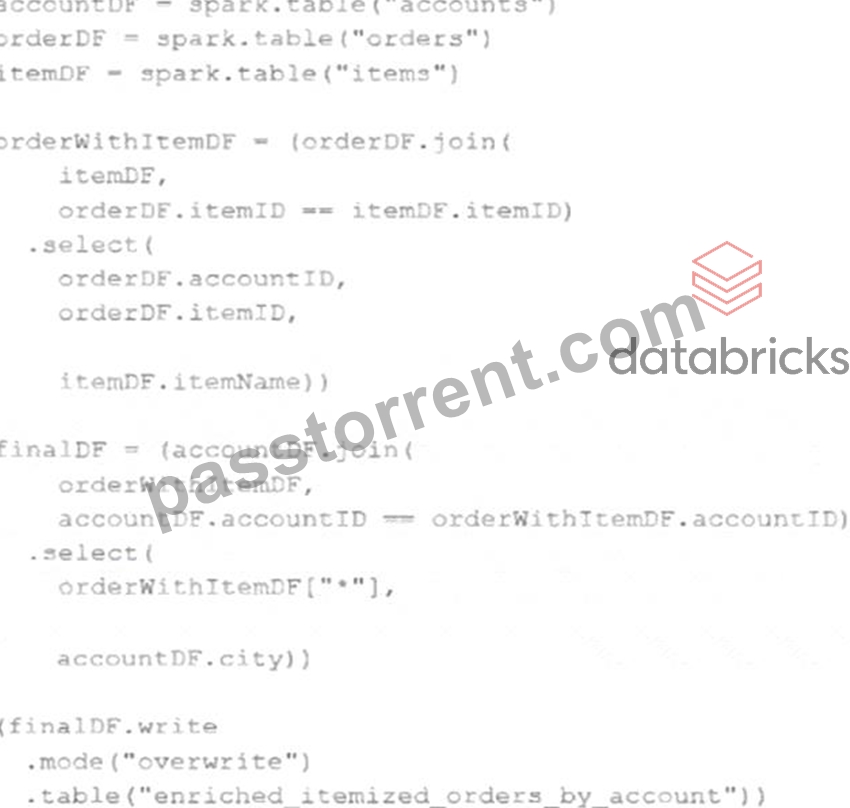
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: D
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 38
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
Answer: E
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. Reference:
transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
NEW QUESTION # 39
A data team is automating a daily multi-task ETL pipeline in Databricks. The pipeline includes a notebook for ingesting raw data, a Python wheel task for data transformation, and a SQL query to update aggregates. They want to trigger the pipeline programmatically and see previous runs in the GUI. They need to ensure tasks are retried on failure and stakeholders are notified by email if any task fails.
Which two approaches will meet these requirements? (Choose 2 answers)
Answer: A,D
Explanation:
Databricks Jobs supports defining multi-task workflows that include notebooks, SQL statements, and Python wheel tasks. These can be configured with retry policies, dependency chains, and failure notifications. The correct practice, as stated in the documentation, is to use the Jobs REST API (/jobs/create) or Databricks Asset Bundles to define multi-task jobs, and then trigger them programmatically using /jobs/run-now, CLI, or SDK. This allows the team to maintain full job history, handle retries automatically, and receive alerts via configured email notifications. Using /jobs/runs/submit creates one-off ad hoc runs without maintaining dependency visibility. Therefore, options B and C together satisfy the operational, automation, and governance requirements.
NEW QUESTION # 40
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
Answer: E
Explanation:
The libraries command group allows you to install, uninstall, and list libraries on Databricks clusters. You can use the libraries install command to install a custom Python Wheel on a cluster by specifying the --whl option and the path to the wheel file. For example, you can use the following command to install a custom Python Wheel named mylib-0.1-py3-none-any.whl on a cluster with the id 1234-567890-abcde123:
databricks libraries install --cluster-id 1234-567890-abcde123 --whl
dbfs:/mnt/mylib/mylib-0.1-py3-none-any.whl
This will upload the custom Python Wheel to the cluster and make it available for use with a production job.
You can also use the libraries uninstall command to uninstall a library from a cluster, and the libraries list command to list the libraries installed on a cluster.
References:
* Libraries CLI (legacy): https://docs.databricks.com/en/archive/dev-tools/cli/libraries-cli.html
* Library operations: https://docs.databricks.com/en/dev-tools/cli/commands.html#library-operations
* Install or update the Databricks CLI: https://docs.databricks.com/en/dev-tools/cli/install.html
NEW QUESTION # 41
......
If you fail, don't forget to learn your lesson. If you still prepare for your test yourself and fail again and again, it is time for you to choose a valid Databricks-Certified-Professional-Data-Engineer study guide; this will be your best method for clearing exam and obtain a certification. Good Databricks-Certified-Professional-Data-Engineer study guide will be a shortcut for you to well-directed prepare and practice efficiently, you will avoid do much useless efforts and do something interesting. PassTorrent releases 100% pass-rate Databricks-Certified-Professional-Data-Engineer Study Guide files which guarantee candidates 100% pass exam in the first attempt.
Reliable Databricks-Certified-Professional-Data-Engineer Exam Practice: https://www.passtorrent.com/Databricks-Certified-Professional-Data-Engineer-latest-torrent.html