P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by ITexamReview: https://drive.google.com/open?id=1emd0QMthtlHiCBqEZ5JEjBtkNGowS1u3
We have a variety of versions for your reference: PDF & Software & APP version. All those versions are high efficient and accurate with passing rate up to 98 to 100 percent. So our Professional-Machine-Learning-Engineer Study Guide is efficient, high-quality for you. Such high quality and low price traits of our Professional-Machine-Learning-Engineer guide materials make exam candidates reassured.
| Section | Objectives |
|---|---|
| Monitoring ML solutions | - Performance monitoring and drift detection - Logging and alerting (Cloud Monitoring) - Model retraining strategies |
| Architecting low-code ML solutions | - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models - AutoML capabilities and implementation |
| Scaling prototypes into ML models | - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Training at scale (Distributed training, TPUs) |
| Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Serving and scaling models | - Online prediction (Vertex AI Prediction) - Model optimization (Quantization, Distillation) - Hardware accelerators (GPU/TPU) in serving - Batch prediction |
| Collaborating within and across teams to manage data and models | - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) |
>> Valid Test Professional-Machine-Learning-Engineer Vce Free <<
If you are determined to purchase our Google Professional Machine Learning Engineer Professional-Machine-Learning-Engineer valid exam collection materials for your companies, if you pursue long-term cooperation with site, we will have some relate policy. Firstly we provide one-year service warranty for every buyer who purchased Google Professional-Machine-Learning-Engineer valid exam collection materials.
NEW QUESTION # 315
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?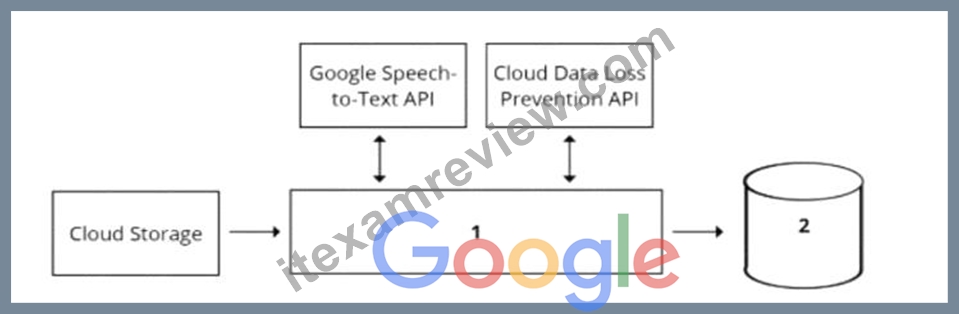
Answer: B
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL
* ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 316
A Machine Learning Specialist working for an online fashion company wants to build a data ingestion solution for the company's Amazon S3-based data lake.
The Specialist wants to create a set of ingestion mechanisms that will enable future capabilities comprised of:
* Real-time analytics
* Interactive analytics of historical data
* Clickstream analytics
* Product recommendations
Which services should the Specialist use?
Answer: D
NEW QUESTION # 317
You are using Kubeflow Pipelines to develop an end-to-end PyTorch-based MLOps pipeline. The pipeline reads data from BigQuery, processes the data, conducts feature engineering, model training, model evaluation, and deploys the model as a binary file to Cloud Storage. You are writing code for several different versions of the feature engineering and model training steps, and running each new version in Vertex Al Pipelines.
Each pipeline run is taking over an hour to complete. You want to speed up the pipeline execution to reduce your development time, and you want to avoid additional costs. What should you do?
Answer: C
Explanation:
Kubeflow Pipelines allows for efficient use of compute resources through parallel task execution and caching, which eliminates redundant executions1. By enabling caching in all the steps of the Kubeflow pipeline, you can avoid re-running the same steps when you execute the pipeline multiple times. This can significantly speed up the pipeline execution and reduce your development time without incurring additional costs
NEW QUESTION # 318
You recently used XGBoost to train a model in Python that will be used for online serving Your model prediction service will be called by a backend service implemented in Golang running on a Google Kubemetes Engine (GKE) cluster Your model requires pre and postprocessing steps You need to implement the processing steps so that they run at serving time You want to minimize code changes and infrastructure maintenance and deploy your model into production as quickly as possible. What should you do?
Answer: D
Explanation:
The best option for implementing the processing steps so that they run at serving time, minimizing code changes and infrastructure maintenance, and deploying the model into production as quickly as possible, is to use the Predictor interface to implement a custom prediction routine. Build the custom container, upload the container to Vertex AI Model Registry, and deploy it to a Vertex AI endpoint. This option allows you to leverage the power and simplicity of Vertex AI to serve your XGBoost model with minimal effort and customization. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained XGBoost model to an online prediction endpoint, which can provide low-latency predictions for individual instances. A custom prediction routine (CPR) is a Python script that defines the logic for preprocessing the input data, running the prediction, and postprocessing the output data. A CPR can help you customize the prediction behavior of your model, and handle complex or non- standard data formats. A CPR can also help you minimize the code changes, as you only need to write a few functions to implement the prediction logic. A Predictor interface is a class that inherits from the base class aiplatform.Predictor , and implements the abstract methods predict() and preprocess() . A Predictor interface can help you create a CPR by defining the preprocessing and prediction logic for your model. A container image is a package that contains the model, the CPR, and the dependencies. A container image can help you standardize and simplify the deployment process, as you only need to upload the container image to Vertex AI Model Registry, and deploy it to Vertex AI Endpoints. By using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint, you can implement the processing st eps so that they run at serving time, minimize code changes and infrastructure maintenance, and deploy the model into production as quickly as possible 1 .
The other options are not as good as option C, for the following reasons:
* Option A: Using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, and deploying it on your organization's GKE cluster would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. FastAPI is a framework for building web applications and APIs in Python. FastAPI can help you implement an HTTP server that can handle prediction requests and responses, and perform data preprocessing and postprocessing. A Docker image is a package that contains the model, the HTTP server, and the dependencies. A Docker image can help you standardize and simplify the deployment process, as you only need to build and run the Docker image. GKE is a service that can create and manage Kubernetes clusters on Google Cloud. GKE can help you deploy and scale your Docker image on Google Cloud, and provide high availability and performance. However, using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, and deploying it on your organization's GKE cluster would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. You would need to write code, create and configure the HTTP server, build and test the Docker image, create and manage the GKE cluster, and deploy and monitor the Docker image. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
* Option B: Using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, uploading the image to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. FastAPI is a framework for building web applications and APIs in Python. FastAPI can help you implement an HTTP server that can handle prediction requests and responses, and perform data preprocessing and postprocessing. A Docker image is a package that contains the model, the HTTP server, and the dependencies. A Docker image can help you standardize and simplify the deployment process, as you only need to build and run the Docker image. Vertex AI Model Registry is a service that can store and manage your machine learning models on Google Cloud. Vertex AI Model Registry can help you upload and organize your Docker image, and track the model versions and metadata. Vertex AI Endpoints is a service that can provide online prediction for your machine learning models on Google Cloud. Vertex AI Endpoints can help you deploy your Docker image to an online prediction endpoint, which can provide low-latency predictions for individual instances. However, using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, uploading the image to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. You would need to write code, create and configure the HTTP server, build and test the Docker image, upload the Docker image to Vertex AI Model Registry, and deploy the Docker image to Vertex AI Endpoints. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
* Option D: Using the XGBoost prebuilt serving container when importing the trained model into Vertex AI, deploying the model to a Vertex AI endpoint, working with the backend engineers to implement the pre- and postprocessing steps in the Golang backend service would not allow you to implement the processing steps so that they run at serving time, and could increase the code changes and infrastructure maintenance. A XGBoost prebuilt serving container is a container image that is provided by Google Cloud, and contains the XGBoost framework and the dependencies. A XGBoost prebuilt serving container can help you deploy a XGBoost model without writing any code, but it also limits your customization options. A XGBoost prebuilt serving container can only handle standard data formats, such as JSON or CSV, and cannot perform any preprocessing or postprocessing on the input or output data. If your input data requires any transformation or normalization before running the prediction, you cannot use a XGBoost prebuilt serving container. A Golang backend service is a service that is implemented in Golang, a programming language that can be used for web development and system programming. A Golang backend service can help you handle the prediction requests and responses from the frontend, and communicate with the Vertex AI endpoint. However, using the XGBoost prebuilt serving container when importing the trained model into Vertex AI, deploying the model to a Vertex AI endpoint, working with the backend engineers to implement the pre- and postprocessing steps in the Golang backend service would not allow you to implement the processing steps so that they run at serving time, and could increase the code changes and infrastructure maintenance. You would need to write code, import the trained model into Vertex AI, deploy the model to a Vertex AI endpoint, implement the pre- and postprocessing steps in the Golang backend service, and test and monitor the Golang backend service. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
References:
Preparing for Google Cloud Certification: Machine Learning Engineer , Course 3: Production ML Systems, Week 2: Serving ML Predictions Google Cloud Professional Machine Learning Engineer Exam Guide , Section 3: Scaling ML models in production, 3.1 Deploying ML models to production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.2: Serving ML Predictions Custom prediction routines Using pre-built containers for prediction Using custom containers for prediction
NEW QUESTION # 319
You work for a bank. You have created a custom model to predict whether a loan application should be flagged for human review. The input features are stored in a BigQuery table. The model is performing well and you plan to deploy it to production. Due to compliance requirements the model must provide explanations for each prediction. You want to add this functionality to your model code with minimal effort and provide explanations that are as accurate as possible What should you do?
Answer: A
Explanation:
The best option for adding explanations to your model code with minimal effort and providing explanations that are as accurate as possible is to upload the custom model to Vertex AI Model Registry and configure feature-based attribution by using sampled Shapley with input baselines. This option allows you to leverage the power and simplicity of Vertex Explainable AI to generate feature attributions for each prediction, and understand how each feature contributes to the model output. Vertex Explainable AI is a service that can help you understand and interpret predictions made by your machine learning models, natively integrated with a number of Google's products and services. Vertex Explainable AI can provide feature-based and example-based explanations to provide better understanding of model decision making. Feature-based explanations are explanations that show how much each feature in the input influenced the prediction.
Feature-based explanations can help you debug and improve model performance, build confidence in the predictions, and understand when and why things go wrong. Vertex Explainable AI supports various feature attribution methods, such as sampled Shapley, integrated gradients, and XRAI. Sampled Shapley is a feature attribution method that is based on the Shapley value, which is a concept from game theory that measures how much each player in a cooperative game contributes to the total payoff. Sampled Shapley approximates the Shapley value for each feature by sampling different subsets of features, and computing the marginal contribution of each feature to the prediction. Sampled Shapley can provide accurate and consistent feature attributions, but it can also be computationally expensive. To reduce the computation cost, you can use input baselines, which are reference inputs that are used to compare with the actual inputs. Input baselines can help you define the starting point or the default state of the features, and calculate the feature attributions relative to the input baselines. By uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines, you can add explanations to your model code with minimal effort and provide explanations that are as accurate as possible1.
The other options are not as good as option C, for the following reasons:
* Option A: Creating an AutoML tabular model by using the BigQuery data with integrated Vertex Explainable AI would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. AutoML tabular is a service that can automatically build and train machine learning models for structured or tabular data. AutoML tabular can use BigQuery as the data source, and provide feature-based explanations by using integrated gradients as the feature attribution method. However, creating an AutoML tabular model by using the BigQuery data with integrated Vertex Explainable AI would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. You would need to create a new AutoML tabular model, import the BigQuery data, configure the model settings, train and evaluate the model, and deploy the model. Moreover, this option would not use your existing custom model, which is already performing well, but create a new model, which may not have the same performance or behavior as your custom model2.
* Option B: Creating a BigQuery ML deep neural network model, and using the ML.EXPLAIN_PREDICT method with the num_integral_steps parameter would not allow you to deploy the model to production, and could provide less accurate explanations than using sampled Shapley with input baselines. BigQuery ML is a service that can create and train machine learning models by using SQL queries on BigQuery. BigQuery ML can create a deep neural network model, which is a type of machine learning model that consists of multiple layers of neurons, and can learn complex patterns and relationships from the data. BigQuery ML can also provide feature-based explanations by using the ML.EXPLAIN_PREDICT method, which is a SQL function that returns the feature attributions for each prediction. The ML.EXPLAIN_PREDICT method uses integrated gradients as the feature attribution method, which is a method that calculates the average gradient of the prediction output with respect to the feature values along the path from the input baseline to the input. The num_integral_steps parameter is a parameter that determines the number of steps along the path from the input baseline to the input. However, creating a BigQuery ML deep neural network model, and using the ML.EXPLAIN_PREDICT method with the num_integral_steps parameter would not allow you to deploy the model to production, and could provide less accurate explanations than using sampled Shapley with input baselines. BigQuery ML does not support deploying the model to Vertex AI Endpoints, which is a service that can provide low-latency predictions for individual instances.
BigQuery ML only supports batch prediction, which is a service that can provide high-throughput predictions for a large batch of instances. Moreover, integrated gradients can provide less accurate and consistent explanations than sampled Shapley, as integrated gradients can be sensitive to the choice of the input baseline and the num_integral_steps parameter3.
* Option D: Updating the custom serving container to include sampled Shapley-based explanations in the prediction outputs would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. A custom serving container is a container image that contains the model, the dependencies, and a web server. A custom serving container can help you customize the prediction behavior of your model, and handle complex or non-standard data formats. However, updating the custom serving container to include sampled Shapley-based explanations in the prediction outputs would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. You would need to write code,
* implement the sampled Shapley algorithm, build and test the container image, and upload and deploy the container image. Moreover, this option would not leverage the power and simplicity of Vertex Explainable AI, which can provide feature-based explanations natively integrated with Vertex AI services4.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Vertex Explainable AI
* AutoML Tables
* BigQuery ML
* Using custom containers for prediction
NEW QUESTION # 320
......
Professional-Machine-Learning-Engineer guide torrent is authoritative. Over the years, our study materials have helped tens of thousands of candidates successfully pass the exam. Professional-Machine-Learning-Engineer certification training is prepared by industry experts based on years of research on the syllabus. These experts are certificate holders who have already passed the certification. They have a keen sense of smell for the test. Therefore, Professional-Machine-Learning-Engineer certification training is the closest material to the real exam questions. With our study materials, you don't have to worry about learning materials that don't match the exam content. With Professional-Machine-Learning-Engineer Study Guide, you only need to spend 20 to 30 hours practicing to take the exam. In addition, Professional-Machine-Learning-Engineer certification training has a dedicated expert who updates all data content on a daily basis and sends the updated content to the customer at the first time. Therefore, using Professional-Machine-Learning-Engineer guide torrent, you don't need to worry about missing any exam focus.
Official Professional-Machine-Learning-Engineer Practice Test: https://www.itexamreview.com/Professional-Machine-Learning-Engineer-exam-dumps.html
BTW, DOWNLOAD part of ITexamReview Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1emd0QMthtlHiCBqEZ5JEjBtkNGowS1u3