P.S. Free & New DP-420 dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=1NcPF93MH71Pahl0kuFM43waI6NnVrnbW
Don't underestimate the difficulty level of the Microsoft DP-420 certification exam because it is not easy to clear. You need to prepare real DP-420 exam questions to get success. If you do not prepare with actual DP-420 Questions, there are chances that you may fail the final and not get the DP-420 certification.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement data models | 35-40% | - Design partitioning strategy
|
| Optimize an Azure Cosmos DB solution | 15-20% | - Optimize query performance
|
| Integrate an Azure Cosmos DB solution | 5-10% | - Integrate with Azure services
|
| Maintain an Azure Cosmos DB solution | 25-30% | - Manage data movement
|
| Design and implement data distribution | 5-10% | - Design replication strategy
|
>> DP-420 Reliable Dumps Pdf <<
All the materials in DP-420 exam torrent can be learned online or offline. You can use your mobile phone, computer or print it out for review. With DP-420 practice test, if you are an office worker, you can study on commute to work, while waiting for customers, and for short breaks after work. If you are a student, DP-420 Quiz guide will also make your study time more flexible. With DP-420 exam torrent, you don't need to think about studying at the time of playing. You can study at any time you want to study and get the best learning results with the best learning status.
NEW QUESTION # 230
Hotspot Question
You have an on-premises network.
You have an Azure subscription that contains an Azure Cosmos DB account named account1 and an Azure virtual network named VNet1. VNet1 contains two virtual machines named VM1 and VM2. VNet1 is connected to the on-premises network by using a Site-to-Site (S2S) VPN.
You need to meet the following requirements:
- Block access to the public endpoint of account1.
- Allow only VM1 to access account1.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.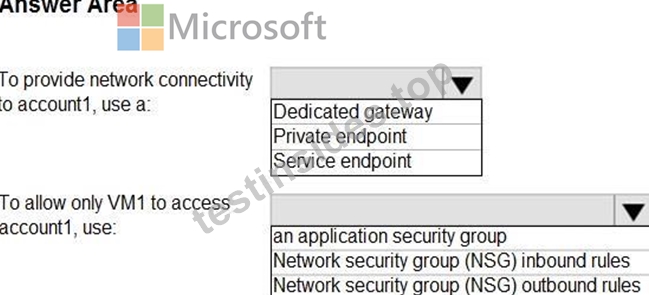
Answer:
Explanation: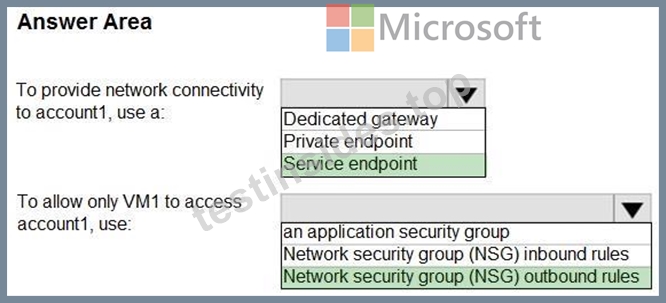
NEW QUESTION # 231
You have a container named container1 in an Azure Cosmos DB Core (SQL) API account.
The following is a sample of a document in container1.
{
"studentId": "631282",
"firstName": "James",
"lastName": "Smith",
"enrollmentYear": 1990,
"isActivelyEnrolled": true,
"address": {
"street": "",
"city": "",
"stateProvince": "",
"postal": "",
}
}
The container1 container has the following indexing policy.
{
"indexingMode": "consistent",
"includePaths": [
{
"path": "/*"
},
{
"path": "/address/city/?"
}
],
"excludePaths": [
{
"path": "/address/*"
},
{
"path": "/firstName/?"
}
]
}
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.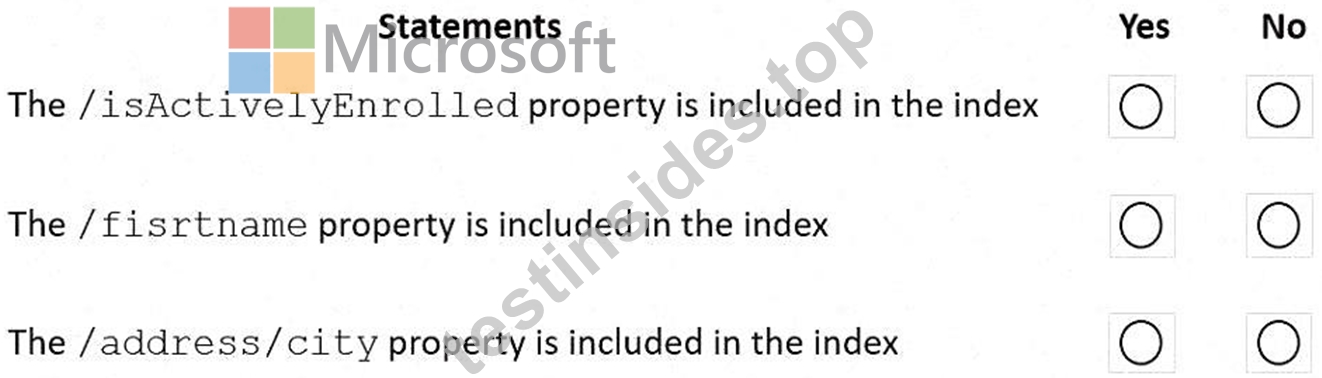
Answer:
Explanation: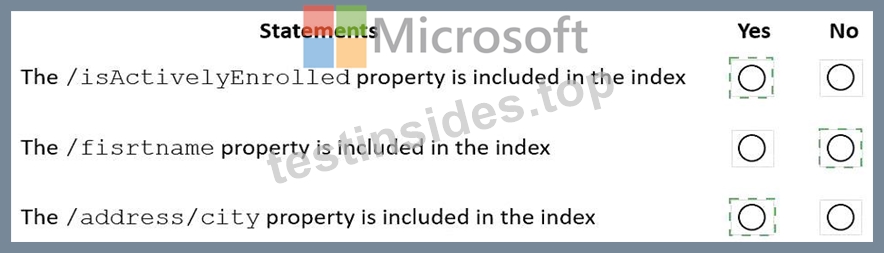
Explanation: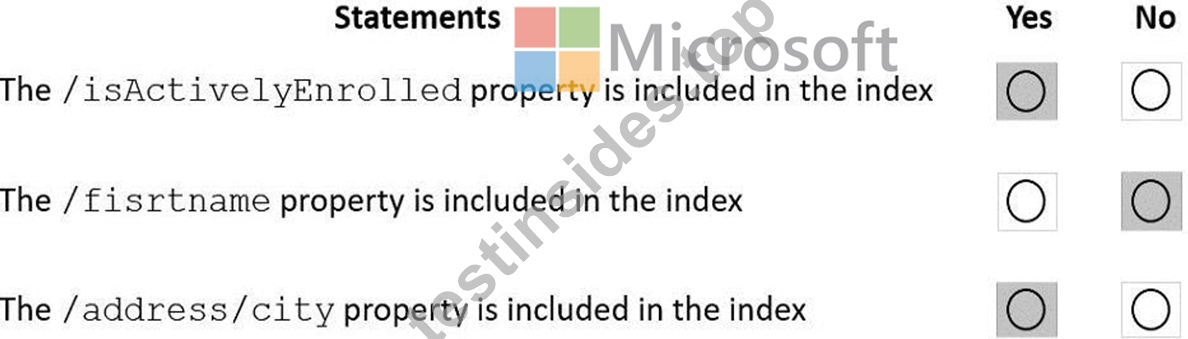
Box 1: Yes
"path": "/*" is in includePaths.
Include the root path to selectively exclude paths that don't need to be indexed. This is the recommended approach as it lets Azure Cosmos DB proactively index any new property that may be added to your model.
Box 2: No
"path": "/firstName/?" is in excludePaths.
Box 3: Yes
"path": "/address/city/?" is in includePaths
Reference: https://docs.microsoft.com/en-us/azure/cosmos-db/index-policy
NEW QUESTION # 232
You need to create a database in an Azure Cosmos DB for NoSQL account. The database will contain three containers named coll1, coll2 and coll3. The coll1 container will have unpredictable read and write volumes.
The col!2 and coll3 containers will have predictable read and write volumes. The expected maximum throughput for coll1 and coll2 is 50,000 request units per second (RU/s) each.
How should you provision the collection while minimizing costs?
Answer: B
Explanation:
Explanation
Azure Cosmos DB offers two different capacity modes: provisioned throughput and serverless1. Provisioned throughput mode allows you to configure a certain amount of throughput (expressed in Request Units per second or RU/s) that is provisioned on your databases and containers. You get billed for the amount of throughput you've provisioned, regardless of how many RUs were consumed1. Serverless mode allows you to run your database operations without having to configure any previously provisioned capacity. You get billed for the number of RUs that were consumed by your database operations and the storage consumed by your data1.
To create a database that minimizes costs, you should consider the following factors:
* The read and write volumes of your containers
* The predictability and variability of your traffic
* The latency and throughput requirements of your application
* The geo-distribution and availability needs of your data
Based on these factors, one possible option that you could choose is B. Create a provisioned throughput account. Set the throughput for coll1 to Autoscale. Set the throughput for coll2 and coll3 to Manual.
This option has the following advantages:
* It allows you to handle unpredictable read and write volumes for coll1 by using Autoscale, which automatically adjusts the provisioned throughput based on the current load1.
* It allows you to handle predictable read and write volumes for coll2 and coll3 by using Manual, which lets you specify a fixed amount of provisioned throughput that meets your performance needs1.
* It allows you to optimize your costs by paying only for the throughput you need for each container1.
* It allows you to enable geo-distribution for your account if you need to replicate your data across multiple regions1.
This option also has some limitations, such as:
* It may not be suitable for scenarios where all containers have intermittent or bursty traffic that is hard to forecast or has a low average-to-peak ratio1.
* It may not be optimal for scenarios where all containers have low or sporadic traffic that does not justify provisioned capacity1.
* It may not support availability zones or multi-master replication for your account1.
Depending on your specific use case and requirements, you may need to choose a different option. For example, you could use a serverless account if all containers have low or sporadic traffic that does not require predictable performance or geo-distribution1. Alternatively, you could use a provisioned throughput account with Manual for all containers if all containers have stable and consistent traffic that requires predictable performance or geo-distribution1.
NEW QUESTION # 233
You have an Azure Cosmos DB for NoSQL database named DB1 that hosts the containers shown in the following table.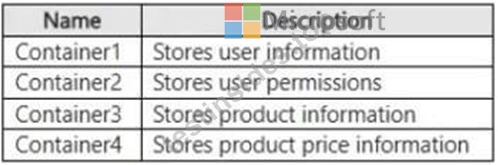
The user permissions are bound to a user and will NOT be queried independently of the user.
The product price is bound to a product and will NOT be queried independently of the product.
You are designing a new data model for DB1.
You need to optimize the data model to improve read performance and maintainability. The solution must meet the following requirements:
- Future enhancements of the user permissions must be supported.
- Future enhancements of the product price do NOT need to be supported.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,F
Explanation:
To improve read performance and maintainability, you must transition from a normalized relational design to an optimized NoSQL design. NoSQL databases prioritize reading data in a single request rather than joining multiple containers.
Container Denormalization Strategy
[B]
Product Data (Container3 and Container4)
Action: Denormalize Container4 into Container3 by flattening the fields.
Product prices are never queried independently. Combining them allows a single read operation to fetch the complete product details.
Maintainability: Since future price enhancements are not required, you can directly flatten the price fields (e.g., price, currency) into the root of the product document. This keeps the schema simple and highly efficient.
[C]
User Data (Container1 and Container2)
Action: Denormalize Container2 into Container1 using reference (embedding as an array).
Users and permissions are always queried together. Embedding eliminates a second network call, drastically improving read performance.
Maintainability: Because future enhancements to permissions must be supported, embedding them as a strongly-typed JSON array or sub-object within the user document allows you to easily add new fields (e.g., expiration dates, scopes) later without breaking the schema.
Reference:
https://microsoftlearning.github.io/dp-420-cosmos-db-dev/instructions/17-denormalize.html
NEW QUESTION # 234
You have an Apache Spark pool in Azure Synapse Analytics that runs the following Python code in a notebook.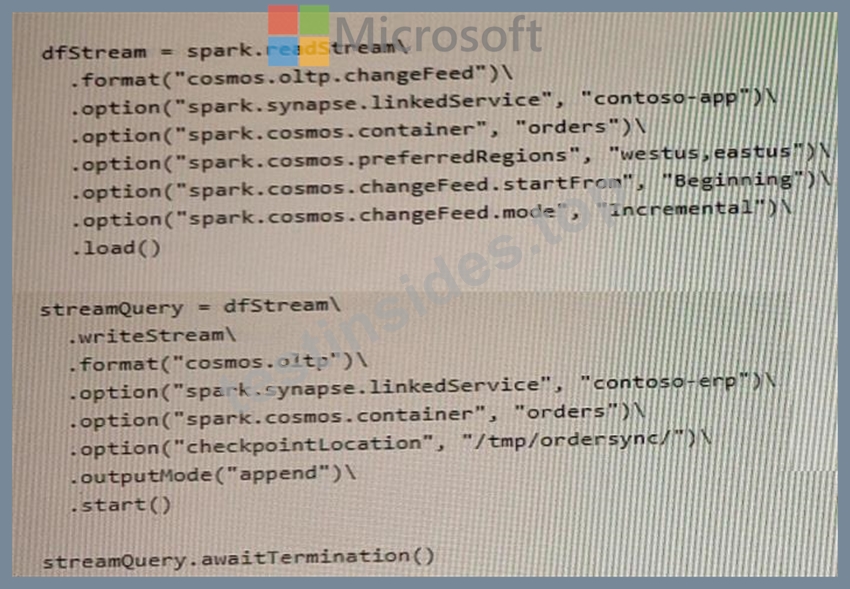
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.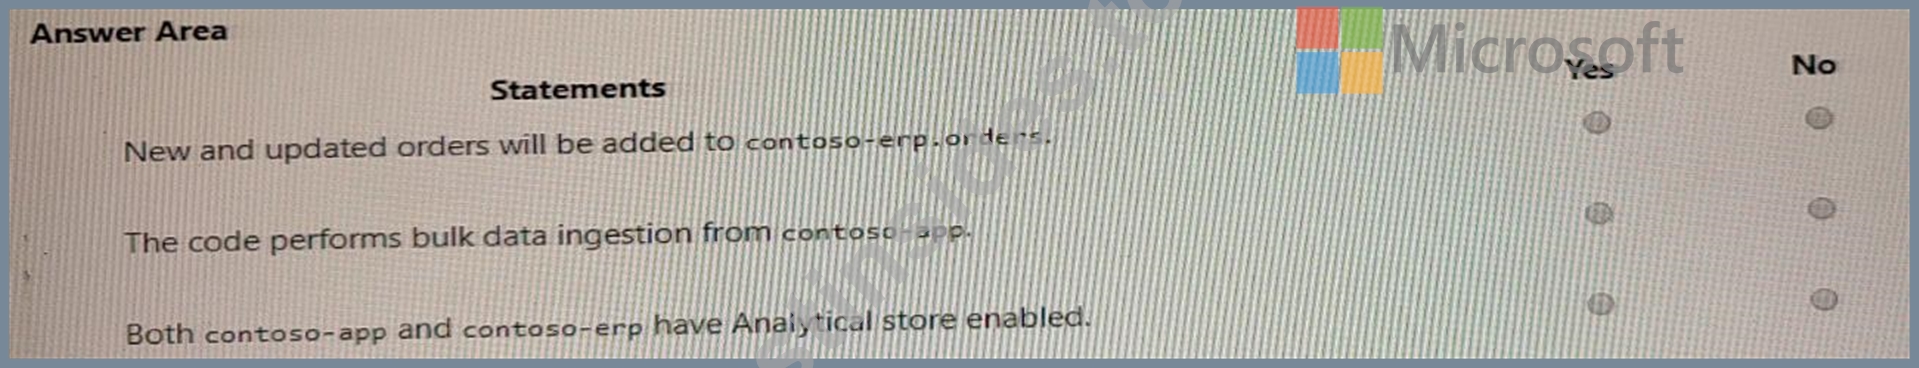
Answer:
Explanation: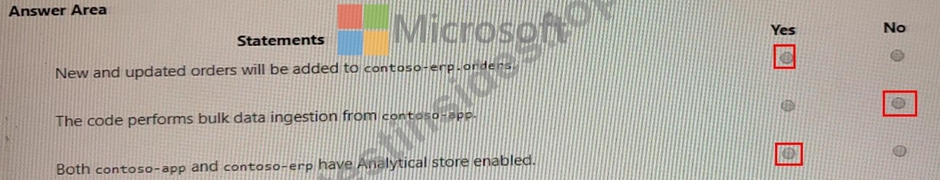
NEW QUESTION # 235
......
We have a large number of regular customers exceedingly trust our Designing and Implementing Cloud-Native Applications Using Microsoft Azure Cosmos DB practice materials for their precise content about the exam. You may previously have thought preparing for the DP-420 practice exam will be full of agony, actually, you can abandon the time-consuming thought from now on. Our practice materials can be understood with precise content for your information, which will remedy your previous faults and wrong thinking of knowledge needed in this exam. As a result, many customers get manifest improvement and lighten their load by using our DP-420 practice materials. Up to now, more than 98 percent of buyers of our practice materials have passed it successfully. DP-420 practice materials can be classified into three versions: the pdf, the software and the app version. So we give emphasis on your goals, and higher quality of our DP-420 practice materials.
Simulated DP-420 Test: https://www.testinsides.top/DP-420-dumps-review.html
P.S. Free 2026 Microsoft DP-420 dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=1NcPF93MH71Pahl0kuFM43waI6NnVrnbW