With our wide range of Databricks Databricks-Certified-Professional-Data-Engineer exam questions types and difficulty levels, you can tailor your Databricks Databricks-Certified-Professional-Data-Engineer exam practice to your needs. Your performance and exam skills will be improved with our Databricks Databricks-Certified-Professional-Data-Engineer Practice Test software. The software provides you with a range of Databricks Databricks-Certified-Professional-Data-Engineer exam dumps, all of which are based on past Databricks Databricks-Certified-Professional-Data-Engineer certifications.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Governance | 7% | - Unity Catalog management - Policy enforcement - Data lineage and metadata tracking |
| Topic 2: Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Topic 3: Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Topic 4: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
| Topic 5: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Topic 6: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching - Cluster configuration and scaling |
| Topic 7: Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Topic 9: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
>> Databricks-Certified-Professional-Data-Engineer Actual Test Pdf <<
Our product boosts varied functions to be convenient for you to master the Databricks-Certified-Professional-Data-Engineer training materials and get a good preparation for the exam and they include the self-learning function, the self-assessment function, the function to stimulate the exam and the timing function. We provide 24-hours online on Databricks-Certified-Professional-Data-Engineer Guide prep customer service and the long-distance professional personnel assistance to for the client. If clients have any problems about our Databricks-Certified-Professional-Data-Engineer study materials they can contact our customer service at any time.
NEW QUESTION # 52
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: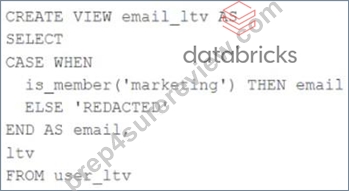
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Answer: C
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 53
You are currently working to ingest millions of files that get uploaded to the cloud object storage for consumption, and you are asked to build a process to ingest this data, the schema of the file is expected to change over time, and the ingestion process should be able to handle these changes automatically. Which of the following method can be used to ingest the data incrementally?
Answer: C
Explanation:
Explanation
The answer is AUTO LOADER,
Use Auto Loader instead of the COPY INTO SQL command when:
*You want to load data from a file location that contains files in the order of millions or higher. Auto Loader can discover files more efficiently than the COPY INTO SQL command and can split file processing into multiple batches.
*COPY INTO only directory listing but AUTO LOADER supports File notification method where the Auto Loader continues to ingest files as they arrive in cloud object storage lever-aging cloud provider(Queues and triggers) and Spark's structured streaming.
*Your data schema evolves frequently. Auto Loader provides better support for schema in-ference and evolution. See Configuring schema inference and evolution in Auto Loader.
NEW QUESTION # 54
The following code has been migrated to a Databricks notebook from a legacy workload: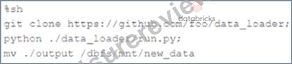
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
Answer: A
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 55
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Answer: D
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under
"CREATE VIEW" section.
NEW QUESTION # 56
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
Answer: A
Explanation:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file-based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file. Verified Reference: [Databricks Certified Data Engineer Professional], under "Spark Configuration" section; Databricks Documentation, under "Available Properties - spark.sql.files.maxPartitionBytes" section.
NEW QUESTION # 57
......
There are only key points in our Databricks-Certified-Professional-Data-Engineer Training Materials. From the experience of our former customers, you can finish practicing all the contents in our training materials within 20 to 30 hours, which is enough for you to pass the Databricks-Certified-Professional-Data-Engineer exam as well as get the related certification. That is to say, you can pass the Databricks Certified Professional Data Engineer Exam exam as well as getting the related certification only with the minimum of time and efforts under the guidance of our training materials. So what you are waiting for? Just come and buy them!
Valid Dumps Databricks-Certified-Professional-Data-Engineer Files: https://www.prep4surereview.com/Databricks-Certified-Professional-Data-Engineer-latest-braindumps.html